Tencent Study Finds Domain Skills Scattered Across Neurons Inside MoE Experts
A new Tencent paper finds that domain skills such as math and coding in Mixture-of-Experts models are not concentrated in individual experts but scattered across sparse neurons spanning multiple experts. Neuron-level pruning scored by routed contribution (RAMP) retains 91%-98% of performance with 75% of neurons kept; at 50% retention, GPU memory drops 36%-43% and batched prefill throughput rises 17%-39%, offering an alternative to whole-expert pruning for MoE compression.
Related Entities
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-11-13 16
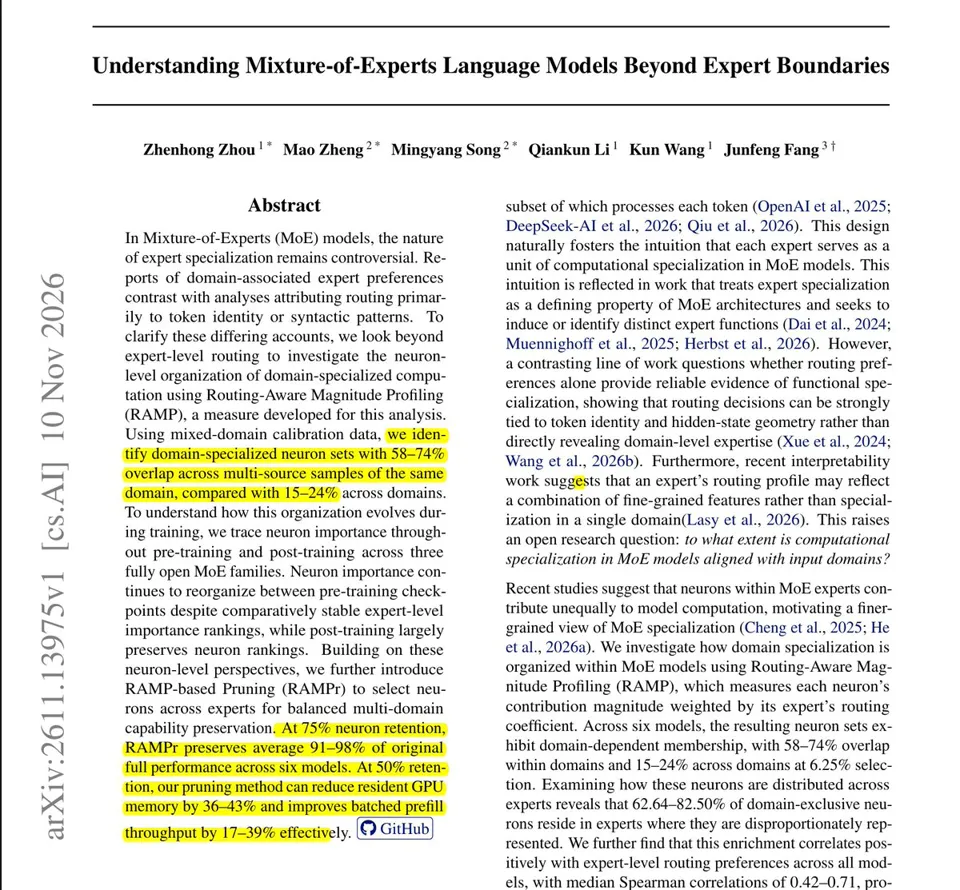
New Tencent paper shows domain skills (like math or coding ) in Mixture of Experts models sit in scattered neurons across expert.
so cutting weak neurons instead of whole experts shrinks the models while keeping most skills.
In their experiment, Mixture of Experts AI models kept 91% to 98% of their performance after their least useful 25% of expert neurons were cut.
MoE models send each token to a few experts, which suggests each expert handles a domain like math or code. Other work finds routing mostly tracks token type instead.
They scored each neuron's routed contribution with a measure called RAMP. Neurons picked for one domain overlapped 58% to 74% across samples of that domain, versus 15% to 24% across domains, and sat in mixed experts.
RAMPr prunes by these scores across all experts and kept 91% to 98% of original performance with 75% of neurons left, across 6 models. With 50% left, GPU memory fell 36% to 43% and batched prefill throughput rose 17% to 39%.
If you compress MoE models, prune neurons inside experts by their routed contribution instead of treating each expert as a single unit.