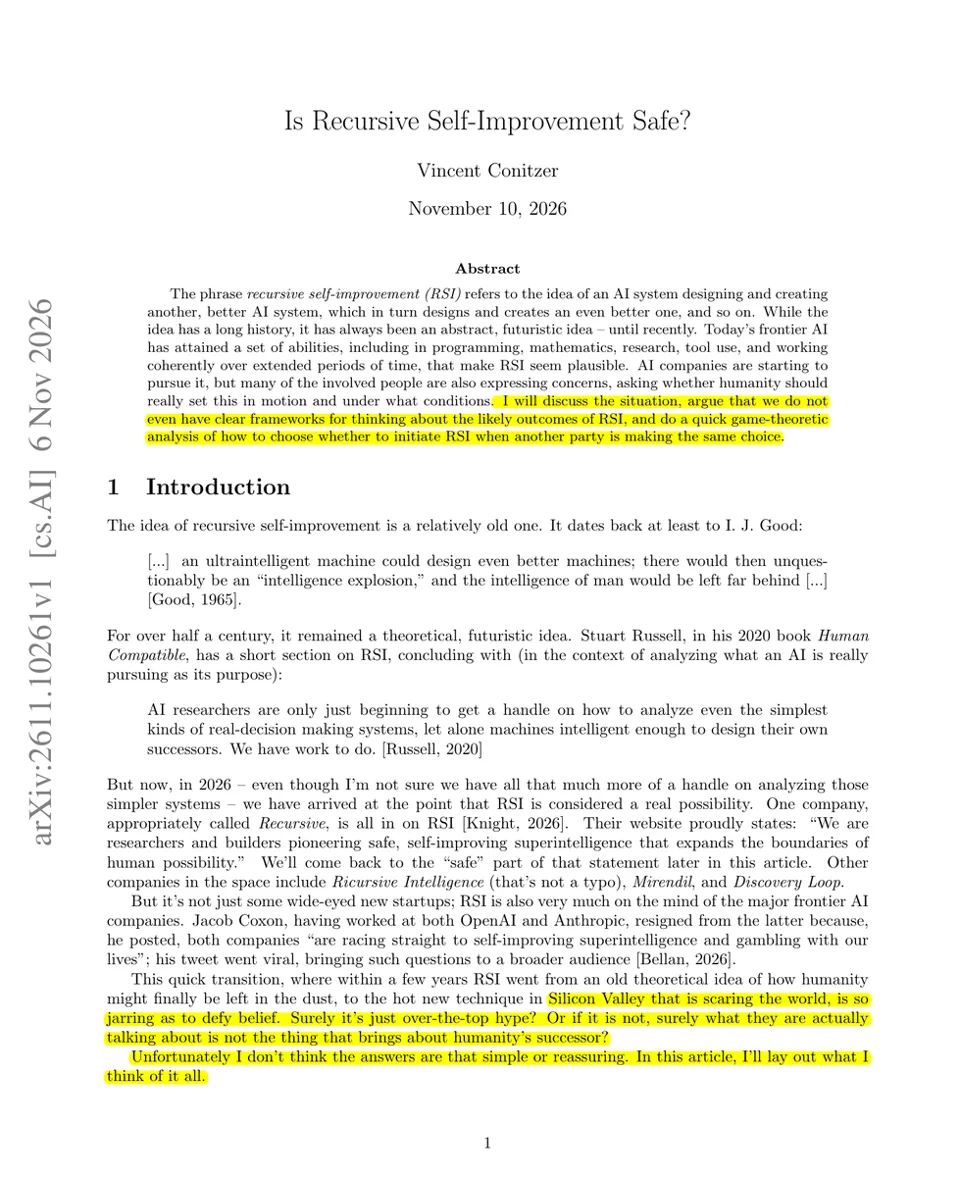
Paper Argues Recursive Self-Improvement Safety Lacks Any Evaluation Framework
A paper argues that recursive self-improvement (RSI) is being pursued by AI companies without any shared view of when it would be safe, and without even a clear framework for reasoning about where it leads. The author also demonstrates that a single high-level prompt can get an AI to train a small LLM from scratch, underscoring how fast the capability barrier is falling.
Related Entities
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-11-10 23
This paper argues that no one can call recursive self-improvement safe yet, because we lack even a clear way to think about where it leads.
Recursive self-improvement, or RSI, means an AI builds a better AI, which builds a better one, and so on. AI companies are starting to pursue it, with no shared view of when it would be safe.
As an ordinary user, the author got an AI to train a small LLM from scratch from 1 high-level prompt. At a