Artificial Analysis · 10/15/2026, 08:00:00
NVIDIA Releases Nemotron 3.5 Super VL: Tops US Open-Weight Models with Near-Lossless NVFP4 Quantization
NVIDIA released Nemotron 3.5 Super VL, scoring 26.5 on the Artificial Analysis Intelligence Index to become the leading US open-weight model, surpassing competitors from Thinking Machines and Meta. The model doubles its predecessor's intelligence while reducing output tokens per task by ~60%, maintaining near-lossless accuracy in NVFP4 quantization (within 0.1 points of BF16). Concurrently, the new Bolt 74B-A9B achieves performance close to the flagship Ultra model with significantly fewer parameters.
SOURCE COVERAGEFull Original Report
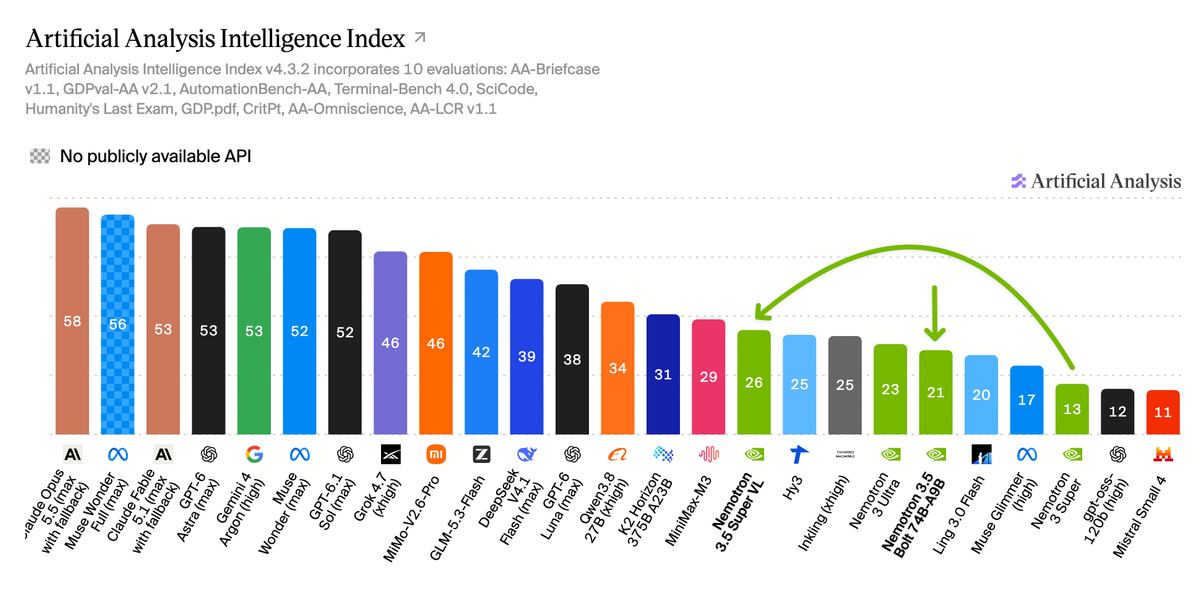
Nvidia’s Nemotron 3.5 Super VL is now the leading US open weight model, scoring 26 on the Artificial Analysis Intelligence Index
Nemotron 3.5 Super VL achieves twice the intelligence of its predecessor, Nemotron 3 Super (13), and does so using ~60% fewer output tokens per task
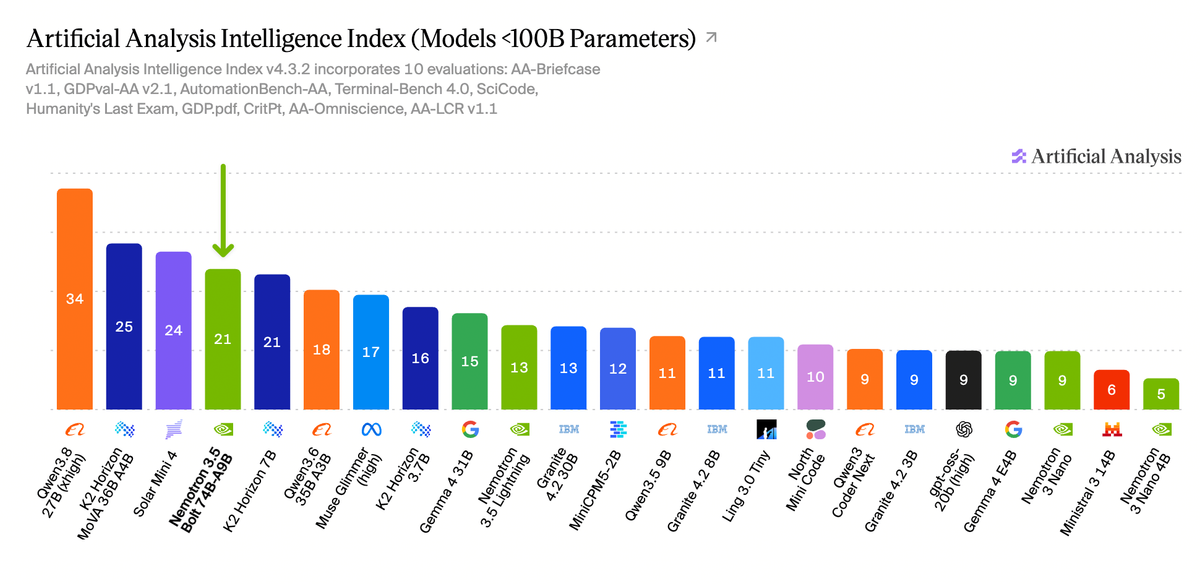
It launches alongside Nemotron 3.5 Bolt 74B-A9B, the first model in its new Bolt family, which scores 21 on the Intelligence Index
Key Takeaways:
➤ Leading US open weight model: Nemotron 3.5 Super VL scores 26.5, edging out Thinking Machines' Inkling Small (25.7) and ahead of NVIDIA's Nemotron 3 Ultra (23) and Meta's Muse Glimmer (17)
➤ Bolt comes within 2 points of Ultra: Nemotron 3.5 Bolt 74B-A9B scores 21, 1.5 points behind Nemotron 3 Ultra 550B A55B (23). It has about a seventh of Ultra's total parameters (74B vs 550B) and a sixth of its active parameters (9B vs 55B)
➤ Super 3.5 near lossless in NVFP4: Nemotron 3.5 Super VL releases in NVFP4, scoring within 0.1 points of its BF16 weights on the Intelligence Index, with no component moving by more than 2.6 points
Nemotron 3.5 Super VL details
- Context window: 1M tokens
- Modalities: Vision and text input; text output
- Parameters: 120B / 12B
Nemotron 3.5 Bolt 74B-A9B details
- Context window: 256k tokens
- Modalities: Vision and text input; text output
- Parameters: 74B / 9B
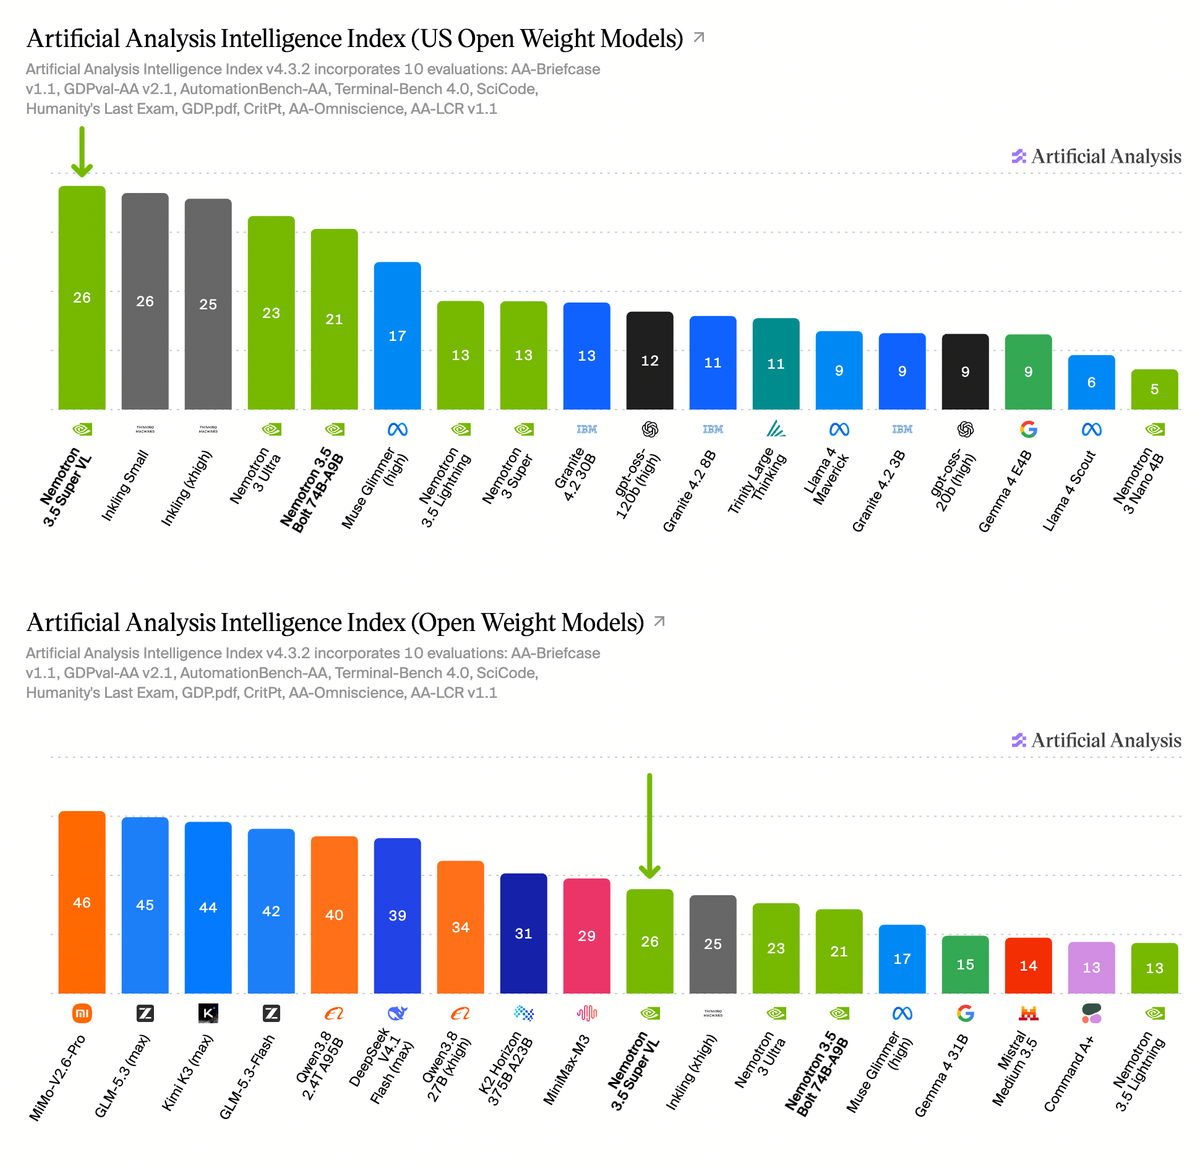
Nemotron 3.5 Super - US Open Weight Leader
Nemotron 3.5 Super VL is the highest-scoring open weights model from the US, at 26 on the Intelligence Index. It edges out Thinking Machines' Inkling Small (26) and passes NVIDIA's previous flagship, Nemotron 3 Ultra (23), and Meta's Muse Glimmer (17)
Despite the advance, the US still trails the United Arab Emirates (K2 Horizon 375B A23B, 31) and China (MiMo-V2.6-Pro, 46) on open weights intelligence.
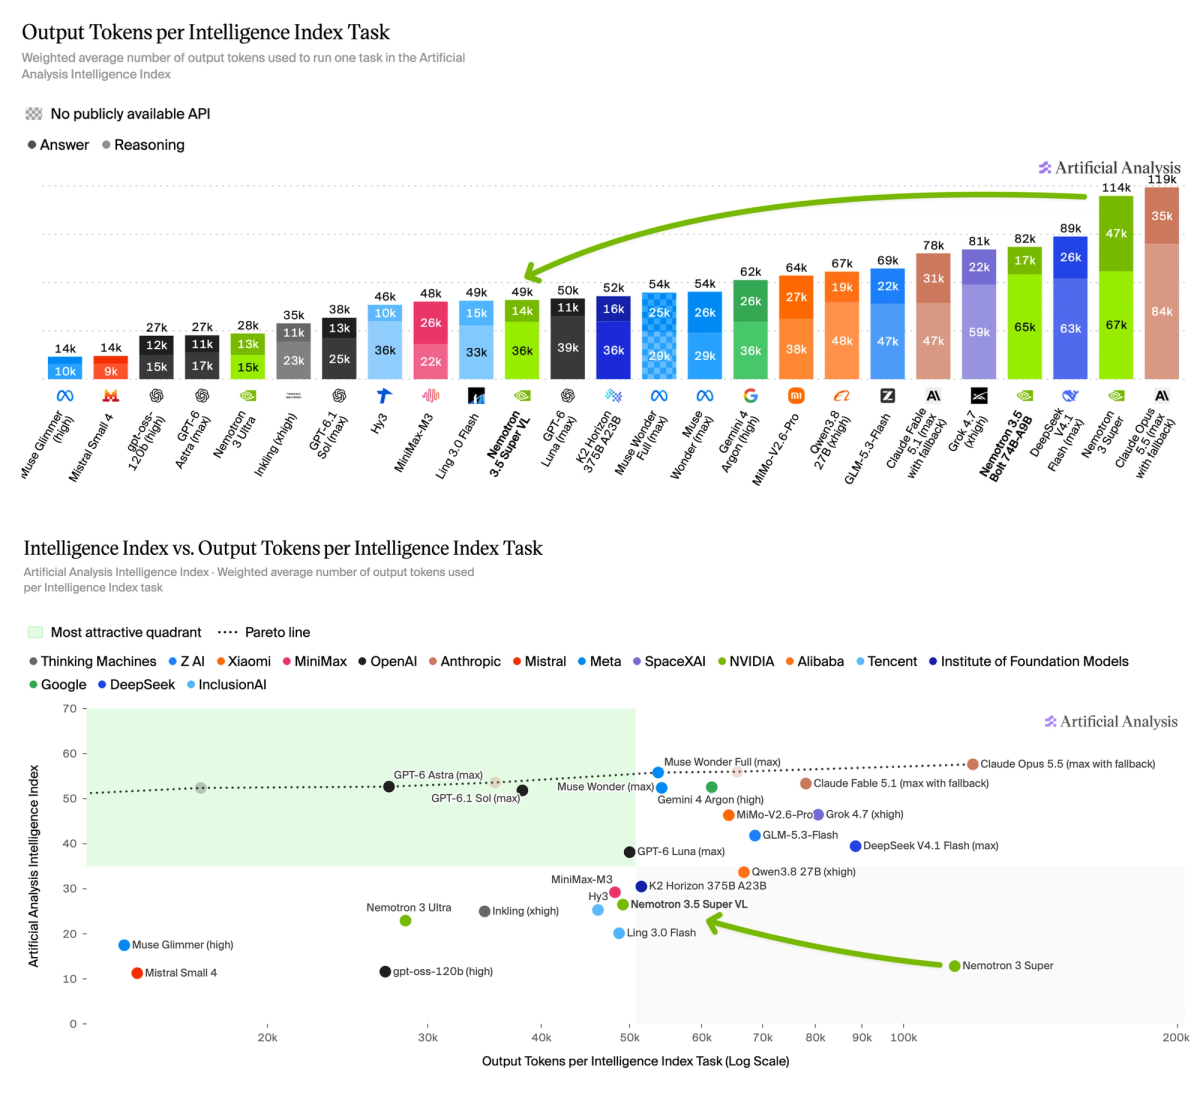
Nemotron 3.5 Super - Token Usage
Nemotron 3.5 Super VL uses 46k output tokens per Intelligence Index task, ~60% fewer than its predecessor Nemotron 3 Super (114k) and fewer than K2 Horizon 375B A23B (52k) and MiMo-V2.6-Pro (64k)
Despite a clear increase in token efficiency, Nemotron 3.5 Super still falls a way behind the Intelligence Index vs. Output Tokens per Task frontier
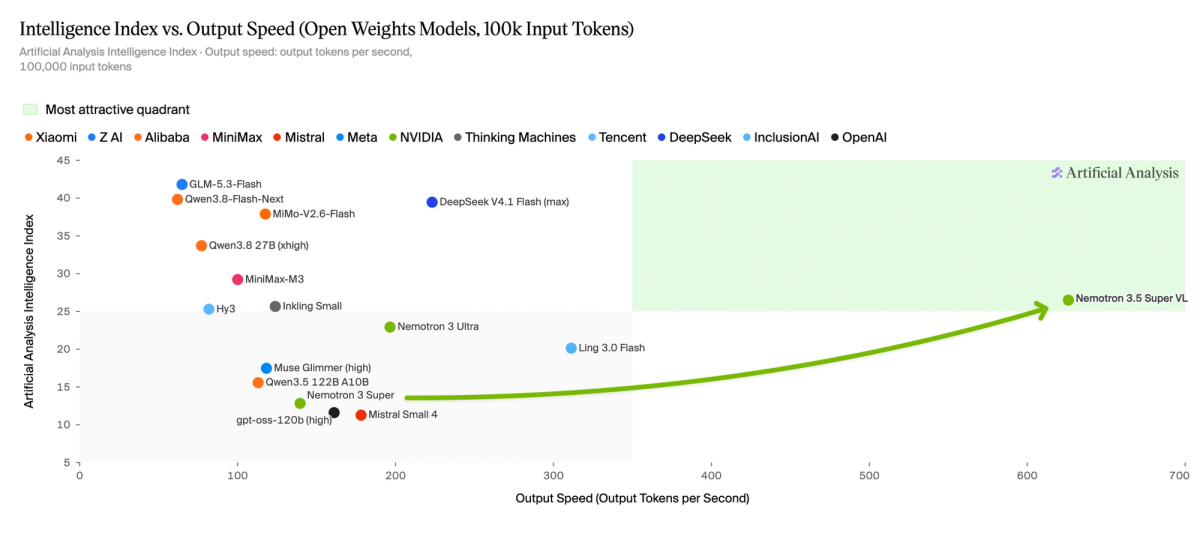
Nemotron 3.5 Super - Output Speed
Measured on a pre-release @DeepInfra endpoint serving NVFP4 weights, Nemotron 3.5 Super VL reaches an output speed of ~630 tokens/s with 100k-token prompts. That is the fastest of any model scoring 20 or more on the Intelligence Index that we have measured at this prompt length
That is ~5x Inkling Small (124 tokens/s), ~2.7x Nemotron 3 Ultra (235), and ~4.5x Nemotron 3 Super (140). It also returns its first token in 1.8s, against 4.4s for Nemotron 3 Ultra and 8.5s for Inkling Small
Nemotron 3.5 Bolt
Nemotron 3.5 Bolt 74B-A9B is the first model in NVIDIA's new Bolt family. It scores 21.4 on the Intelligence Index, placing 4th among models under 100B parameters and first among US models in that class
Bolt scores 8.6 points above Nemotron 3 Super (12.8) with 39% fewer total parameters. Against Nemotron 3 Ultra, it leads on AutomationBench-AA (15.5% vs 3.0%) and AA-Briefcase (912 vs 874 Elo), but trails on AA-LCR (70% vs 79%) and Humanity's Last Exam (25% vs 28%)
Nemotron 3.5 Bolt - Token Usage
Nemotron 3.5 Bolt 74B-A9B uses 82k output tokens per Intelligence Index task, 1.8x Nemotron 3.5 Super VL (46k) and 2.9x Nemotron 3 Ultra (28k), though still 28% fewer than Nemotron 3 Super (114k)