Meta Launches Muse Ember Efficient Model at $0.14 per Task
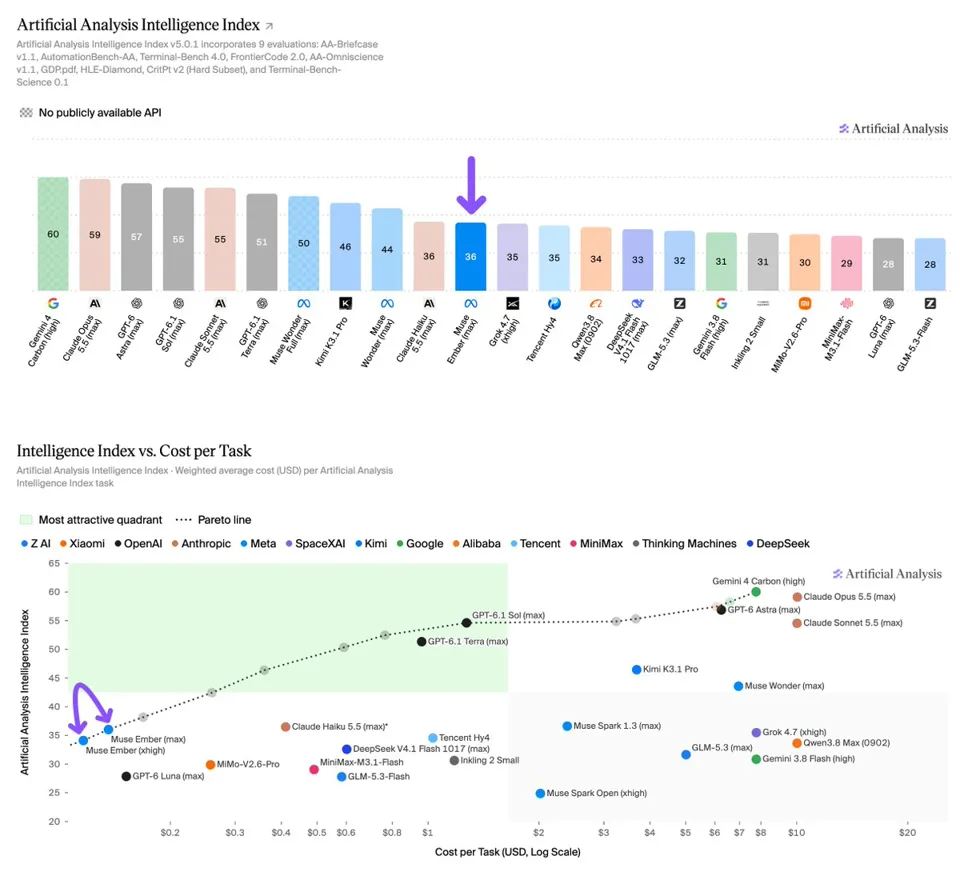
Meta has launched Muse Ember, a new efficiency-tier model line that scores 36 on the Artificial Analysis Intelligence Index, matching Claude Haiku 5.5 at roughly one-third the cost per task ($0.14 vs $0.41). It reaches 68.1% on AutomationBench-AA, level with Meta's flagship Muse Wonder, though results are mixed on agentic coding and other benchmarks.
Related Entities
Full Report
Artificial Analysis (@ArtificialAnlys) · 2026-11-09 18
Meta's newest model Muse Ember scores 36 on the Artificial Analysis Intelligence Index, matching Claude Haiku 5.5 (max) at a third of the Cost per Task
Muse Ember is Meta's newest efficient-tier model line, with the same input and output token prices as Claude Haiku 5.5 and GPT-6 Luna
Key Takeaways:
➤ On the Intelligence Index vs. Cost per Task Pareto frontier at both max and xhigh effort. Muse Ember (max) is the cheapest model scoring 36 or higher, at $0.14 per task, and Muse Ember (xhigh) scores 34 for $0.12. Claude Haiku 5.5 (max) costs almost 3x more at $0.41 for the same score as Muse Ember (max). Muse Ember (max) is also about 4x cheaper than DeepSeek V4.1 Flash 1017 (max, 33, 0.58)
➤ 8 points behind Muse Wonder for about 1/50th of the Cost per Task. Muse Wonder (max) scores 44 at $6.95 per Intelligence Index task
➤ Stands out on AutomationBench-AA. Muse Ember (max) scores 68.1% on AutomationBench-AA, level with Muse Wonder (max), and beats Claude Haiku 5.5 (max) on GDP.pdf (22.8% vs 20.8%), but trails it on AA-Briefcase (1521 vs 1574 Elo)
➤ Mixed in agentic coding in our Intelligence Index evaluations. It beats Claude Haiku 5.5 (max) on Terminal-Bench 4.0 (40.9% vs 32.8%) but trails it on FrontierCode 2.0 (27.2% vs 34.9%)
➤ Ahead of similarly priced models when running in its own coding agent. In Muse Code, Muse Ember (max) scores 46 on the Artificial Analysis Coding Agent Index, ahead of Claude Haiku 5.5 in Claude Code (max, 37) and GPT-6 Luna in Codex (max, 31)
➤ Knowledge is the main weakness, but it rarely hallucinates. Its AA-Omniscience accuracy of 21.1% is the lowest of the similarly intelligent models we compared, against 34.7% for Claude Haiku 5.5 (max) and 50.5% for Gemini 3.8 Flash (high). This is mostly because it declines to answer 64% of questions, which keeps its hallucination rate at 17.4%, half of Claude Haiku 5.5’s (max)
Other details: ➤ Pricing: 0.004 cached input / $0.50 output per 1M tokens ➤ Reasoning effort: results shown at max effort, with xhigh also on the Intelligence vs. Cost chart ➤ Availability: Meta's first-party API and Muse Code