Anthropic's Three Internal Models Leaked, Top Model 4 Surpasses Opus 5.5 on Capability Index
Third-party evaluator METR disclosed three unreleased Anthropic internal models, Model 2/3/4, trained between July and October this year. The strongest, Model 4, scores 178.6 on Anthropic's AECI capability index, roughly 3.9 points above Opus 5.5 released six weeks earlier—equivalent to about three months of normal progress. Co-founder Sam McCandlish acknowledged AI is accelerating Anthropic's own R&D, while noting the public report omits substantial detail.
Full Report
Dario just called for slowing down…
Tingyu, reporting from the Non-Obvious Temple QbitAI | WeChat Official Account QbitAI
Three mysterious internal models from Anthropic have been exposed.
Model 2, Model 3, Model 4.
Their real names haven't been made public yet, but their training timelines and some benchmark results have already surfaced.
A new report from third-party evaluator METR discloses that the three models finished training in July, August–September, and September–October of this year, respectively.
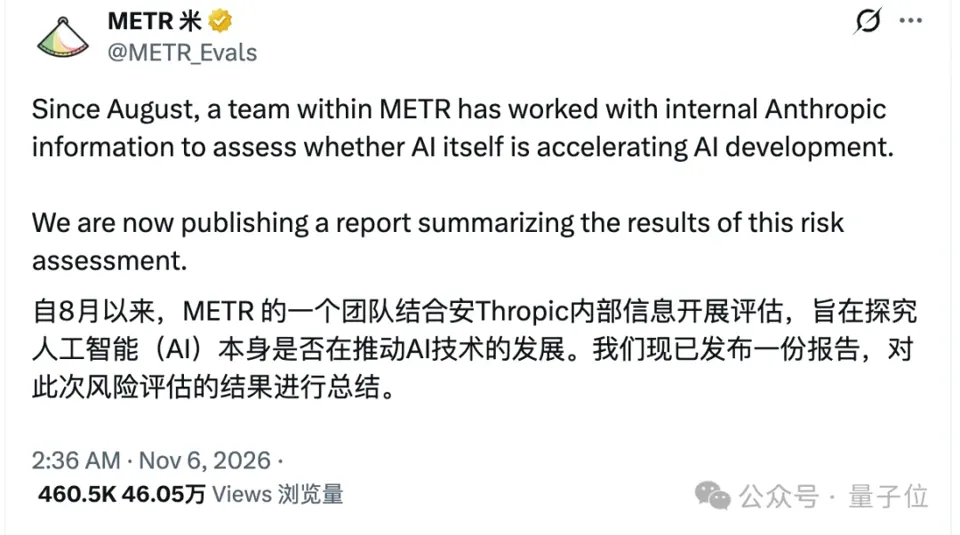
Among them, the strongest one, Model 4, has already surpassed Opus5.5 on Anthropic's comprehensive capability index, AECI.
Anthropic co-founder Sam McCandlish also responded publicly.
He agreed with several of the report's judgments: AI is accelerating Anthropic's R&D—it's just hard to measure precisely by how much.
(So Anthropic's founder is also named Sam.)
In addition, Sam acknowledged that the public report has had a large amount of information removed.
He knows this will make it harder for outsiders to verify METR's analysis. But in his view, disclosing the details behind the R&D acceleration involves commercially sensitive information and could also hand other companies an "acceleration roadmap."
The three internal models: what's their story?
How large is the capability gap between these three models?
The AECI curve disclosed in the METR report provides an intuitive reference.
AECI is Anthropic's version of the Epoch capability index, which aggregates results across multiple internal and external benchmarks to track how model capability changes over time.

△AECI score trends for Anthropic models; orange dots represent internal models, green dots represent public models
As the chart shows, Model 2's score is close to Opus5.5's, while Model 3 and Model 4 are higher.
Among them, Model 4 reaches an AECI of 178.6, the highest in this group and about 3.9 points above Opus5.5.
So what does 3.9 points represent?
Converted at Anthropic's past rate of capability improvement, it's roughly equivalent to 3 months of progress.
And when was Opus 5.5 released? A month and a half ago.
Looking at the overall trend, METR estimates that since October 2025, Anthropic models' AECI scores have been growing at about 1.9 times the previous rate—nearly double.
Model 4 has another distinction: it exceeds 50% on all 15 benchmarks included in its AECI evaluation.
By comparison, about nine months earlier, Opus4.6 still scored below 50% on quite a few benchmarks.
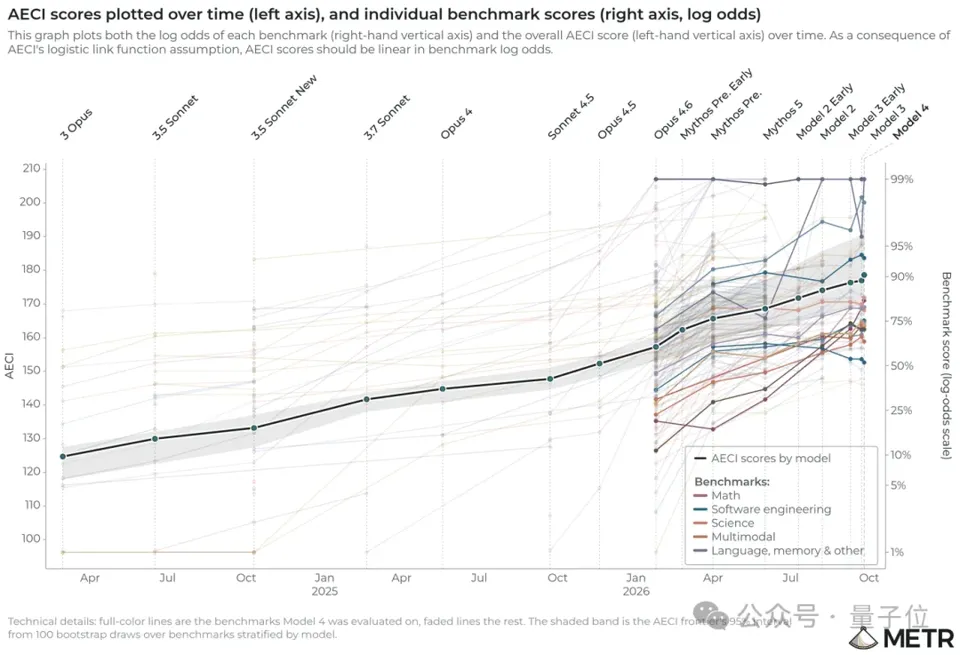
△The highlighted curves represent the 15 benchmarks included in Model 4's evaluation, all scoring above 50%
That's astonishingly fast progress…
This has also led METR to worry that high-difficulty tests capable of fully challenging these models are running out, and that measuring capability will only get harder going forward.
Well, METR needn't worry—benchmarks getting saturated is far too common now, and everyone shares that concern.
On Anthropic's side, co-founder Sam McCandlish also responded publicly.
He agreed with several of the report's judgments: AI is accelerating Anthropic's R&D, but precisely how much is hard to measure.
According to Sam, Anthropic provided METR with benchmark results for unreleased models, estimates of model progress, and opportunities to speak with researchers, allowing evaluators to form independent conclusions.
He also acknowledged that Anthropic removed a large amount of information from this report, making it harder for others to verify METR's analysis.
He also previewed that in the coming weeks, Anthropic will publish its own progress analysis~
It will explain the pace of internal AI R&D, where the company stands relative to its Responsible Scaling Policy, and what new safety measures it plans to adopt.
After Claude's self-evolution, the next-generation models are arriving faster
Claude has already started helping build its own next generation.
In September of this year, Anthropic disclosed a set of figures:
As of August, Claude had led 26% of model R&D work under human supervision. Half a year earlier, that share was still under 1%.
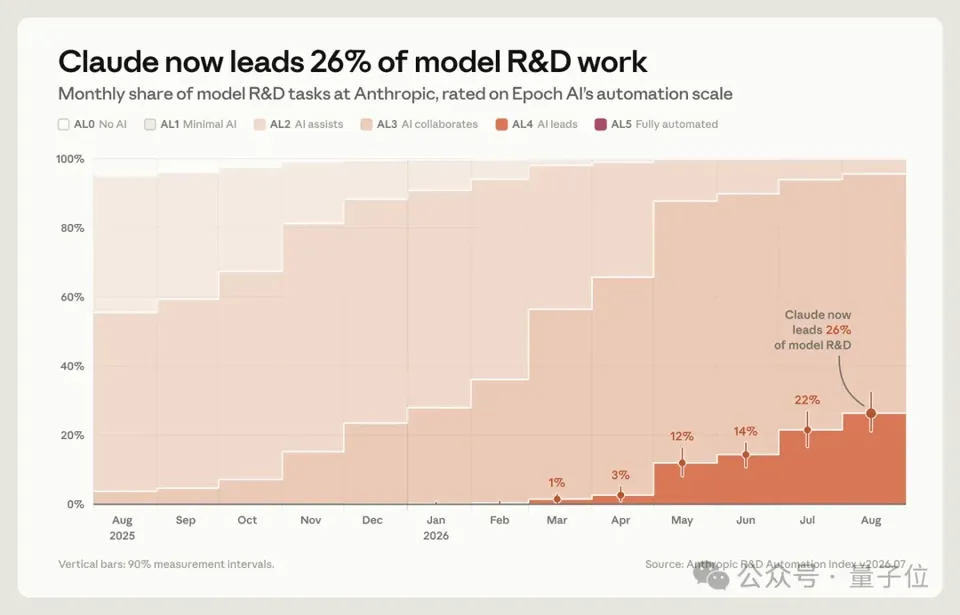
The newly released METR report also includes interview excerpts from several Anthropic researchers, discussing how AI is changing their R&D work.
One interviewed researcher said the time from generating an idea to running an experiment has dropped by about 80%.
In his experience, code is no longer the main bottleneck—what actually holds back progress is ideas and compute.
Another researcher mentioned that with Claude and agent tools, teams can try more ideas simultaneously and even discover directions they wouldn't have invested effort in exploring before.
Their accounts share a common thread: Claude helps researchers turn ideas into experiments faster, giving R&D teams the chance to try more approaches.
Following this path, even stronger models could become assistants for the next round of R&D, continuing to drive further model progress.
METR also leans toward the view that widespread AI use accounts for most of Anthropic's current R&D acceleration.
But it also emphasizes that at this stage, the acceleration mainly comes from AI assisting human researchers; fully autonomous AI R&D has not yet become the main source of overall progress.
In September of this year, Dario also wrote a dedicated article calling for everyone to collectively slow down:
We must slow down the pace of improving AI model capabilities.
Dario probably saw some signs internally…
By his judgment, AI progress has clearly accelerated since around this summer, driven mainly by AI's growing ability to help develop the next generation of AI.
He also worries that this process could become so fast that it outstrips humanity's ability to understand and control these systems.
However, "talking up the brakes while stepping on the gas" is an old trick of Anthropic's...
Internal models are being exposed one after another, with no sign of slowing down at all 😓
As everyone knows, Dario has always been someone who places particular emphasis on safety.
A recent article in The New York Times also pointed out that concern about AI risk is precisely the driving force behind Dario's push for technological leadership.
He believes AI could bring enormous risks, so he wants to develop this technology before those who don't care about human safety do, and have it controlled by people he trusts.
In his vision: training will continue, but the company should leave enough time for alignment, safeguards, and third-party evaluation.
Let's wait and see just how much effort Anthropic will put into safety while it keeps pumping out new models~
Reference links: [1]https://x.com/METR_Evals/status/2118412183860351084 [2]https://x.com/Sam_McCandlish/status/2118422266669371519 [3]https://www.nytimes.com/2026/11/05/technology/dario-amodei-anthropic-ai.html [4]https://darioamodei.com/post/we-must-pace-the-frontier