GitHub Launches Copilot Fusion to Orchestrate Multi-Model Performance and Cost
GitHub has released Copilot Fusion, a runtime orchestration system that dynamically coordinates models from Anthropic and OpenAI to optimize performance, cost, and latency. Benchmarks indicate its max setting scores just 2 points below Claude Opus 5.5 in the Coding Agent Index while costing roughly half as much per task ($5.59 vs $11.42), offering developers a high-value near-frontier option.
Full Report
Contents5 sections
October 28, 2026
GitHub has released Copilot Fusion in GitHub Copilot, which orchestrates between Anthropic and OpenAI models. It scores 2 points below Opus 5.5 in Claude Code at half the Cost per Task in the Coding Agent Index
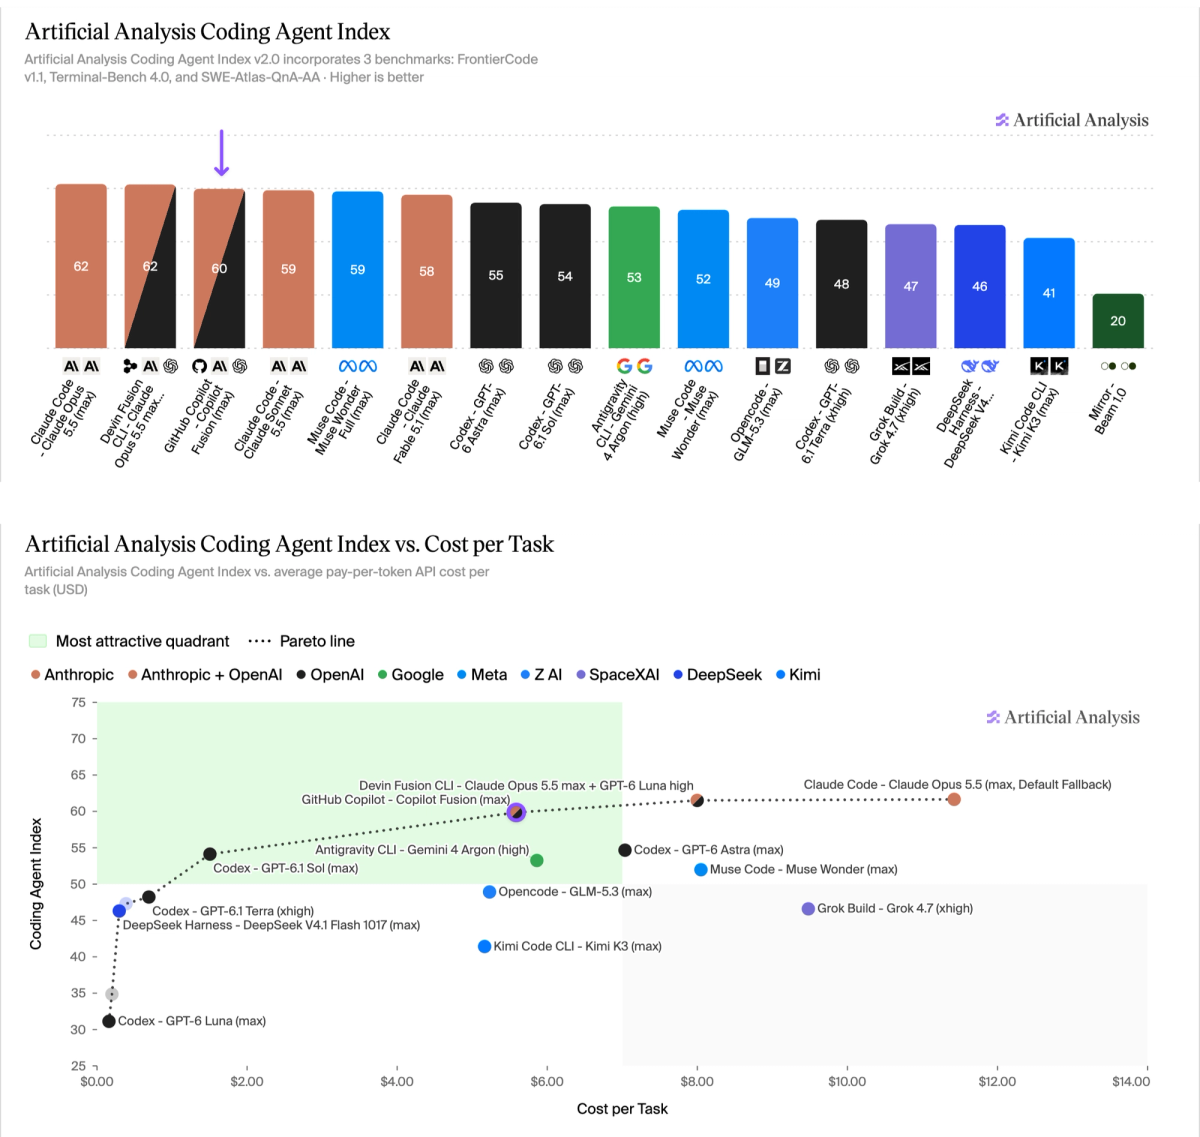
GitHub describes Copilot Fusion as a runtime orchestration system, which selects and coordinates models to optimize performance, cost, and latency for each task. Copilot Fusion chooses between a number of models from Anthropic and OpenAI, including Claude Opus 5.5, Claude Sonnet 5.5, GPT-6 Astra, and GPT-6 Sol. We benchmarked its max setting in GitHub Copilot CLI in the Artificial Analysis Coding Agent Index v2.0.
Token costs are charged based on the underlying models used to complete a request.
Key takeaways:
➤ Cost-efficient for near-frontier performance: Copilot Fusion in GitHub Copilot costs $5.59 per task, versus $11.42 for Claude Code with Opus 5.5 (max). Devin Fusion with Opus 5.5 (max) + GPT-6 Luna (high) scores 62 at $8.00 per task.
➤ Slight lead in Terminal-Bench 4.0: The Coding Agent Index v2.0 weights its three constituent benchmarks equally. Copilot Fusion in GitHub Copilot leads Terminal-Bench 4.0 with a score of 71. It ranks third on FrontierCode in the chart at 51, behind Claude Code with Opus 5.5 (max) at 56 and Devin Fusion with Opus 5.5 (max) + GPT-6 Luna (high) at 54. Its SWE-Atlas-QnA-AA score lags at 57, between GPT-6 Astra in Codex and Gemini 4 Argon in Antigravity CLI.
➤ Half the token use of Opus 5.5 in Claude Code: GitHub Copilot Fusion used 7.2M tokens per task in the Coding Agent Index, approximately half of the tokens used by Claude Opus 5.5 in Claude Code, and 30% less than Devin Fusion with Opus 5.5 (max) + GPT-6 Luna (high).
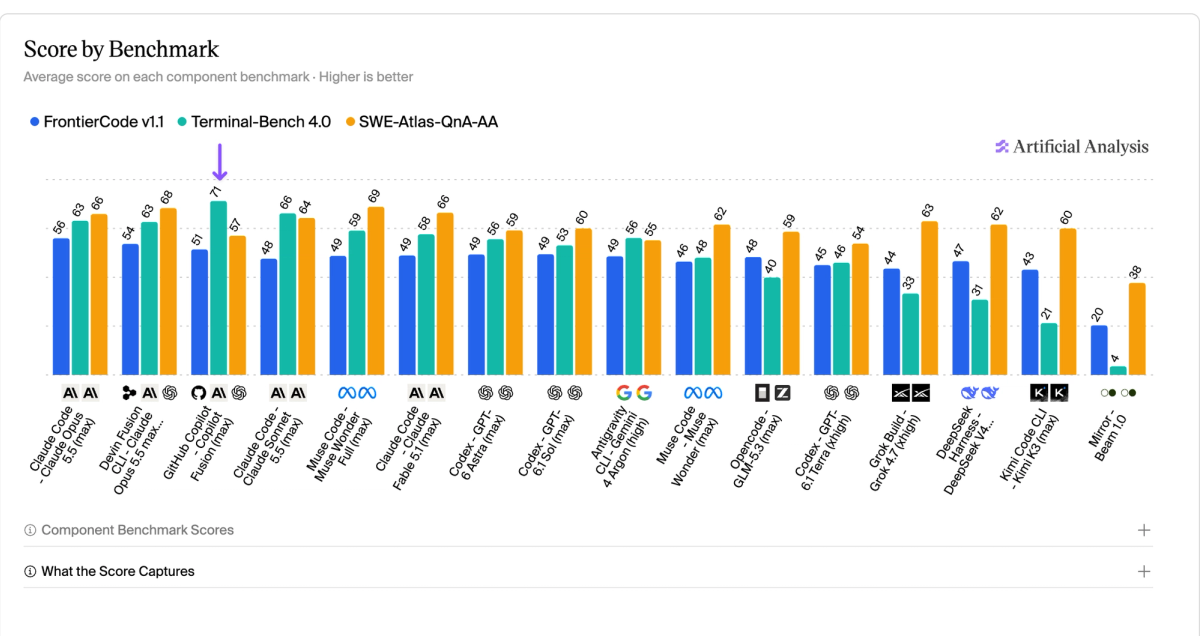
Copilot Fusion in GitHub Copilot lands with a slight lead in Terminal-Bench 4.0 with a score of 71. It ranks third on FrontierCode in the chart at 51, behind Claude Code with Opus 5.5 (max) at 56 and Devin Fusion with Opus 5.5 (max) + GPT-6 Luna (high) at 54. Its SWE-Atlas-QnA-AA score lags at 57, between GPT-6 Astra in Codex and Gemini 4 Argon in Antigravity CLI.
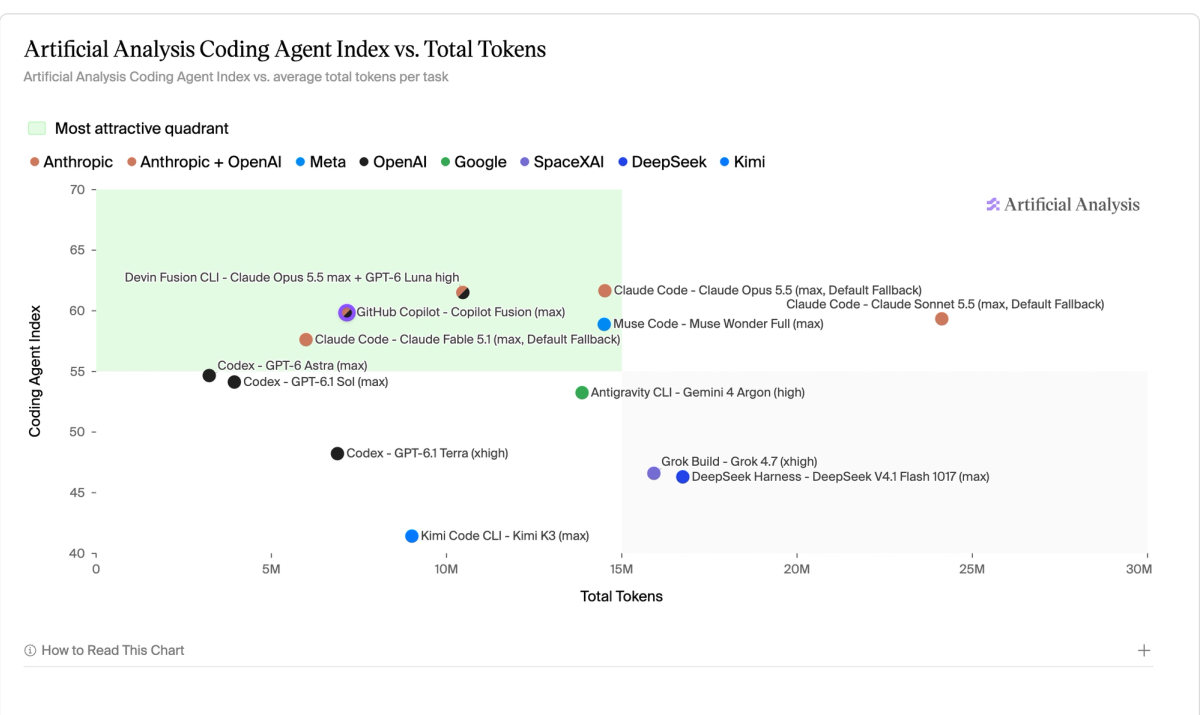
GitHub Copilot Fusion used 7.2M tokens per task in the Coding Agent Index, approximately half of the tokens used by Claude Opus 5.5 in Claude Code.
Explore the Coding Agent Index, task costs and benchmark results:
https://artificialanalysis.ai/agents/coding-agents?routers=true
Read the latest
[
Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5
Google’s Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5, and second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index
October 28, 2026](https://artificialanalysis.ai/articles/gemini-4-carbon-new-number-1)[

Announcing Artificial Analysis Intelligence Index v5
Index v5 features 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets
October 27, 2026](https://artificialanalysis.ai/articles/artificial-analysis-intelligence-index-v5)[
Code2Video-AA: how well do AI models design videos in code?
Artificial Analysis' implementation of HeyGen's Code2Video Bench, evaluating how well models create short product and brand videos from 114 design briefs using HyperFrames HTML.
October 26, 2026](https://artificialanalysis.ai/articles/code2video-aa){"@context":"https://schema.org","@type":"NewsArticle","headline":"GitHub Copilot Fusion orchestrates Anthropic and OpenAI models to balance performance and cost","description":"itHub has released Copilot Fusion in GitHub Copilot, which orchestrates between Anthropic and OpenAI models. It scores 2 points below Opus 5.5 in Claude Code at half the Cost per Task in the Coding Agent Index","datePublished":"2026-10-28","dateModified":"2026-10-28","image":"https://cdn.sanity.io/images/6vfeftx9/articles/0968ba533e8f3599faae4925bcf3781fbbd52fed-1024x1024.webp?w=1200&auto=format","author":{"@type":"Organization","name":"Artificial Analysis","url":"https://artificialanalysis.ai"},"publisher":{"@type":"Organization","name":"Artificial Analysis","url":"https://artificialanalysis.ai"},"mainEntityOfPage":{"@type":"WebPage","@id":"https://artificialanalysis.ai/articles/github-copilot-fusion-orchestrates-anthropic-and-openai-models-to-balance-performance-and-cost"}}
