Rohan Paul (@rohanpaul_ai) · 10/24/2026, 08:28:33
Meta and CMU Study: RL-Trained Small Models Outperform Llama-4 in Tool Selection
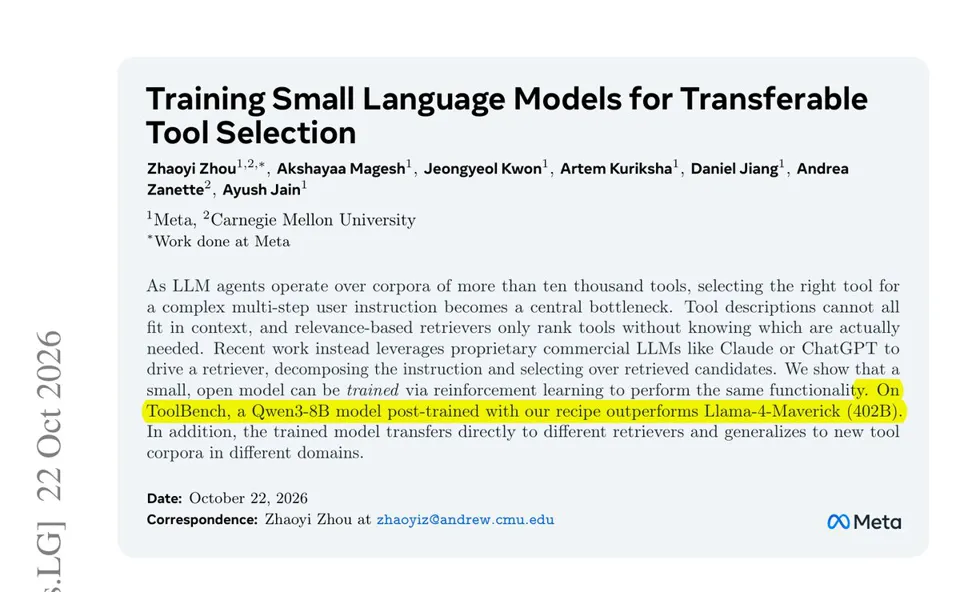
A new paper from Meta and Carnegie Mellon University demonstrates that an RL-trained Qwen3-8B small model outperforms a prompted 402B Llama-4-Maverick in tool selection tasks. By decomposing requests into steps and using keyword search, the small model achieved 41.5% accuracy on ToolBench, compared to 30.6% for the large model's best setup. This suggests that specialized small models can effectively replace expensive large models for decision-making in scenarios with extensive tool catalogs.
SOURCE COVERAGEFull Original Report
Rohan Paul (@rohanpaul_ai) · 2026-10-24 00
New Meta and Carnegie Mellon paper finds that small models trained with RL pick the right tools more often than a prompted 402B Llama-4-Maverick.
Agents can face more than 10,000 tools, and their descriptions cannot all fit in context. Retrievers only rank by relevance, so recent setups have Claude or ChatGPT pick the tools.
They trained Qwen3 models to split a request into steps, search each step with plain keyword search, and pick 1 tool per step. Training used teacher-written examples, then RL that rewards useful search steps and exact picks.
On ToolBench, the trained 8B model picked exactly the right tools 41.5% of the time, versus 30.6% for Maverick's best prompted setup. With no retraining, it beat Maverick on 3 of 4 new tool benchmarks and improved when given a stronger retriever.
If your agent chooses from a large tool catalog, an RL-trained small model can handle selection instead of a prompted large one.