IT之家 · 智能时代 · 10/9/2026, 12:59:08
JetBrains Releases Mellum2.1: RL Enhances Agentic Coding with Throughput Nearly Double Qwen3.5-9B
JetBrains released the open-source Mellum2.1 model, significantly enhancing agentic coding capabilities by expanding reinforcement learning as a core training phase. The model achieves nearly double the high-load inference throughput of Qwen3.5-9B on H200 GPUs and supports local deployment for code privacy.
SOURCE COVERAGEOriginal coverage
JetBrains Releases Mellum2.1: A Coding AI Model with Inference Throughput Nearly Double That of Qwen3.5-9B Under High Load
On October 9, JetBrains announced the release of its Mellum2.1 model via a blog post published on October 8, highlighting significant enhancements in agentic coding capabilities. The model retains the 12B Mixture-of-Experts (MoE) architecture from Mellum2, featuring 2.5B active parameters, and continues to be released under the Apache 2.0 license.
The primary upgrade in Mellum2.1 lies in the reinforcement learning (RL) phase following pre-training. This stage has expanded from a brief finalization step into a core component of the training process, incorporating additional training data across tasks such as mathematics, algorithmic competitions, science, tool use, and software engineering.
JetBrains built internal infrastructure for RL environments to support this model, launching millions of sandboxes covering thousands of environments during training. Prior to training, the team also curated open datasets by filtering out test defects, unverifiable answers, and tasks with inappropriate difficulty levels.
With these upgrades, Mellum2.1 can explore codebases, edit files, and verify its own modifications. JetBrains states that the most significant improvements are seen in agentic coding, where the model can identify root causes of failing tests, draft fixes, and validate results.
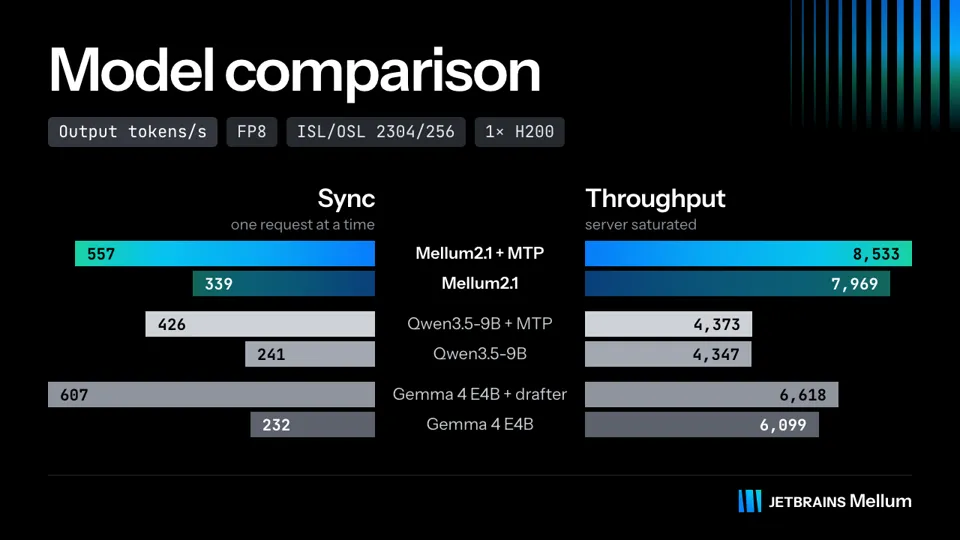
In terms of performance, Mellum2.1 maintains the same speed as Mellum2 due to their identical architectures, while Multi-Token Prediction (MTP) further enhances response times. In single-request scenarios, MTP improves speed by approximately 1.6x.
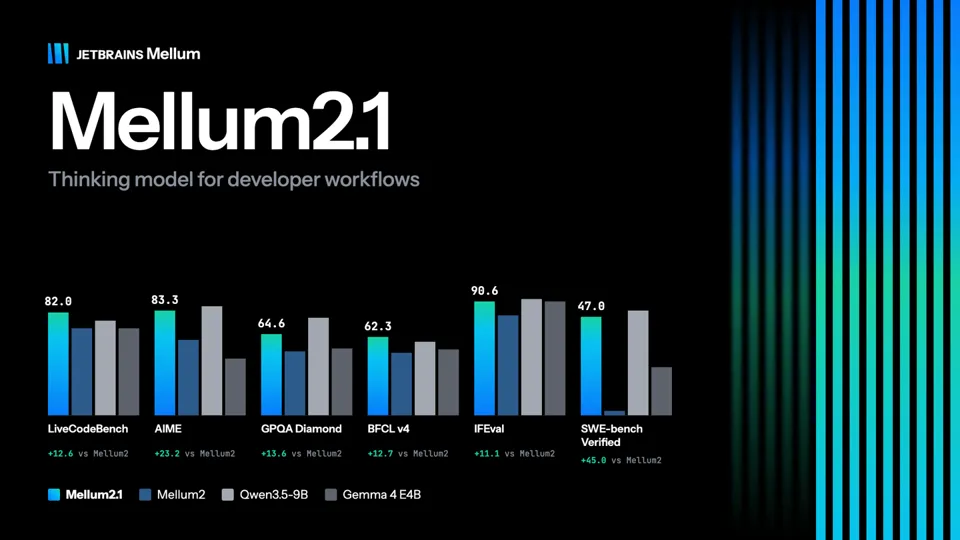
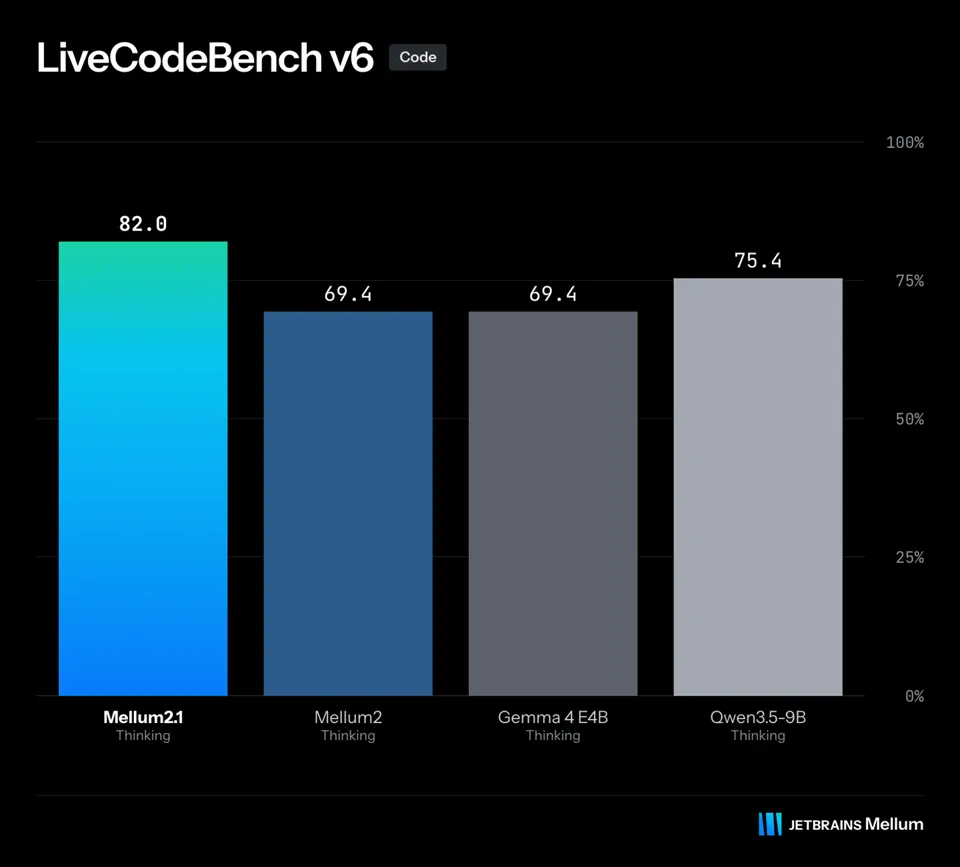
JetBrains benchmarked Mellum2.1 against Mellum2, Qwen3.5-9B, and Gemma 4 E4B under identical evaluation settings. The results show that under high load, Mellum2.1’s inference throughput in output tokens per second is nearly double that of Qwen3.5-9B, with improvements observed across dimensions including coding, algorithmic competitions, mathematics, tool calling, and general knowledge. IT Home provides the relevant screenshots below:
Mellum2.1 is now available on Hugging Face, supporting deployment locally or on proprietary infrastructure, allowing enterprises to keep their code and data within their own environments. Official releases will soon include GGUF versions for llama.cpp, Ollama, and LM Studio, as well as an MTP speculative decoding component for vLLM.