量子位官网 · 10/19/2026, 18:04:18
Meta Biohub and NIH Launch $1.8B Virtual Biology Initiative
Meta Biohub, the NIH, and the Department of Energy have launched a $1.8 billion 'Virtual Biology' initiative to build data infrastructure for life-prediction models. The project aims to train high-fidelity AI capable of simulating systems from molecules to whole organisms, shifting research focus toward digital-experiment-to-real-world validation loops and signaling a strategic pivot in AI competition towards complex life sciences.
SOURCE COVERAGEFull Original Report
Contents5 sections
On October 17, Zheyuan Technology released the WHIRLPO Computational Medicine platform.
In 2026, an interesting shift is occurring in the AI landscape. While industry attention remains focused on large model parameters, agents, and general superintelligence, Mark Zuckerberg has directed capital toward a more complex domain: living systems.
In April of this year, Biohub—founded by Zuckerberg and his wife Priscilla Chan—launched its Virtual Biology initiative, investing 1.8 billion in investment, including over $500 million from the DOE over the next five years and the opening of extensive accumulated biomedical data by the NIH.
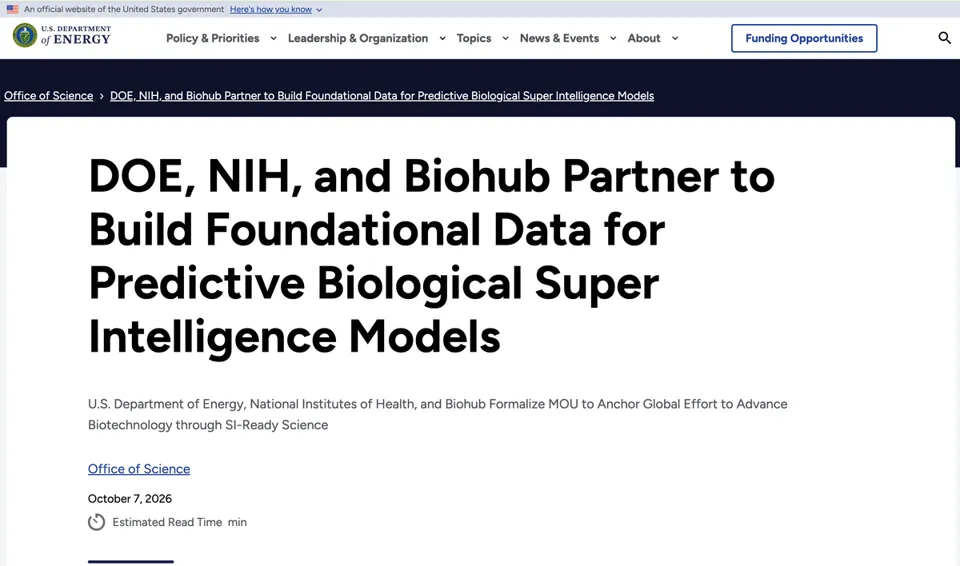
The goal of this project is straightforward: to create an AI capable of predicting life behaviors, which Biohub calls "Virtual Biology." Simply put, this involves building high-fidelity digital replicas ranging from molecules, genes, and cells up to complete living systems. In the future, researchers will be able to pose hypotheses about life, simulate interventions, and conduct digital trials on their computers before moving to real-world experiments in the lab, much like they currently query large language models.
This move is not merely Zuckerberg’s bet on biopharmaceuticals. On a deeper level, life sciences are becoming the second battlefield for AI competition. The race for general-purpose large models has become fiercely competitive, with rising barriers in compute, talent, and capital. In contrast, understanding living systems remains an undefined frontier. Whoever enables AI to truly comprehend life will establish moats far harder to replicate than those surrounding chatbots.
AI excels at molecular design, but drug discovery remains difficult
The integration of AI and biopharmaceuticals is not new; it was one of the earliest areas where industrialization expectations were placed on AI. However, after more than a decade, a core question persists: Are we actually closer to new drugs?
In recent years, the most notable achievements in AI-driven drug discovery have been concentrated at the molecular level: protein structure prediction, candidate molecule screening, molecular generation, drug safety prediction, and drug-target interactions. AI can generate thousands of candidate molecules at once, significantly expanding the chemical space available for screening—a tangible efficiency gain.
However, if the evaluation metric shifts from model benchmarks to the successful market launch of a new drug, reality is less optimistic. In August of this year, Nature Reviews Drug Discovery published a retrospective on over a decade of AI in drug development: despite the proliferation of various AI algorithms, results delivering genuine clinical value remain limited. Many AI-focused pharmaceutical companies’ projects stall at the preclinical or Phase I/II clinical stages, with very few advancing to Phase III trials.
In small-molecule generation, AI indeed makes it easier to find molecules that bind to proteins, but this is ligand design, not drug design. Finding a molecule that binds to a target and finding a safe, effective drug within the human body are entirely different challenges.
This is the area most worthy of reflection for the industry today. In the past, we oversimplified complex biological problems. AI excels at answering "Which molecule can bind to this target?" But the true difficulty in drug discovery lies in a series of systemic questions: Why does this target cause disease? What chain reactions occur in the entire human biological system after intervening on the target? Why is the same drug effective for some patients but not others? Why do cell and animal experiments show excellent results, only to fail in human clinical trials?
Drug molecules do not act in isolation. They enter a dynamic, complex system involving genes, proteins, cells, tissues, organs, immunity, metabolism, and external environmental factors—all interacting with one another. The success of a drug hinges precisely on this system. This raises a fundamental question: If AI can only understand molecules but not complete living systems, how far can it take drug discovery?
From single-point molecular models to world models of life
This explains the core shift in AI life sciences in 2026: modeling scales are no longer limited to individual proteins, molecules, or cells but are extending upward to construct life prediction models. The goal is no longer just predicting protein structures but characterizing life states, anticipating changes in the system following intervention, and simulating cellular responses to perturbations—what the industry calls World Models of Life.
Large Language Models learn the rules of language; physical world models learn the rules of object motion and spatial dynamics. The rules facing World Models of Life are far more complex. Genetic variations alter protein expression; proteins regulate signaling pathways; signals change cell states. Interactions between cells form tissue microenvironments, influencing organs and the human body layer by layer. Life itself is not static; it grows, ages, develops compensatory mechanisms, undergoes mutations, and continuously feeds back to external interventions.
Therefore, a World Model of Life is not a static encyclopedia of biology. Its core is understanding how life operates and predicting how the entire system evolves when a specific variable is changed.
Once this model is implemented, AI’s role in pharmaceutical R&D will fundamentally change. Old Mode: Given a target, quickly find candidate molecules. New Mode: Given a disease, first identify the root cause, then determine which position to intervene, which patients will benefit, and predict the systemic chain reactions resulting from the intervention. While both modes use AI to empower new drug development, the problems they solve are completely different.
Domestic parallel deployment: Computational medicine written into national planning
This transformation is not unique to the United States; domestic AI life sciences are also shifting from single-point algorithms to systemic disease modeling.
In September of this year, ten departments including the Ministry of Industry and Information Technology (MIIT) and the National Development and Reform Commission (NDRC) released the "15th Five-Year Plan for Pharmaceutical Industry Development." Computational medicine was included as a key technical direction for the pharmaceutical industry over the next five years, listed alongside AI, quantum computing, and supercomputing. AI and supercomputing provide powerful general-purpose computing capabilities; computational medicine addresses how to connect these computing resources to living systems to solve real-world disease problems.
Zheyuan Technology is a domestic team pursuing this path. Rather than simply training a larger biological foundation model, they focus on diseases themselves, integrating genomic data, cellular characteristics, disease mechanisms, patient data, and drug intervention information to build multi-level computational models. They are attempting to construct a system of World Models of Life that can be continuously simulated, trained, and validated.
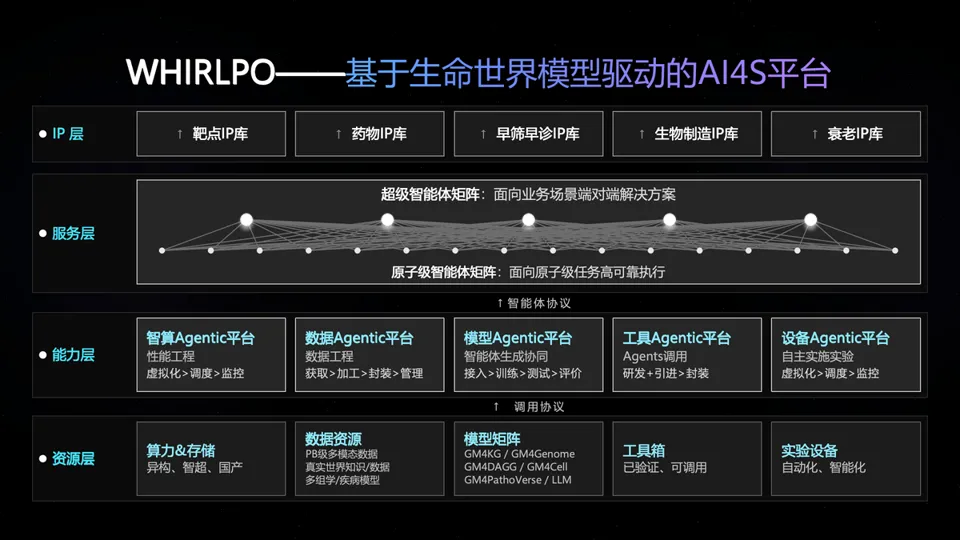
On October 17, Zheyuan Technology released the WHIRLPO Computational Medicine platform. It is not a standalone biological foundation model but rather a solution to a more fundamental engineering challenge: if World Models of Life are the infrastructure for next-generation life sciences, we need a base layer to support the training and operation of such models.
Building a World Model for Life Is Far Harder Than Training LLMs
The difficulty of implementing world models for life is easily underestimated. First is the data challenge. Large language models (LLMs) are fueled by massive amounts of internet text, but there is no unified dataset in the life sciences. Data sources—genomics, single-cell, spatial omics, pathology, imaging, and clinical records—are fragmented, with vast differences in format, quality, and observational scale. Much high-value data requires dedicated experiments to generate. A significant portion of Biohub’s $1.8 billion investment is allocated to producing biological data, rather than solely training models.
Second is the challenge of multi-scale modeling. There is no one-size-fits-all model for life. Studying DNA mutations, cell states, tissue microenvironments, and human diseases requires different models working in concert. The complete world model for life will likely not be a single monolithic model, but a composite system where multiple models, knowledge bases, and tools collaborate.
Third is the engineering challenge of heterogeneous computing power. Pre-training models, analyzing omics data, simulating disease progression, and running digital patient trials all require different computational approaches. This demands flexible scheduling of diverse resources like CPUs and GPUs, presenting large-scale scientific computing engineering problems rarely encountered in traditional LLM development.
Fourth, life models must bridge the computational world and the real experimental world. If an LLM produces an incorrect answer, it can simply be retrained. However, target hypotheses generated by life models must undergo laboratory validation; experimental results then feed back to refine the model, which ultimately faces clinical scrutiny. Model conclusions cannot merely be self-consistent within a computer.
The WHIRLPO platform addresses this exact pain point: integrating heterogeneous computing power, multi-omics life data, model matrices, research tools, intelligent agents, and experimental validation pipelines to build infrastructure that closes the loop from model training and scientific computing to wet-lab validation. In short, Zheyuan is not just building models; it is creating the production foundation for world models of life.
AI in Life Sciences Enters the Infrastructure Competition Era
In 2026, industry resonance emerged across China and the United States. In the US, Biohub joined forces with the Department of Energy, NIH, Meta, and DeepMind to build the data, computing, and experimental infrastructure required for AI in life sciences. In China, computational medicine was included in the 15th Five-Year Plan for pharmaceuticals, and local teams began constructing engineering platforms for world models of life.
While these developments may seem independent, they point to the same underlying judgment: AI in life sciences has moved beyond competing on model metrics and entered the era of infrastructure competition.
Previously, the industry competed on who could predict protein structures more accurately, who could generate better molecules, or who could accelerate specific R&D stages. The core competencies for the next phase have shifted to: Can we acquire large-scale, high-quality life science data? Can we model across scales—from genes and cells to tissues and whole humans? Can we coordinate multiple models effectively? Can we ensure continuous closed-loop validation between models and real-world experiments? Ultimately, can we upgrade AI from processing life data to understanding life systems?
The direction of AI-driven drug discovery over the past decade has been correct. What we have conquered so far is only the relatively computable part of life’s complexities. Molecules are important, but the subject of drug treatment is not molecules—it is humans. Between a candidate molecule and therapeutic efficacy in the human body lies a complete, complex life system.
If world models for life become AI’s next core direction after language models and physical world models, the biggest opportunities may not belong to teams that marginally improve model metrics. The truly scarce asset is not yet another bio-AI model, but a complete infrastructure that enables AI to enter the real world of life.
This article was provided by Zheyuan Technology and republished by Quantum Bit with authorization. Views expressed are those of the original author.