Artificial Analysis 发布决策指数 v2 引入校准置信度指标
Artificial Analysis 推出决策指数 v2,将私有数据集占比从 25% 提升至 45%,并采用同时奖励正确性与置信度校准的新头部指标。榜单中 Nace AI 的 Drex Max v1.1 以 73 分微弱领先,Mammoth 27B 与 GPT-6 Luna 差距在 4 分内且速度快 118 倍。
报道正文
本文目录6 个章节
Introducing the Artificial Analysis Decision Index v2
Introducing the Artificial Analysis Decision Index v2: a new proprietary evaluation, updated benchmarks, and a headline metric that rewards model calibration
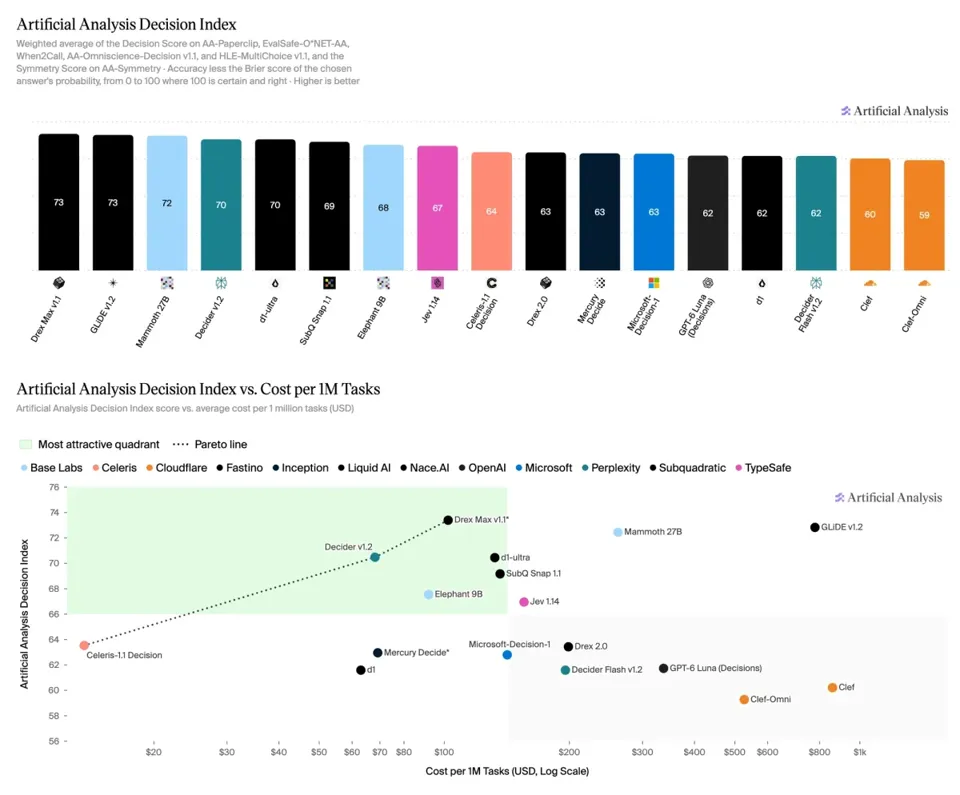
We’ve released the second version of the Artificial Analysis Decision Index to better reflect real-world utility and guard against benchmark gaming. 45% of the Index is now built on private datasets, up from 25% in v1. Drex Max v1.1 from Nace AI narrowly leads among decision models at 73, within 1 point of GLiDE v1.2 (Fastino Labs) and Mammoth 27B (Baseten).
Updates in Decision Index v2:
➤ Decision Score: We adopt a new headline metric that rewards a model for both correctness and calibrated confidence. Each question scores from 0 to 100: right answers score above 50, wrong answers below 50, and confidence in its top answer moves the score within each half
➤ AA-Paperclip (30%): We added a new private benchmark of 1,500 documents including resumes, receipts, invoices, and AI and machine learning research papers. Models make decisions and extract facts from each document and are scored jointly as a single decision, correct only if all 15 answers are right
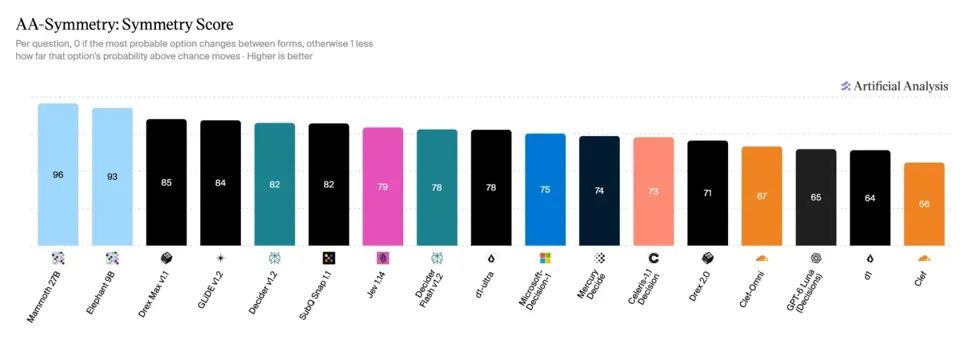
➤ AA-Symmetry (15%): This evaluates whether models change their answers for equivalent questions worded differently. We test 120 questions with variations such as reordered options, swapped labels, and negated yes/no questions, then measure how consistent the model’s probabilities are across those variations
➤ AA-Omniscience-Decision v1.1 and HLE-MultiChoice v1.1 (15% each, down from 25%): AA-Omniscience-Decision now varies the wording of its “I don’t know” option across ten alternatives. HLE-MultiChoice adds an option to decline using the same ten phrasings
We’ve also added EvalSafe-ONET-AA (15%), our implementation of TypeSafe AI’s ONET benchmark. We have retained When2Call from NVIDIA in the Index at a decreased weighting of 10% (down from 25%), and removed WildGuardTest given its high saturation.
Key results:
➤ Three decision models sit within 1 point at the top of the Index: Drex Max v1.1 from Nace AI and GLiDE v1.2 from Fastino Labs both score 73, with Mammoth 27B from Base Labs scoring 72
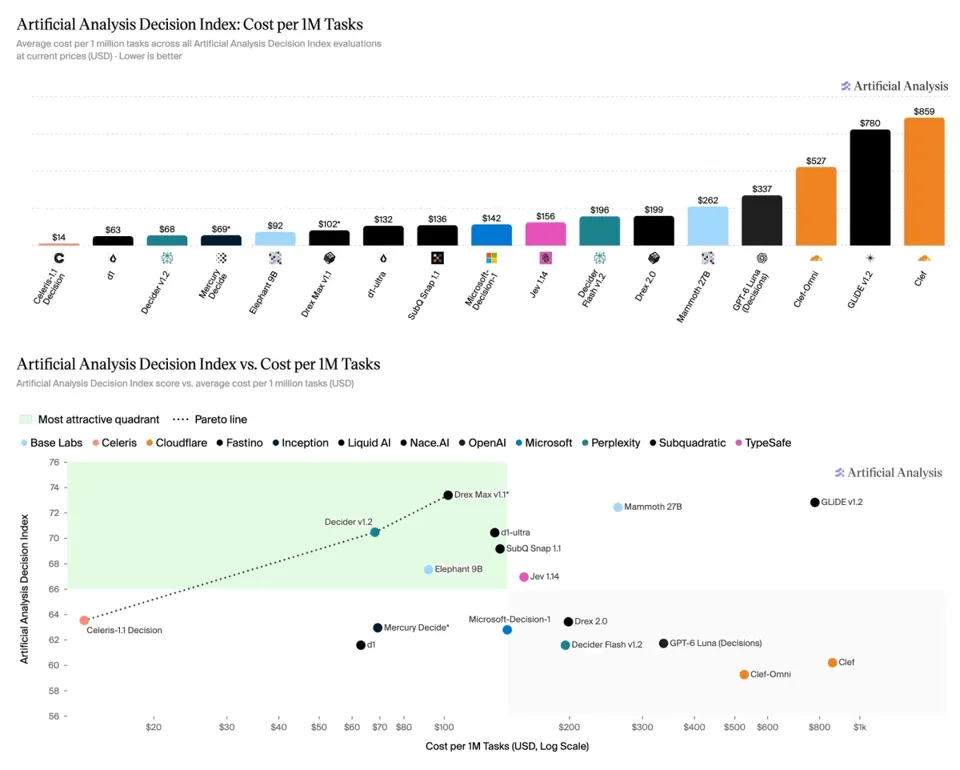
➤ Cost per 1M Tasks varies by more than 60x across decision models: Celeris-1.1 Decision ($14), Decider v1.2 ($68) and Drex Max v1.1 ($102) sit on the Decision Index vs. Cost Pareto frontier, while Clef costs $859. Token price is not the only cost driver: most decision models, including Drex Max v1.1 and Decider v1.2, bill a document’s input once for all its questions, while GLiDE v1.2 and Decider Flash v1.2 bill it for every question. This means GLiDE v1.2 costs $780, nearly 8x higher than Drex Max v1.1 despite only 33% higher list prices
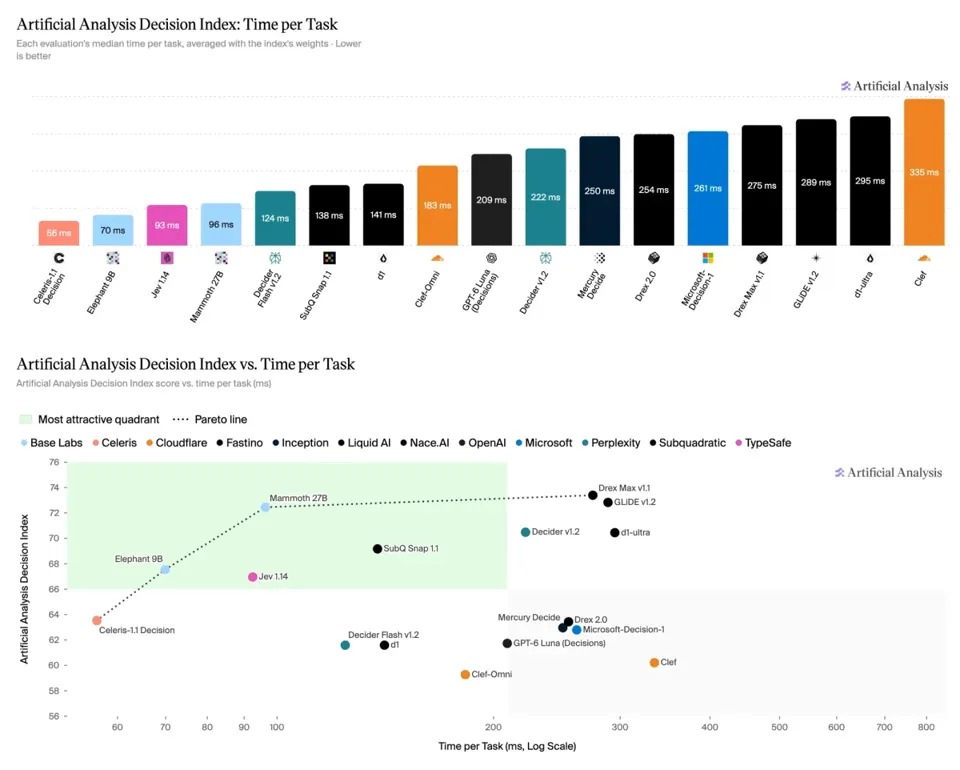
➤ Language models can score higher, alongside higher Cost and Time per Task: Claude Haiku 5.5 (Max) scores 77 and GPT-6 Luna (Max) scores 76 on Decision Index v2, putting them ~3 points ahead of Drex Max v1.1. GPT-6 Luna (Max) costs $1,530 per 1M Tasks vs. $102 for Drex Max v1.1 (15x the cost) and takes 11.34 seconds per task vs. 275 milliseconds (~40x slower)
Decision Score
The Decision Score rewards models for both correct answers and well-calibrated confidence. A decision model’s answer is typically acted on when its confidence clears a threshold; otherwise, it is passed to a person or a more capable model. The Decision Score measures the average payoff across all thresholds, so it does not depend on choosing a single cutoff.
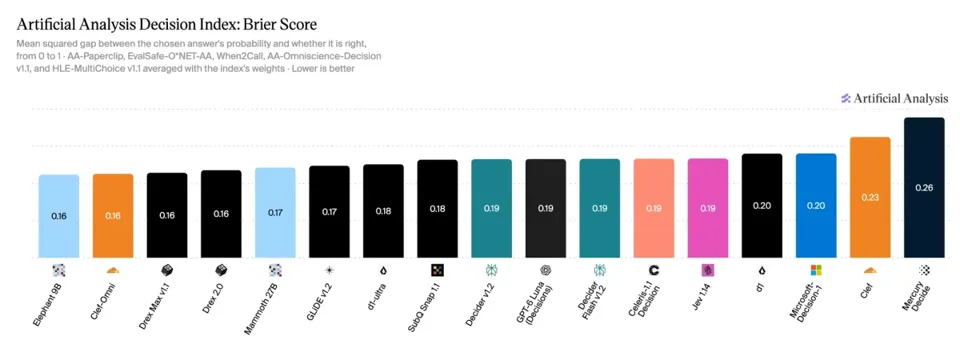
For each question, the score is 50 × (1 + c − (p − c)²), where p is the probability the model assigns to its chosen answer and c is a flag for whether the answer was correct (c = 1 if correct, c = 0 if incorrect). Across an evaluation, this is equal to 50 × (1 + Accuracy − Brier score).
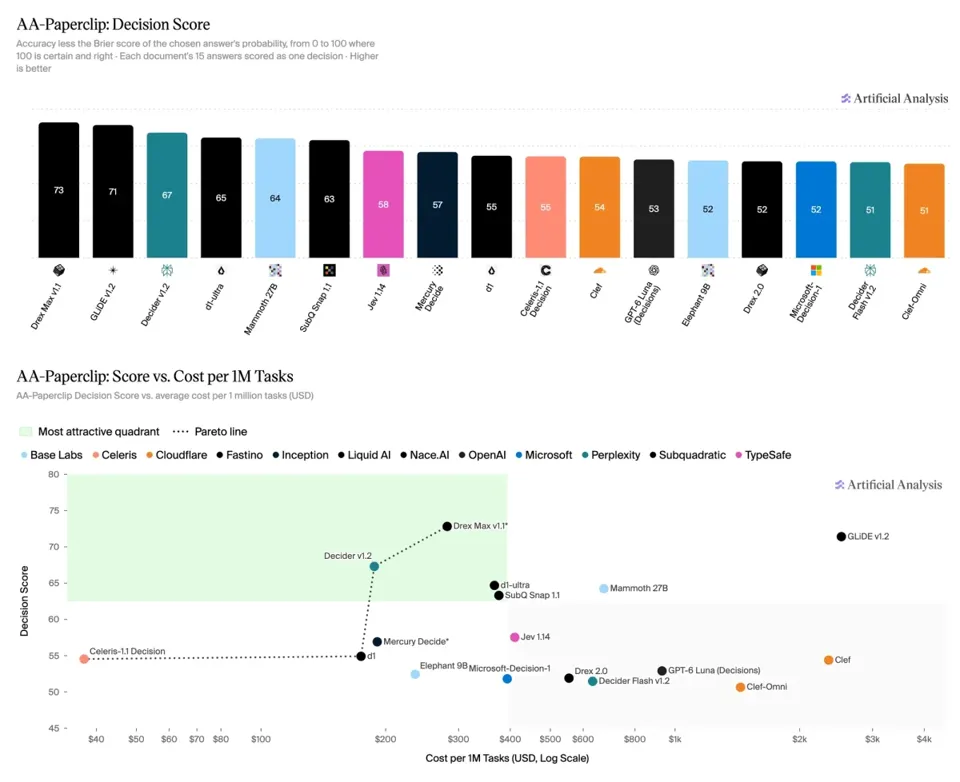
Including confidence impacts overall leaderboard rankings. On AA-Paperclip, for raw accuracy Clef passes 36% of documents and Celeris-1.1 Decision passes 24%, but Celeris-1.1 Decision matches it on the Decision Score due to better calibration (Brier score of 0.15 vs. 0.27 for Clef). Across the Index, GLiDE v1.2 leads Drex Max v1.1 on accuracy metrics (60 vs. 58), while Drex Max v1.1 edges ahead on the Decision Index.
AA-Paperclip
AA-Paperclip tests models on extracting facts and making decisions about real-world documents. Each of its 1,500 private documents has five decisions and ten facts to extract. The key metric measures the share of documents where a model answers all 15 questions correctly. For the Decision Score, the model’s confidence in a document is the product of its 15 answer probabilities.
Claude Haiku 5.5 (Max) passes 92% of documents and GPT-6 Luna (Max) passes 86%. Drex Max v1.1 (63%) and GLiDE v1.2 (62%) lead the decision models, followed by Decider v1.2 (55%). The all-pass requirement separates models that look close on individual answers. Drex Max v1.1 gets 97% of answers right, close to Claude Haiku 5.5 (Max) at 99%, but passes 63% of documents against Haiku's 92%. Decision models lose most documents on the decisions rather than extraction, with Drex Max v1.1 correctly making all five decisions on 71% of documents and all ten extractions on 88%.
AA-Symmetry
AA-Symmetry measures how consistent models are when asked equivalent questions. We take a fixed task set and make changes like reordering options, swapping labels, or negating yes/no questions. AA-Symmetry includes 120 base questions and total 440 variations, testing consistency in both the chosen answer and its probability.
Models from Baseten lead on AA-Symmetry, driven by a high abstention rate. They consistently admit they do not know an answer with high confidence across question variations, earning high consistency scores. Mammoth 27B scores 96 and Elephant 9B scores 93 on AA-Symmetry. Mammoth 27B selects the same answer across variations on 99% of questions, compared with 91% for Drex Max v1.1, 88% for GLiDE v1.2 and 67% for Clef.
Cost per Task
Decision model costs ranged from $14 per 1M Tasks for Celeris-1.1 Decision to $859 for Clef. Celeris-1.1 Decision, Decider v1.2 and Drex Max v1.1 sit on the Decision Index vs. Cost Pareto frontier, with GPT-6 Luna (Max) ($1,530) and Claude Haiku 5.5 (Max) ($6,240) extending it at higher scores.
Token price isn’t the only factor in decision model cost. GLiDE v1.2 and Decider Flash v1.2 evaluate each question in a separate pass and bill the input each time, so an AA-Paperclip task uses about 63k input tokens, against about 9k for Drex Max v1.1. As a result GLiDE v1.2 costs $780 per 1M Tasks at $0.04 per 1M input tokens, and Decider Flash v1.2 costs $196, nearly 3x Decider v1.2, at half its token price.
Time per Task
Celeris-1.1 Decision recorded the lowest Time per Task at 56 milliseconds, followed by Elephant 9B (70 milliseconds) and Jev 1.14 (92 milliseconds). In comparison, Claude Haiku 5.5 (Max) has a Time per Task of 32.65 seconds. Mammoth 27B scores within 4 points of GPT-6 Luna (Max) on the Decision Index and is 118x faster.