Perplexity 开源 Decider v1.3 决策模型,支持精确文本片段抽取
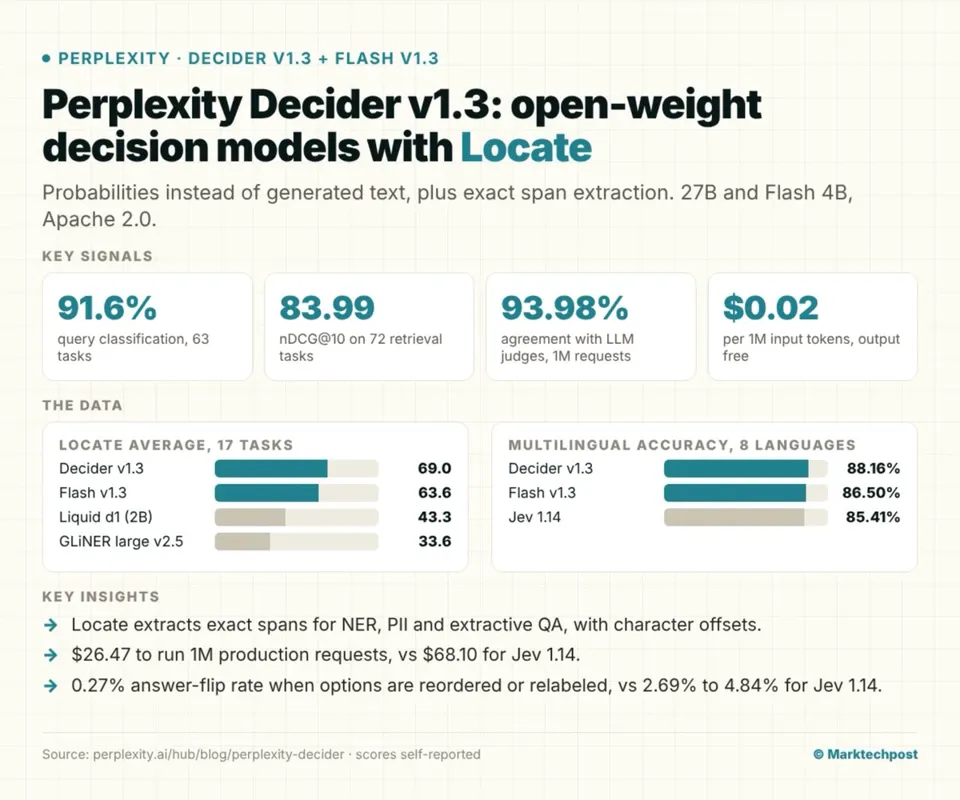
Perplexity 发布 Decider v1.3 与 Decider Flash v1.3 两款开放权重决策模型,核心能力从单一标签分类升级为返回带起止字符偏移的精确文本片段(Locate)。在 17 项域外 NER、PII 与抽取式问答任务上,v1.3 平均得分 69.0、Flash 63.6,显著高于 Liquid d1 的 43.3 与 GLiNER large v2.5 的 33.6;查询分类在 63 项任务上达 91.6%,答案翻转率仅 0.27%。模型基于 Qwen3.8-27B 与 Qwen3.5-4B 构建,采用 Apache 2.0 许可,API 输入定价为每百万 token 0.02 与 0.01 美元。
报道正文
▲ Marktechpost AI · 2026-11-13 16
▲ Perplexity just released Decider v1.3 and Decider Flash v1.3, open-weight decision models that now extract exact text spans, not just labels.
The key idea is Locate. You name a field ("location") or write an instruction, and the model returns the matching text with start and end character offsets. A span head plus a LoRA adapter does this while the backbone and decision head stay frozen. Classification questions still return probabilities in 1 forward pass.
On 17 out-of-domain NER, PII and extractive QA tasks, Locate averages 69.0 for v1.3 and 63.6 for Flash, vs 43.3 for Liquid d1 and 33.6 for GLiNER large v2.5. Query classification hits 91.6% across 63 tasks, and the answer-flip rate is 0.27% vs 2.69% to 4.84% for Jev 1.14. It is a trade-off though: Flash trails Jev 1.14 in finance, programming and law, and every number is self-reported.
27B on Qwen3.8-27B, Flash 4B on Qwen3.5-4B, Apache 2.0 weights. API pricing is $0.02 (v1.3) and $0.01 (Flash) per 1M input tokens, with free output......
Full analysis: