斯坦福论文揭示上下文学习回路 模型靠查表匹配标签
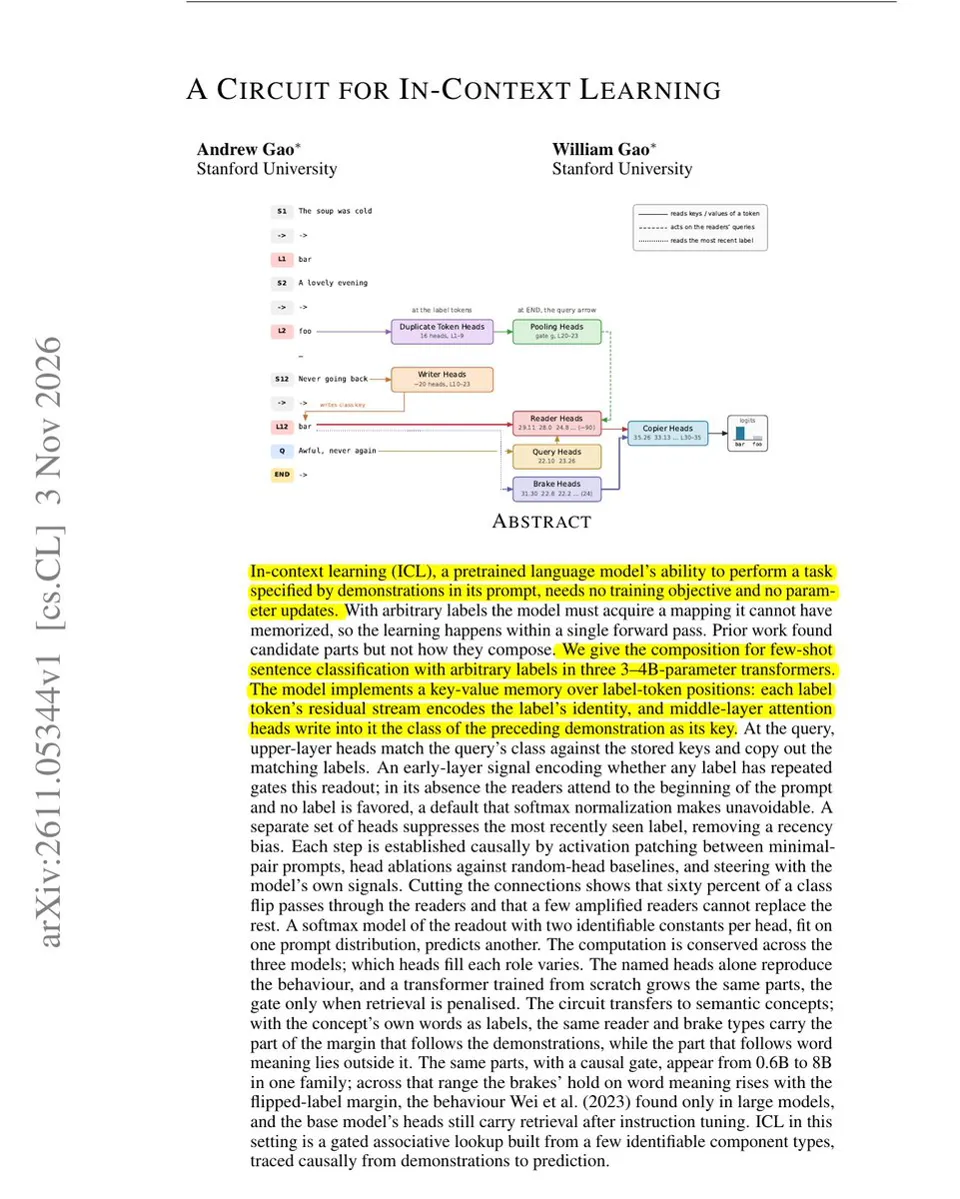
斯坦福一篇题为《A Circuit for In-Context Learning》的新论文指出,小模型的少样本能力并非真正“学会”新模式,而是靠标签查表:只有当同类标签在提示中重复出现时,模型才会触发这一查表机制。研究在 Qwen3-4B、SmolLM3-3B 与 Llama-3.2-3B 中追踪到完整路径——每个标签 token 存储所属句子类别,约 90 个靠后的注意力头负责将新句子与这些存储类别匹配。因此实用结论是:少样本提示中应重复每个标签,并只使用模型已能区分的类别,示例无法教给模型它本就缺失的特征。
报道正文
Rohan Paul (@rohanpaul_ai) · 2026-11-05 02
New Stanford paper finds that showing a small AI language model more examples cannot teach it a pattern it does not already notice, such as the third letter of a word.
finds that LLMs learn from few-shot examples by looking up stored labels, and only switch that lookup on when labels repeat.
An early signal opens this lookup only when some label repeats. With 1 example per class the model was right about 20% of the time, and with 6 it was right 96%.
Give a model a dozen sentences tagged with made-up labels like foo and bar, and it learns the mapping without weight updates. Earlier work found parts of this, but not how they fit together.
They traced the full path in Qwen3-4B, SmolLM3-3B and Llama-3.2-3B. Each label token stores the class of its sentence, and about 90 later heads match the new sentence against those stored classes.
For few-shot prompts, repeat every label several times and pick classes the model can already tell apart, since examples cannot teach a feature it lacks.
– arxiv. org/abs/2611.05344
Title: "A Circuit for In-Context Learning"