Google 发布 Gemini 3.1 Flash-Lite:主打高吞吐低成本
Google 推出 Gemini 3.1 Flash-Lite 预览版,专为大规模高频工作负载设计。该模型定价为每百万输入 token 0.25 美元、输出 1.50 美元,宣称在成本效率与速度上优于前代 2.5 Flash,适用于翻译、内容审核及 UI 生成等场景。
报道正文
本文目录3 个章节
Get best-in-class intelligence for your highest-volume workloads.
Equipe do Google Gemini
Your browser does not support the audio element.
Listen to article [[duration]] minutes
Gemini 3.1 Flash-Lite is now available in preview to developers via the Gemini API in Google AI Studio and for enterprises via Vertex AI. Priced at 1.50/1M output tokens, it's cost-efficient and faster than 2.5 Flash. Use 3.1 Flash-Lite for tasks like translation content moderation generating user interfaces and creating simulations.
Summaries were generated by Google AI. Generative AI is experimental.
Google made a new AI model called Gemini 3.1 Flash-Lite. It's super fast and cheap to use, so more people can use it. This AI is good at things like translating languages and checking content. Some companies are already using it to solve tough problems because it's both smart and efficient.
Summaries were generated by Google AI. Generative AI is experimental.
Explore other styles:
Today, we're introducing Gemini 3.1 Flash-Lite, our fastest and most cost-efficient Gemini 3 series model. Built for high-volume developer workloads at scale, 3.1 Flash-Lite delivers high quality for its price and model tier.
Starting today, 3.1 Flash-Lite is rolling out in preview to developers via the Gemini API in Google AI Studio and for enterprises via Vertex AI.
Cost-efficiency without compromise
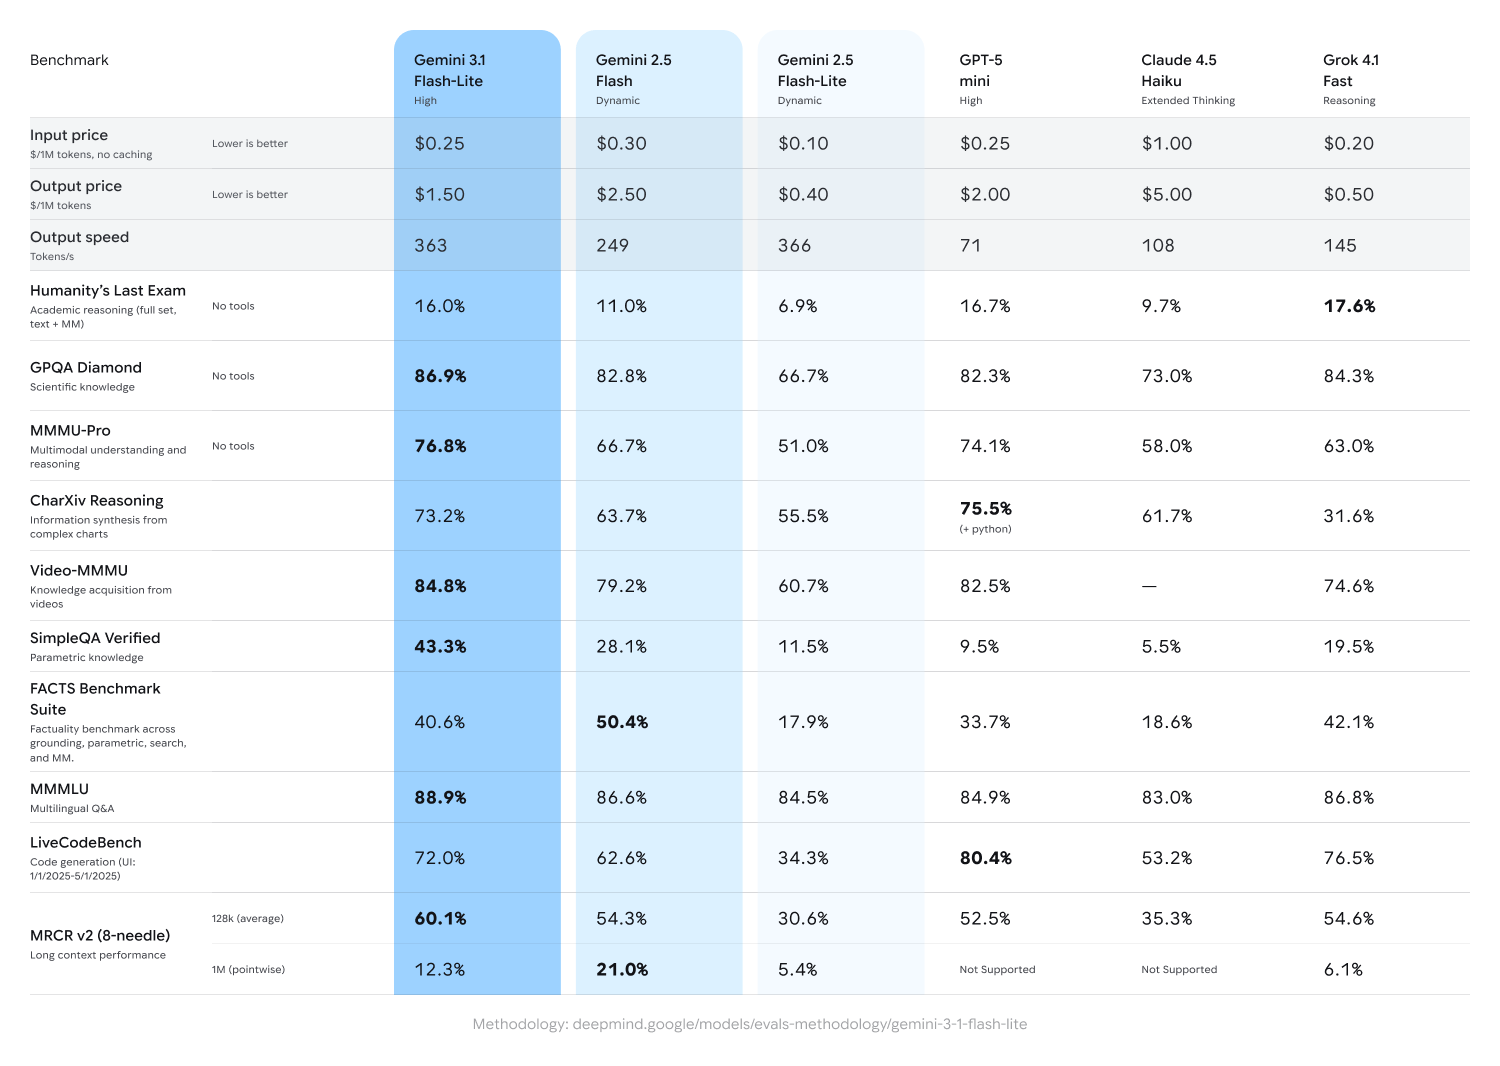
Priced at just 1.50/1M output tokens, 3.1 Flash-Lite delivers enhanced performance at a fraction of the cost of larger models. It outperforms 2.5 Flash with a 2.5X faster Time to First Answer Token and 45% increase in output speed, according to the Artificial Analysis benchmark while maintaining similar or better quality. This low latency is needed for high-frequency workflows, making it an ideal model for developers to build responsive, real-time experiences.

Gemini 3.1 Flash-Lite outperforms 2.5 Flash in speed and quality.
3.1 Flash-Lite achieves an impressive Elo score of 1432 on the Arena.ai Leaderboard and outperforms other models of similar tier across reasoning and multimodal understanding benchmarks, including 86.9% on GPQA Diamond and 76.8% on MMMU Pro–even surpassing larger Gemini models from prior generations like 2.5 Flash.
Adaptive intelligence at scale for developers
Beyond its raw performance, Gemini 3.1 Flash-Lite comes standard with thinking levels in AI Studio and Vertex AI, giving developers the control and flexibility to select how much the model “thinks” for a task, which is critical for managing high-frequency workloads. 3.1 Flash-Lite can tackle tasks at scale, like high-volume translation and content moderation, where cost is a priority. And it can also handle more complex workloads where more in-depth reasoning is needed, like generating user interfaces and dashboards, creating simulations or following instructions.
3.1 Flash-Lite instantly fills an e-commerce wireframe with hundreds of products in different categories.
3.1 Flash-Lite can generate dynamic weather dashboards in real-time, using live forecasts and historical data.
3.1 Flash-Lite creates a SaaS agent capable of executing versatile, multi-step tasks for a business.
3.1 Flash-Lite can analyze and sort large numbers of content like images quickly.
Early-access developers on AI Studio and Vertex AI, and companies like Latitude, Cartwheel and Whering are already using 3.1 Flash-Lite to solve complex problems at scale. Early testers highlighted 3.1 Flash-Lite’s efficiency and reasoning capabilities, saying it can handle complex inputs with the precision of a larger-tier model, plus follow instructions and maintain adherence.
We look forward to seeing what you build with 3.1 Flash-Lite and the rest of the Gemini 3 series models.