Rohan Paul (@rohanpaul_ai) · 2026/10/10 16:01:17
东京都立大学研究:AI 文本检测器跨代失效,Pangram 漏检率随模型版本剧变
东京都立大学最新论文指出,基于旧版模型训练的 AI 文本检测器(如 Pangram)在新一代大模型发布后性能断崖式下跌。数据显示,该工具对 GPT-5 改写内容的检出率高达 93.5%,但对 Meta Muse-Glimmer 的漏检率却达 79.8%,证明其鲁棒性严重依赖特定模型版本。这一发现警示学术界与出版界,现有检测手段无法应对快速迭代的生成式 AI,必须针对每次模型更新重新校准或放弃单一检测策略。
报道全文原始报道全文
Rohan Paul (@rohanpaul_ai) · 2026-10-10 08
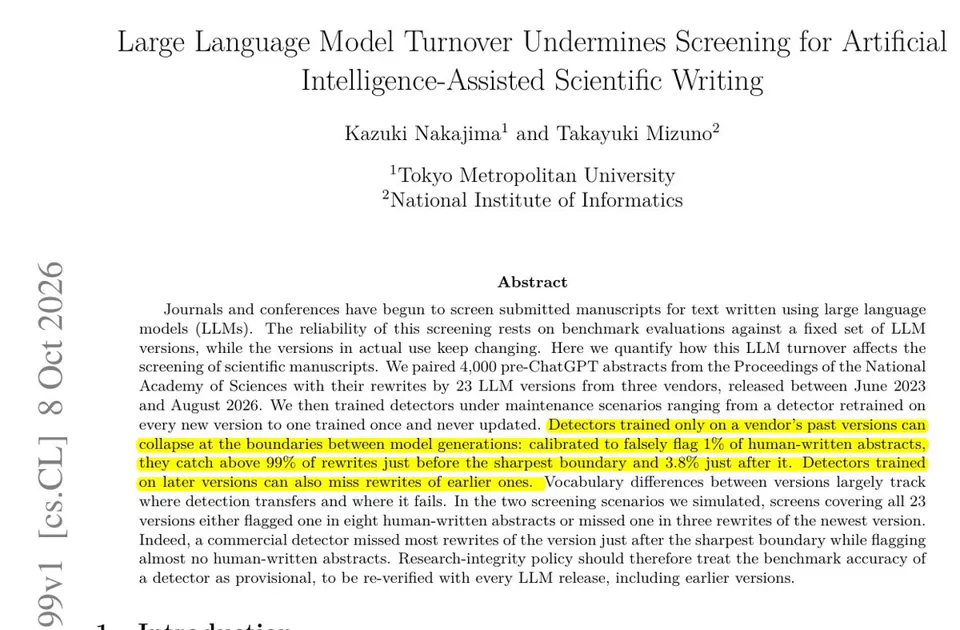
This paper finds that AI-text detectors trained on a vendor's older models caught over 99% of rewrites before a generation change and only 3.8% after it.
Detectors that screen scientific papers for AI writing can stop working when a new LLM generation arrives, so anyone relying on them should re-test them with every model release.
↳ 引用 @rohanpaul_ai (Rohan Paul): Pangram, the AI-text detector, missed 79.8% of scientific abstracts rewritten by Meta's Muse-Glimmer, while flagging just 1 of 5,000 human abstracts.
In a new paper from Tokyo Metropolitan University, reseaerchers find the share of AI-rewritten abstracts that Pangram misses depends strongly on the LLM version
Shows that it caught 93.5% of GPT-5 rewrites but missed 79.8% from another new model. Its miss rate depended mostly on which model did the rewriting.