Rohan Paul (@rohanpaul_ai) · 2026/10/14 04:02:34
SanSi 提出循环推理架构:1.4B 小模型通过复用层迭代决策,准确率超越 4.2B 单遍模型
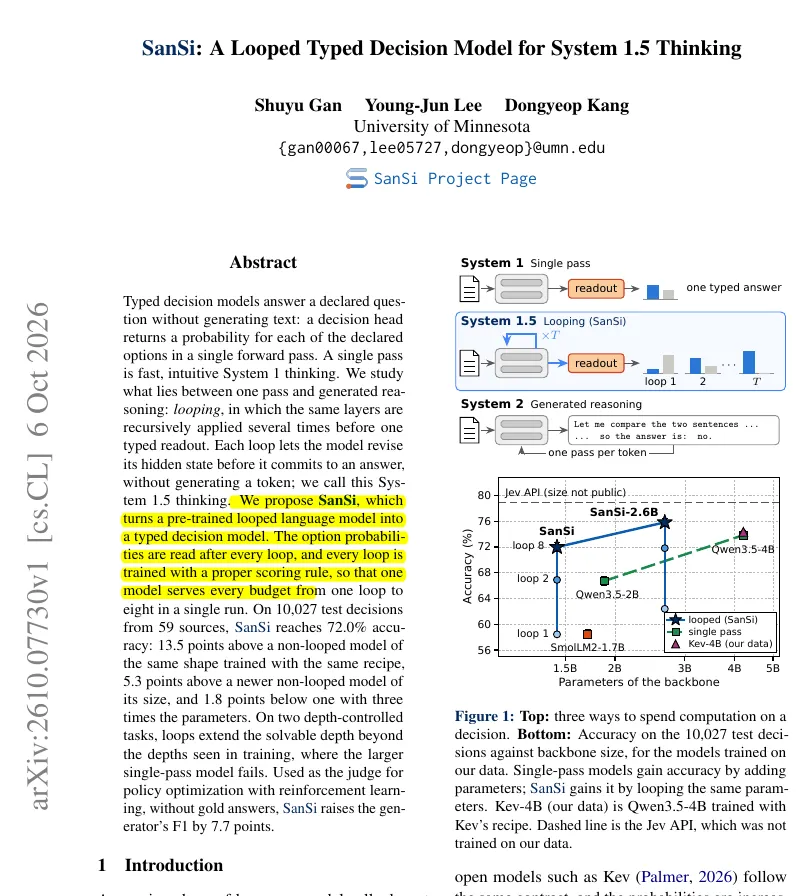
研究提出 SanSi 框架,让预训练的小模型(如 Ouro-1.4B)在单次推理中循环复用同一组网络层多次以完成复杂决策。实验显示,该机制使模型在 10,027 个测试决策中的准确率达到 72.0%,显著高于同规模无循环模型的 58.4%;在长链逻辑任务上,其表现甚至优于参数量大 3 倍的单遍推理模型。该方法为内存受限场景下的高精度轻量级决策提供了新路径。
报道全文原始报道全文
Rohan Paul (@rohanpaul_ai) · 2026-10-13 20
This paper finds that small decision models get far more accurate by rerunning the same layers several times before giving an answer.
Many LLM calls only need a choice, like spam or not spam. Typed decision models answer these in a single pass, which fails when a decision needs several dependent steps.
SanSi loops Ouro-1.4B, a model pretrained to reuse its layers, and reads option probabilities after each of 8 loops. Every loop is trained to answer, so the same model can stop anywhere from 1 to 8 loops.
On 10,027 test decisions, SanSi scored 72.0% versus 58.4% for a same-shape model without loops, at 7.7x the compute. On liar chains longer than any seen in training, it reached 72.6% while a 4.2B single-pass model scored 50.0%, the chance level.
If memory limits your decision-style calls, try a looped small model before moving to a model 3x larger.