▲ Ricursive Intelligence just released Ripple-65B Preview, a 65B dense open-weight model that beats ...
▲ Marktechpost AI · 2026-11-04 21:05 ▲ Ricursive Intelligence just released Ripple-65B Preview, a 65B dense open-weight model that beats US open models up to 15x its size on agentic coding. The key idea is going dense instead of MoE. Ricursive trained a thin, deep Transformer (80 layers, dmodel 5120) with extra attention heads. Simpler infrastructure let a 5-person team hold 40% MFU with no custom kernels. It scores 80.5 on Terminal-Bench 2.1, vs 80.1 for Reflection Beam (501B) and 76.4 for Meta...
报道正文
▲ Marktechpost AI · 2026-11-04 21
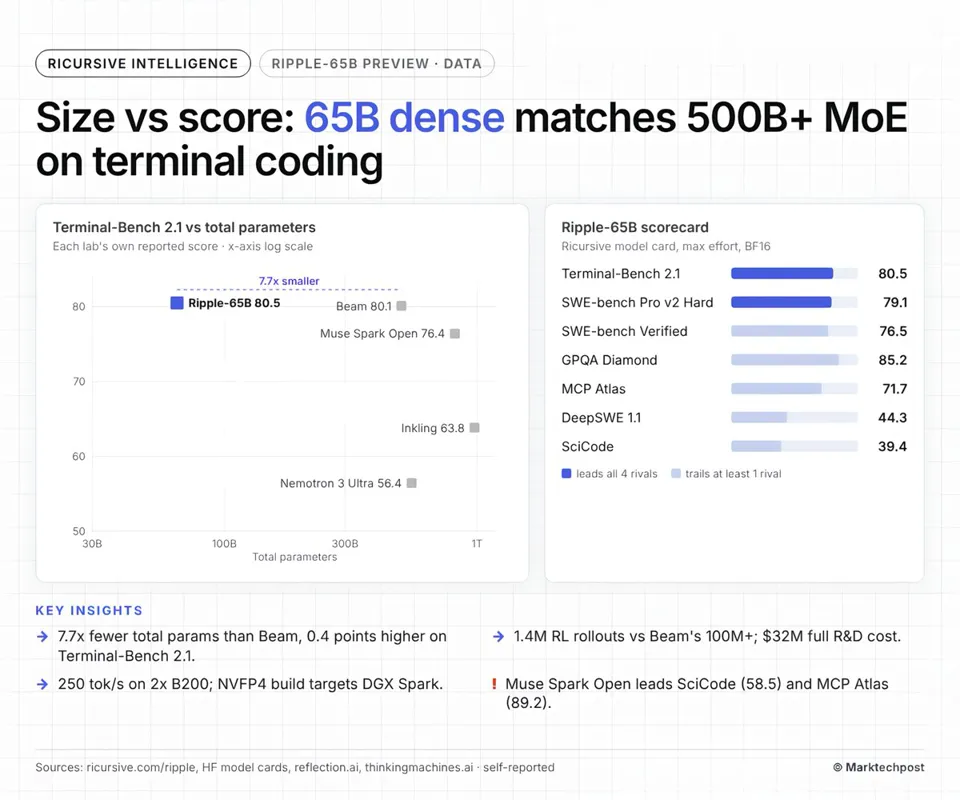
▲ Ricursive Intelligence just released Ripple-65B Preview, a 65B dense open-weight model that beats US open models up to 15x its size on agentic coding.
The key idea is going dense instead of MoE. Ricursive trained a thin, deep Transformer (80 layers, d_model 5120) with extra attention heads. Simpler infrastructure let a 5-person team hold 40% MFU with no custom kernels.
It scores 80.5 on Terminal-Bench 2.1, vs 80.1 for Reflection Beam (501B) and 76.4 for Meta Muse Spark Open (816B). It is a trade-off though: SciCode sits at 39.4 vs 58.5 for Muse Spark Open, and Beam leads on SWE-bench Verified (80.9 vs 76.5).
Apache 2.0 weights, 12T pretraining tokens, up to 1M context, $32M full R&D cost. An experimental NVFP4 build targets local machines like NVIDIA DGX Spark......
Full analysis: