研究发现大模型道德选择缺乏稳定价值排序
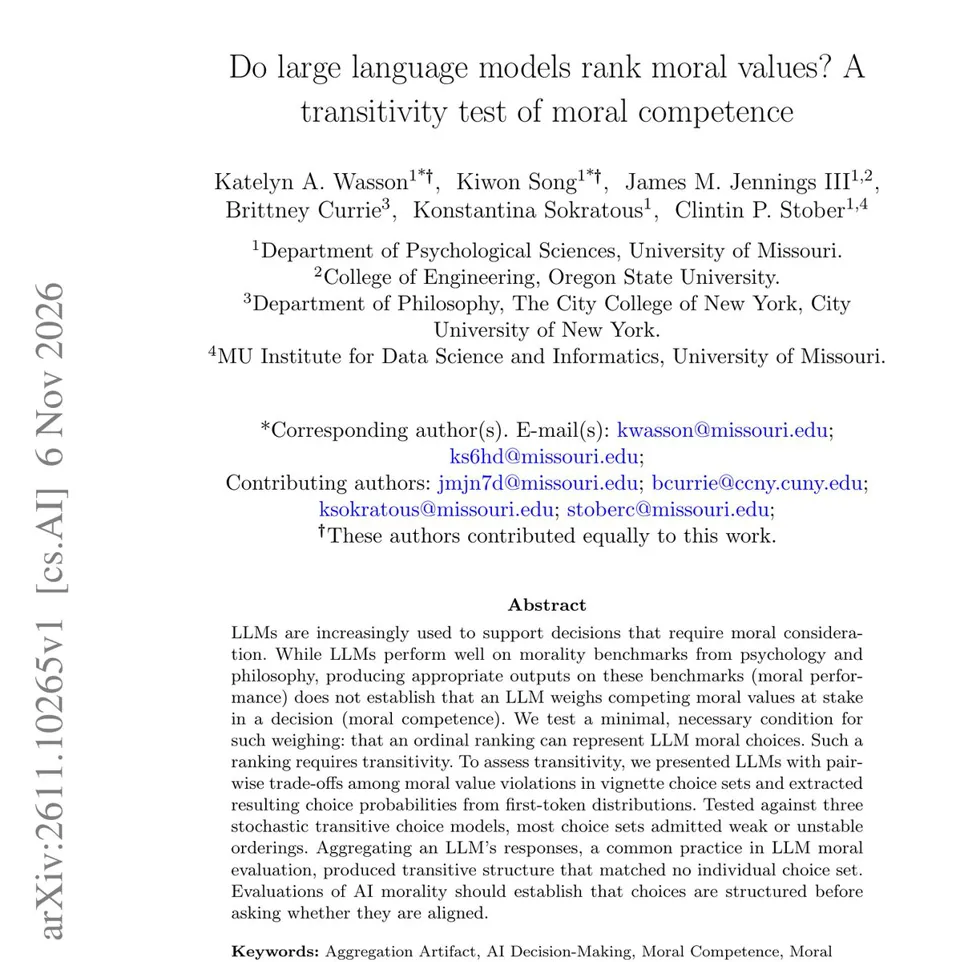
一项针对 GPT-5.2、Gemini、DeepSeek 等 5 个大模型的研究发现,模型在成对道德违规比较中缺乏一致的价值排序:调换选项顺序后,30 个测试块中有 26 个的排序发生改变。更关键的是,对多次回答取平均会制造出一个看似合理、接近人类却并不对应任何单次测试结果的虚假道德层级,因此模型的道德对齐分数需在单次提示与两种选项顺序下均保持排序一致才可信。
报道正文
Rohan Paul (@rohanpaul_ai) · 2026-11-11 04
This paper finds that LLM moral choices often lack a stable ranking of values, and averaging their answers creates a fake, human-like moral hierarchy.
Many studies conclude that LLMs hold sensible moral values because they do well on morality tests. But good answers do not show that a model weighs competing values against each other.
The researchers gave 5 LLMs, including GPT-5.2, Gemini, and DeepSeek, pairs of moral violations and asked which was worse. They read each answer's probability straight from the model's next-token output, then tested whether the choices fit a consistent ranking.
Reversing the order of the 2 options changed the ranking in 26 of 30 test blocks. After averaging, 4 of 5 models showed a clean, nearly identical ranking that matched no individual test set.
Before trusting a model's moral alignment scores, check that its choices hold a consistent ranking on individual prompts and both answer orders, without averaging.