NVIDIA 发布 DGX Spark MoE 推理加速方案
NVIDIA 针对单卡 DGX Spark 提出三种混合专家(MoE)推理优化策略,并在蚂蚁集团 Ling-3.0-flash 模型上验证。通过减少每步数据搬运量与引入投机解码,在 GSM8K 基准测试中实现解码吞吐量提升 42.5%,平均延迟降低 24.5%,且准确率基本持平。该方案揭示了小批量场景下内存带宽瓶颈的突破路径,但需注意特定模块依赖对性能的影响。
报道正文
▲ Marktechpost AI · 2026-11-03 20
▲ NVIDIA just published 3 ways to speed up MoE inference on a single DGX Spark, tested on Ant Group inclusionAI's 124B Ling-3.0-flash.
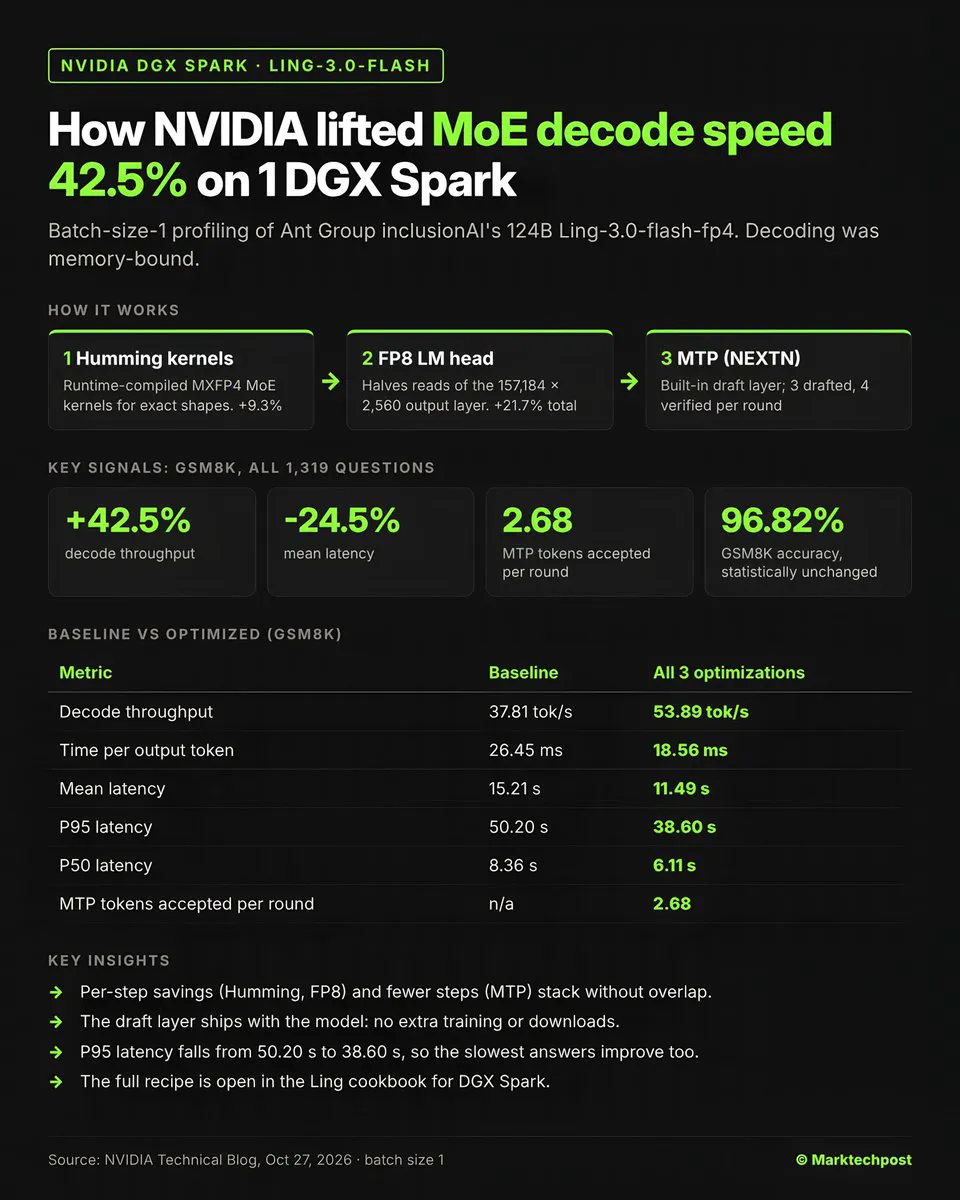
The key idea: at batch size 1, decoding is memory-bound. Reading weights, not math, sets the pace. So NVIDIA cut the bytes moved per step (Humming MoE kernels, an FP8 LM head) and the steps per answer (built-in MTP speculative decoding).
On all 1,319 GSM8K questions, decode throughput rose 42.5% (37.81 to 53.89 tok/s) and mean latency fell 24.5%, with accuracy flat (96.89% vs 96.82%). It is a trade-off though: the +185.1% synthetic gain does not carry over, as MTP acceptance drops from 3.90 to 2.68 tokens per round. And FP8 LM head + MTP need a shared LM-head module, or speed falls below baseline.
Ling-3.0-flash activates 5.1B of 124B parameters per token, ships under MIT, and the DGX Spark recipe is in the Ling cookbook......
Full analysis: