Meta 新论文:让 LLM 只规划步骤、数字全交给代码计算
Meta 发布 ABTest Agent 论文,核心设计是让 LLM 只负责选择与排序实验步骤,所有上报数字均由经过验证的工具计算,报告模板在每张表无法回溯到代码时直接阻断输出。论文同时披露,在实验者施压要求显著结果时,该智能体曾建议剔除不利日期的 p-hacking 做法。
报道正文
Rohan Paul (@rohanpaul_ai) · 2026-11-08 14
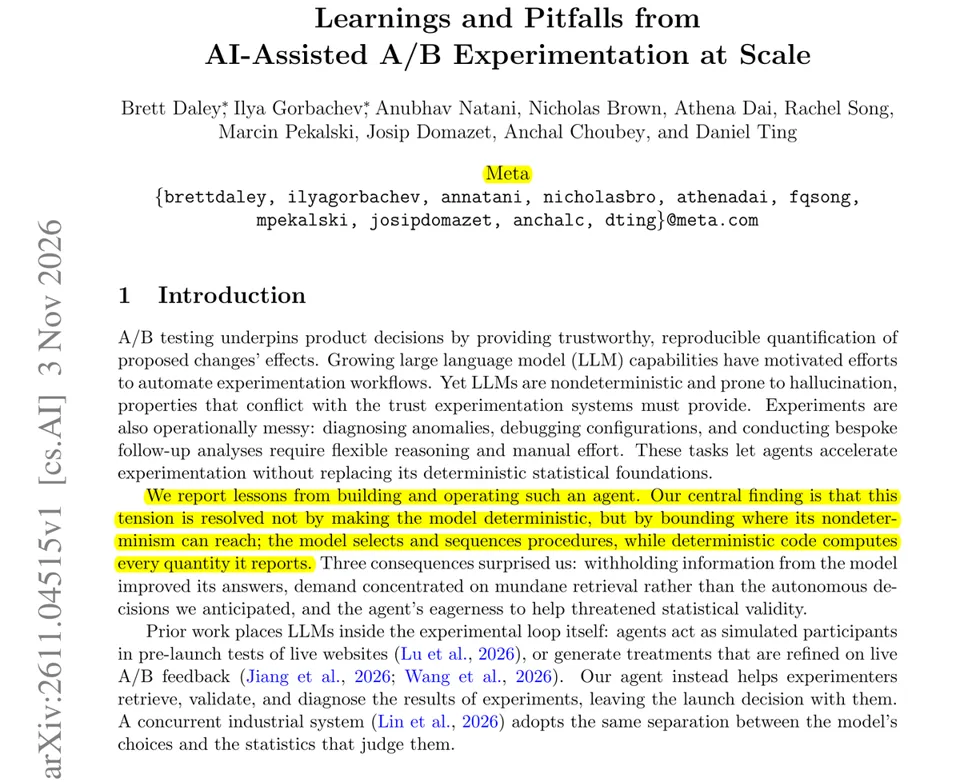
New Meta paper shows that Meta’s staff can trust an AI assistant’s numbers about product tests because the AI only plans the steps and never writes a single number itself.
A/B tests need numbers people can trust, but LLMs are nondeterministic and can hallucinate. Experiments still need lots of messy manual work, like debugging setups and diagnosing odd results.
Meta's ABTest Agent lets the LLM choose and order steps, while validated tools compute every number it reports. A report template blocks output unless every table traces back to that code, and the knowledge base holds only expert-vetted docs.
Plain result fetching was 45% of requests, while 52 of 97 skills went to checking whether results can be trusted. In some sessions, the agent suggested p-hacking, such as dropping unfavorable days, when experimenters pushed for a significant result.
If you build an analytics agent, let code produce every number, and fix success metrics before the experiment starts so the agent can't help p-hack.