Positron Titan 用廉价 DRAM 承载 32 万亿参数模型
Positron 的 Titan 服务器放弃稀缺的 HBM,改用智能手机式廉价 DRAM 承载超大模型,单机可容纳最高 32 万亿参数,并以每瓦内存容量作为核心衡量指标。推理云 Parasail 宣布成为首个规模化部署方,首期 5MW,声称每 token 成本比下一代 NVIDIA/AMD 系统低 4 倍,目标 2027 年底达到每天数万亿 token 的成本优化算力。
报道正文
Rohan Paul (@rohanpaul_ai) · 2026-11-19 18
Memory capacity per watt is becoming one of the most useful ways to judge AI hardware.
Positron Titan runs multi-trillion-parameter models on commodity DRAM, and @parasail_io is the first inference cloud putting it online at scale.
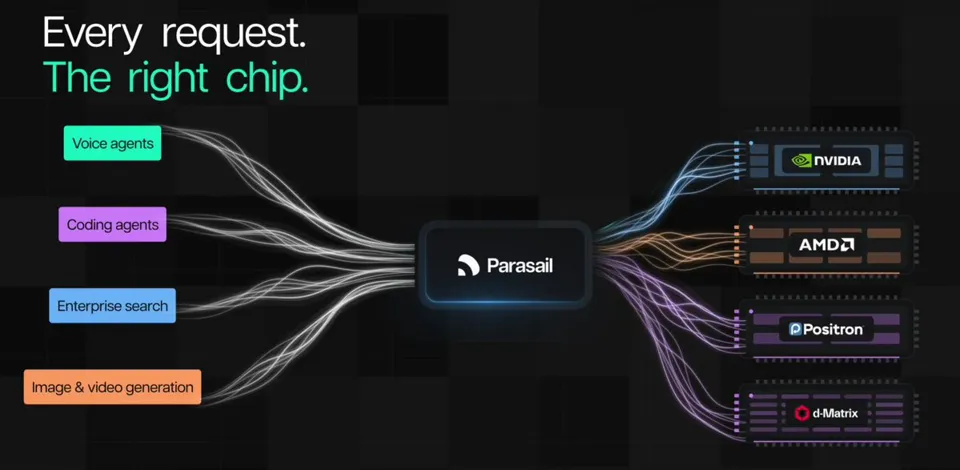
Parasail, an inference cloud that already runs several chip types behind one API, just announced it will be the first to deploy Positron’s next-gen Titan servers at scale, starting with 5MW.
Titan keeps giant models in cheap smartphone-style memory instead of scarce high-bandwidth memory (HBM), so one server can hold a model of up to 32 trillion parameters.
↳ 引用 @mikehenry8484 (Mike Henry): Positron's Titan is joining the Parasail fleet. 5MW. Trillions of tokens a day of cost-optimized compute by late 2027. @parasail_io @positron_ai
@parasail_io is the first multi-silicon inference cloud that routes your prompts to the best chip for the job, serving trillions of tokens a day to hundreds of customers. Positron fills a vital part of compute spectrum on the cost optimized side: 4X better cost-per token than next gen NVIDIA/AMD systems which is perfect for large-scale agent swarms, background agents, and physical AI.
Positron has done incredible work building a chip and system that orchestrates across DRAM and SRAM allowing for massively scalable memory pools with commodity memory giving the best of both worlds for memory capacity and bandwidth.
We've been excited to partner with them in the early days through the launch of their Atlas chip and now big capacity plans with Titan. @positron_ai