Hugging Face 优化推理 API 提速百倍
Hugging Face 宣布其托管的加速推理 API 实现了高达 100 倍的 Transformer 模型推理速度提升。该优化旨在解决大规模模型在生产环境部署中的性能与扩展性难题,主要面向付费企业客户。
报道正文
本文目录4 个章节
我们如何将 🤗 API 客户的 Transformer 推理速度提升 100 倍
发布于 2021 年 1 月 18 日 在 GitHub 上更新 点赞 1
本文也有简体中文版本:简体中文。
🤗 Transformers 已成为全球数据科学家探索最先进 NLP 模型并构建新 NLP 功能的默认库。它提供了超过 5,000 个预训练和微调模型,涵盖 250 多种语言,无论你使用哪种框架,都能轻松访问这个丰富的试验场。
虽然在 🤗 Transformers 中实验模型很容易,但将这些大型模型以最高性能部署到生产环境,并管理一个能随使用量扩展的架构,对任何机器学习工程师来说都是一个艰巨的工程挑战。
正是这种 100 倍的性能提升和内置的可扩展性,促使我们的托管 Accelerated Inference API 订阅用户选择在其之上构建他们的 NLP 功能。为了获得最后 10 倍的性能提升,优化必须是底层的、针对特定模型的,并且要适配目标硬件。
本文将分享我们的一些方法,旨在为客户榨取每一滴计算潜力。🍋
实现第一个 10 倍加速
优化之旅的第一阶段是最容易实现的,关键在于结合使用 Hugging Face 库 提供的最佳技术,且不受目标硬件的限制。
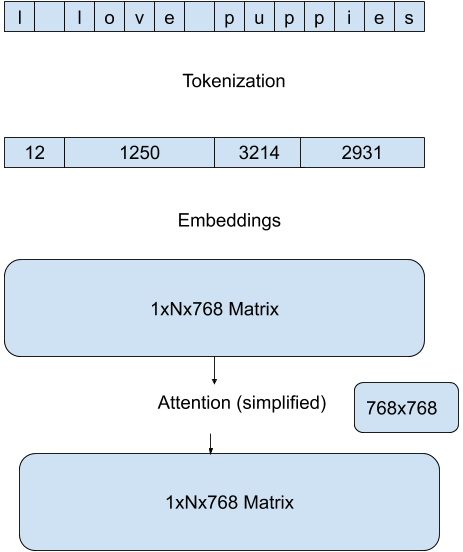
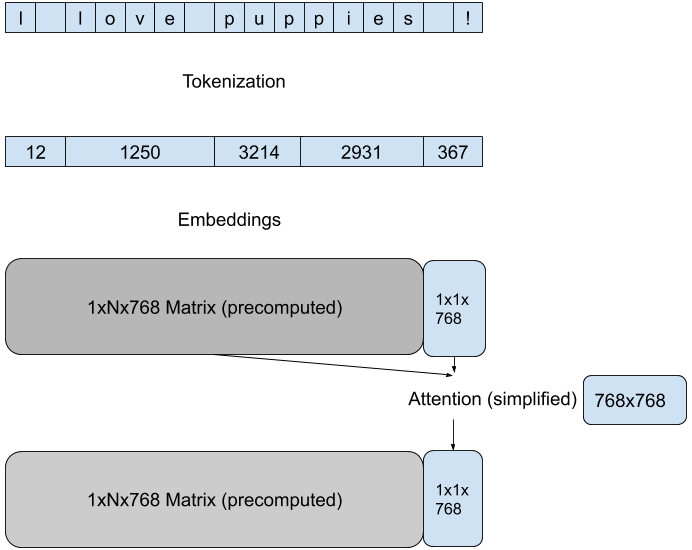
我们利用 Hugging Face 模型 pipelines 中最有效的方法,以减少每次前向传播期间的计算量。这些方法取决于模型的架构和目标任务。例如,对于 GPT 架构上的文本生成任务,我们通过专注于每次传递中最后一个 token 的新注意力,来降低注意力矩阵计算的维度:
| - | 朴素版本 | 优化版本 |
|---|---|---|
| - |  |  |
在推理过程中,分词(Tokenization)往往是效率瓶颈。我们采用 🤗 Tokenizers 库中最高效的方法,结合模型分词器的 Rust 实现与智能缓存机制,使整体延迟获得高达 10 倍的加速。
通过利用 Hugging Face 库的最新特性,针对给定的模型/硬件组合,我们实现了相比开箱即用部署方案稳定可靠的 10 倍加速。由于 Transformers 和 Tokenizers 通常每月都会发布新版本,我们的 API 客户无需不断适应新的优化机会,他们的模型只会运行得越来越快。
编译制胜:难以获得的 10 倍加速
接下来是最具挑战性的部分。为了获得最佳性能,我们需要修改模型并针对特定的推理硬件进行编译。硬件的选择取决于模型本身(内存占用大小)和需求特征(请求批处理)。即使使用同一模型提供预测服务,某些 API 客户可能更受益于加速的 CPU 推理,而另一些则更适合加速的 GPU 推理,两者分别应用不同的优化技术和库。
一旦为特定用例选定计算平台,我们就可以着手工作。以下是可以在静态图中应用的一些 CPU 专属技术:
- 图优化(移除未使用的流程)
- 层融合(利用特定的 CPU 指令集)
- 操作量化
直接使用开源库中的开箱即用函数(例如 🤗 Transformers 配合 ONNX Runtime)无法产生最佳结果,或者可能导致显著的精度损失,尤其是在量化阶段。没有万能药,每种模型架构的最佳路径都各不相同。但深入钻研 Transformers 代码和 ONNX Runtime 文档,我们可以让各项条件完美契合,从而实现又一个 10 倍的加速。
不公平的优势
The Transformer architecture was a decisive inflection point for Machine Learning performance, starting with NLP, and over the last 3 years the rate of improvement in Natural Language Understanding and Generation has been steep and accelerating. Another metric which accelerated accordingly, is the average size of the models, from the 110M parameters of BERT to the now 175Bn of GPT-3.
This trend has introduced daunting challenges for Machine Learning Engineers when deploying the latest models into production. While 100x speedup is a high bar to reach, that’s what it takes to serve predictions with acceptable latency in real-time consumer applications.
To reach that bar, as Machine Learning Engineers at Hugging Face we certainly have an unfair advantage sitting in the same (virtual) offices as the 🤗 Transformers and 🤗 Tokenizers maintainers 😬. We are also extremely lucky for the rich partnerships we have developed through open source collaborations with hardware and cloud vendors like Intel, NVIDIA, Qualcomm, Amazon and Microsoft that enable us to tune our models x infrastructure with the latest hardware optimizations techniques.
If you want to feel the speed on our infrastructure, start a free trial and we’ll get in touch. If you want to benefit from our experience optimizing inference on your own infrastructure participate in our 🤗 Expert Acceleration Program.