研究称廉价验证器可匹配前沿 LLM 的 RAG 校验精度
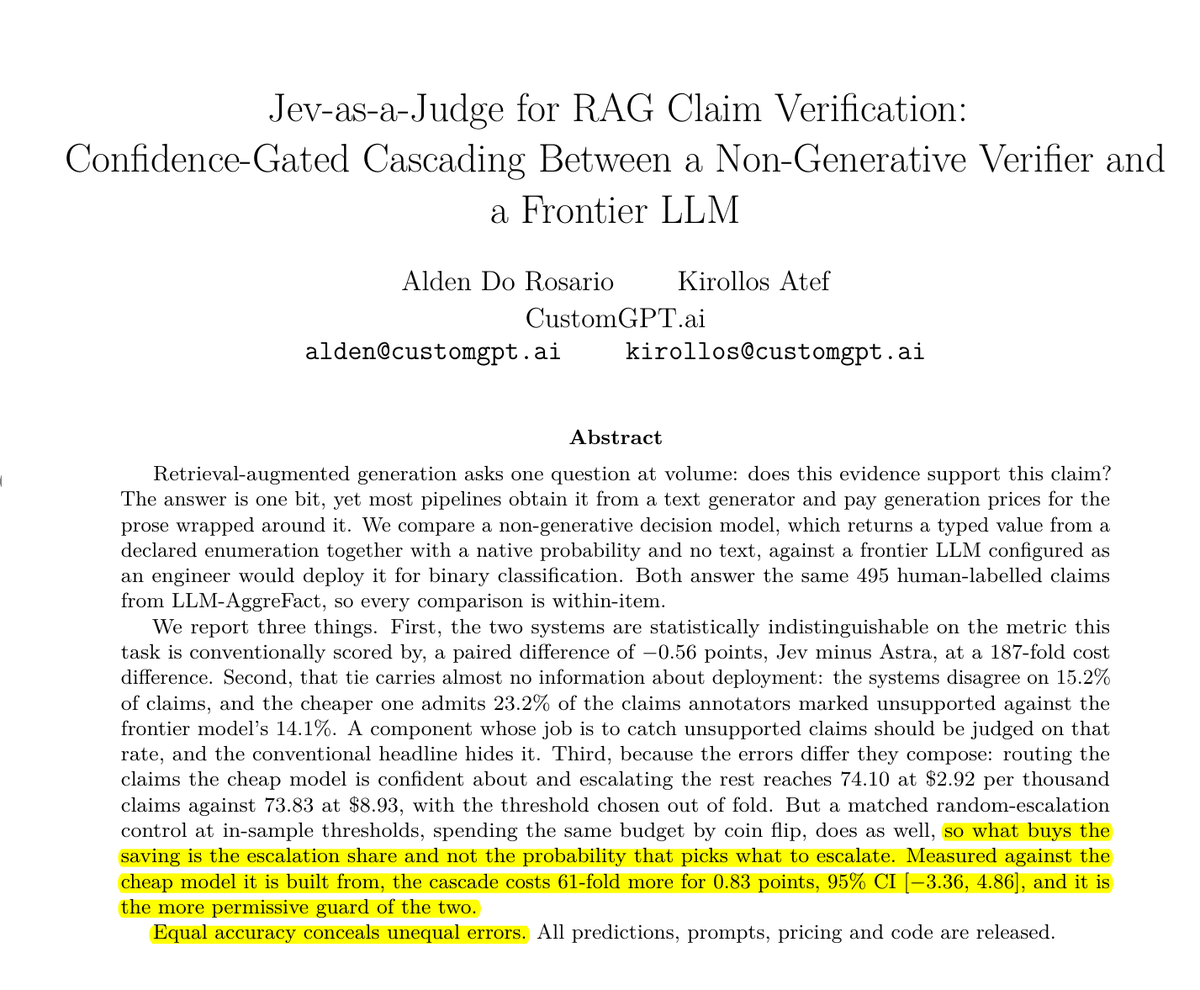
最新研究表明,专用分类模型 Jev 在检索增强生成(RAG)声明校验任务中,能以 1/187 的成本达到接近 GPT-6 Astra 的整体准确率。然而,Jev 对无依据声明的误判率显著更高,且级联策略带来的成本节省与随机分流无异。该发现提示开发者在选择校验工具时,应重点关注“无依据声明通过率”而非仅看整体准确率。
报道正文
This paper finds that a cheap verifier can match a frontier LLM's accuracy at checking RAG claims, while letting more unsupported claims slip through.
RAG pipelines keep asking whether evidence supports a claim, a simple yes or no. Most teams get that answer from a text-generating LLM at generation prices.
They tested Jev, which returns only a label and a probability, against GPT-6 Astra on 495 human-labelled claims. They also built a cascade where Jev answers confident claims and passes the rest to Astra.
Jev landed within 0.6 points of Astra's accuracy at 187 times lower cost, but it approved 23.2% of unsupported claims against Astra's 14.1%. The cascade also cut Astra's bill, yet sending the same share of claims to Astra at random saved about as much.
Before picking a claim checker for a RAG product, measure how often it approves unsupported claims, since headline accuracy hides that.