Baidu Open-Sources Unlimited OCR 2 for Long Document Parsing
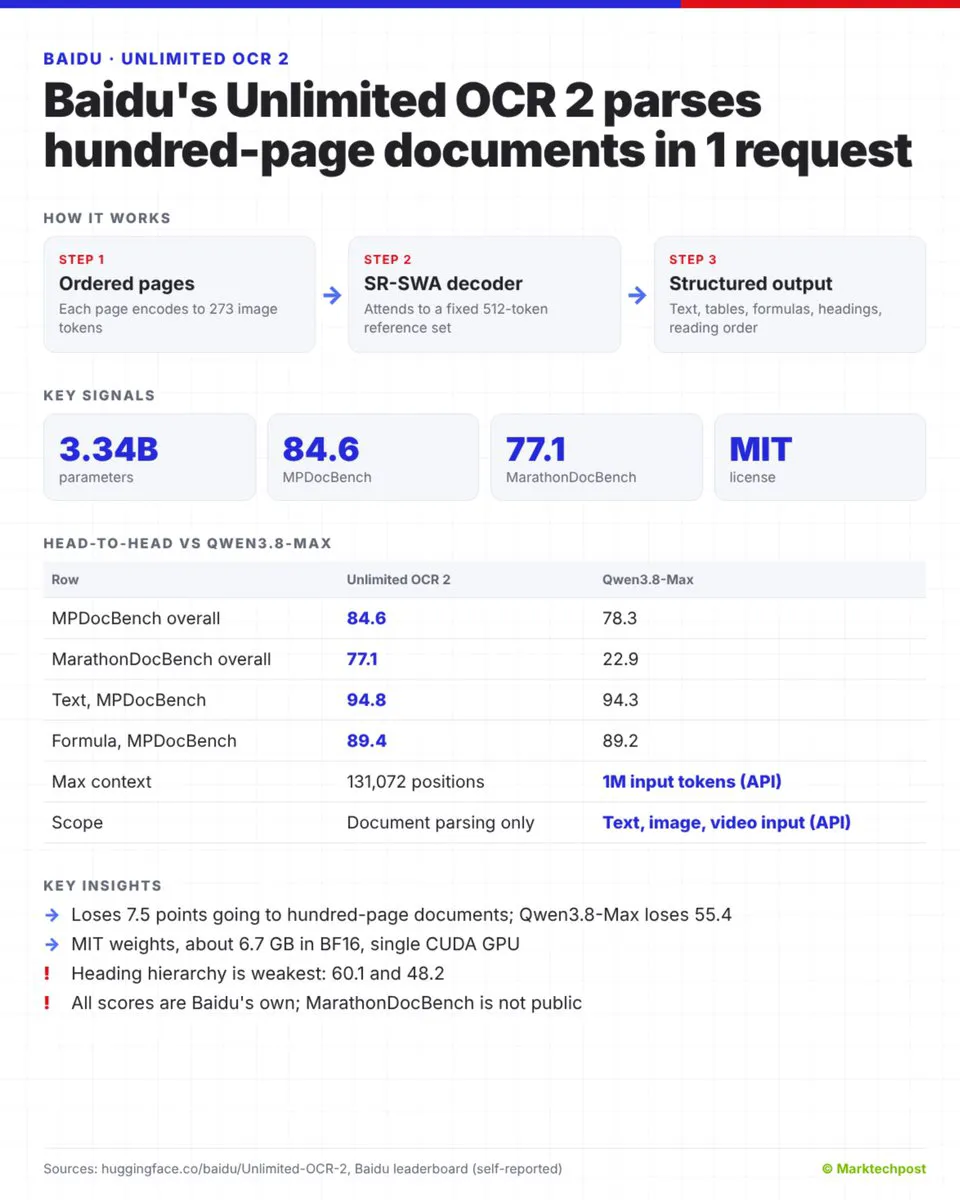
Baidu has open-sourced Unlimited OCR 2, a 3.3B parameter model that parses hundreds of pages in a single request using Sparse Reference Sliding Window Attention (SR-SWA). It significantly outperforms Kimi-K3 and Qwen3.8-Max on long-document benchmarks like MarathonDocBench, maintaining constant decoding latency and memory usage as document length increases.
Full Report
▲ Marktechpost AI · 2026-10-27 05
▲ Baidu just open-sourced Unlimited OCR 2, a 3B OCR model that parses books and reports of hundreds of pages in a single request.
The key innovation is SR-SWA (Sparse Reference Sliding Window Attention). Instead of scanning an ever-growing KV cache, the decoder attends to a fixed set of working references, 512 tokens in Baidu's example. Per-step decoding latency and memory stay nearly constant as the document grows.
On MarathonDocBench (hundreds of pages) it scores 77.1 overall, against 33.7 for Kimi-K3 and 22.9 for Qwen3.8-Max. On MPDocBench (dozens of pages) it leads Qwen3.8-Max 84.6 to 78.3. It is a trade-off though: heading hierarchy is its weakest metric at 48.2 on long documents, the reference pool is lossy, and every score is self-reported.
3.34B parameters, MIT license, about 6.7 GB of BF16 weights. Runs on Transformers, with a customized SGLang build for serving......
Full analysis: