Zyphra Introduces ZHA Hierarchical Attention for Efficient Long-Context Inference
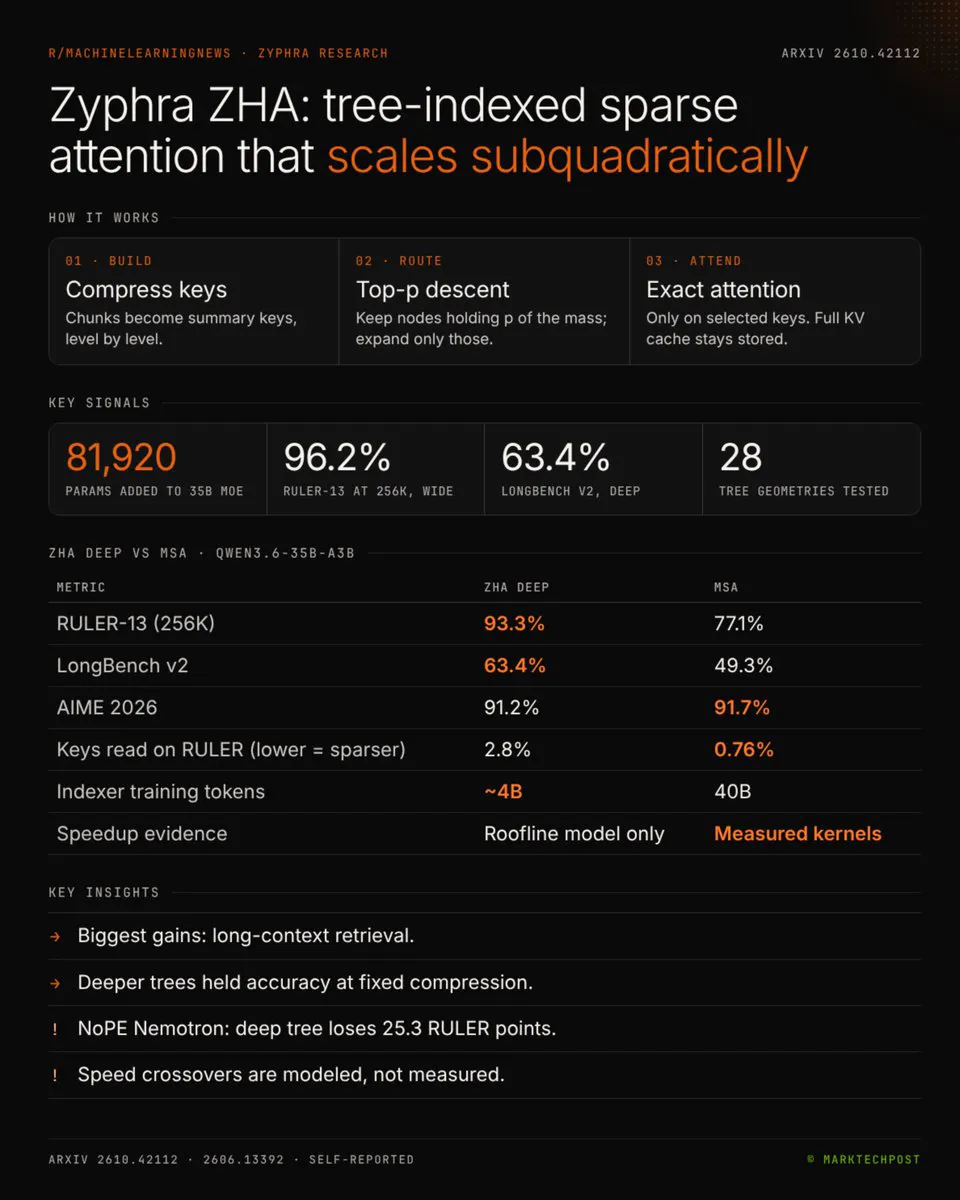
Zyphra introduces ZHA (Hierarchical Attention), a sparse attention method utilizing a tree structure over the KV cache for efficient retrieval. On Qwen3.6-35B, it outperforms dense attention on LongBench v2 while reading only ~1.1% of keys, with minimal training overhead (optimizing just 80k parameters). Although trade-offs exist in specific benchmarks like Terminal-Bench, it offers a novel architectural approach to long-context processing.
Full Report
▲ Marktechpost AI · 2026-11-03 01
▲ Zyphra just introduced ZHA (Zyphra Hierarchical Attention), a sparse attention method where finding the relevant tokens is itself sparse.
The key idea is a tree over the KV cache. Chunks of keys are compressed into summary keys by 16 learned reference queries, then compressed again, level by level. Each query walks the tree top-down with top-p routing and runs exact attention only on the leaves it reaches.
On a frozen Qwen3.6-35B-A3B, the wide tree scores 96.2% on RULER-13 at 256K vs 96.0% dense and 77.1% for MiniMax Sparse Attention. On LongBench v2 the deep tree hits 63.4% vs 58.0% dense, reading about 1.1% of keys. It is a trade-off though: the deep tree drops to 46.7% on Terminal-Bench 2.1 (dense 49.9%), and on NoPE Nemotron it loses 25.3 RULER points.
Conversion trains only 81,920 parameters with about 4B tokens of KL distillation. The 48K and 0.48M crossovers vs dense and MSA come from a roofline model, not shipped kernels......
Full analysis: