Simple Few-Shot Prompting Lets Small Open Models Match Complex Methods
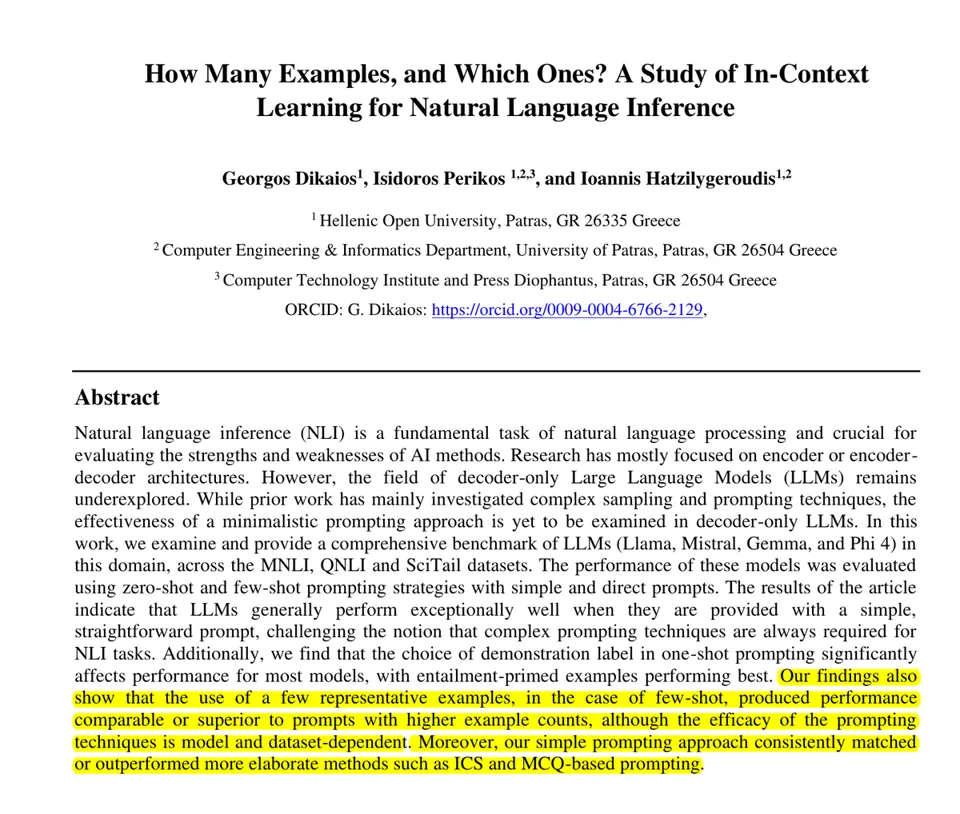
A paper finds that on natural language inference (NLI), a single short direct prompt with a few in-context examples lets small open models such as Gemma 2 9B, Mistral 7B and Llama 3.1 8B match or beat prior methods that relied on complex prompting and sampling tricks. Mistral 7B surpassed the 63.4% MNLI accuracy reported by a published in-context sampling method, and performance with 1 example was roughly equal to 15 examples.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-11-11 01
This paper finds that a short, direct prompt with a few examples (In-Context Learning) lets small open LLMs match more complex prompting methods on natural language inference.
The task, called NLI, asks whether one sentence follows from another, contradicts it, or is unrelated. Earlier LLM work on it leaned on complex prompting and sampling tricks, assuming more examples help.
They tested 5 small open models, including Gemma 2 9B, Mistral 7B and Llama 3.1 8B, on 3 NLI datasets. Each got 1 short, direct prompt with 0 to 15 examples and no reasoning steps.
Mistral 7B beat the 63.4% MNLI accuracy that a published in-context sampling method got with the same model. Gemma 2, Llama 3.1 and Mistral scored about the same with 1 example or 15 on MNLI and SciTail.