简单少样本提示即可让小模型追平复杂方法
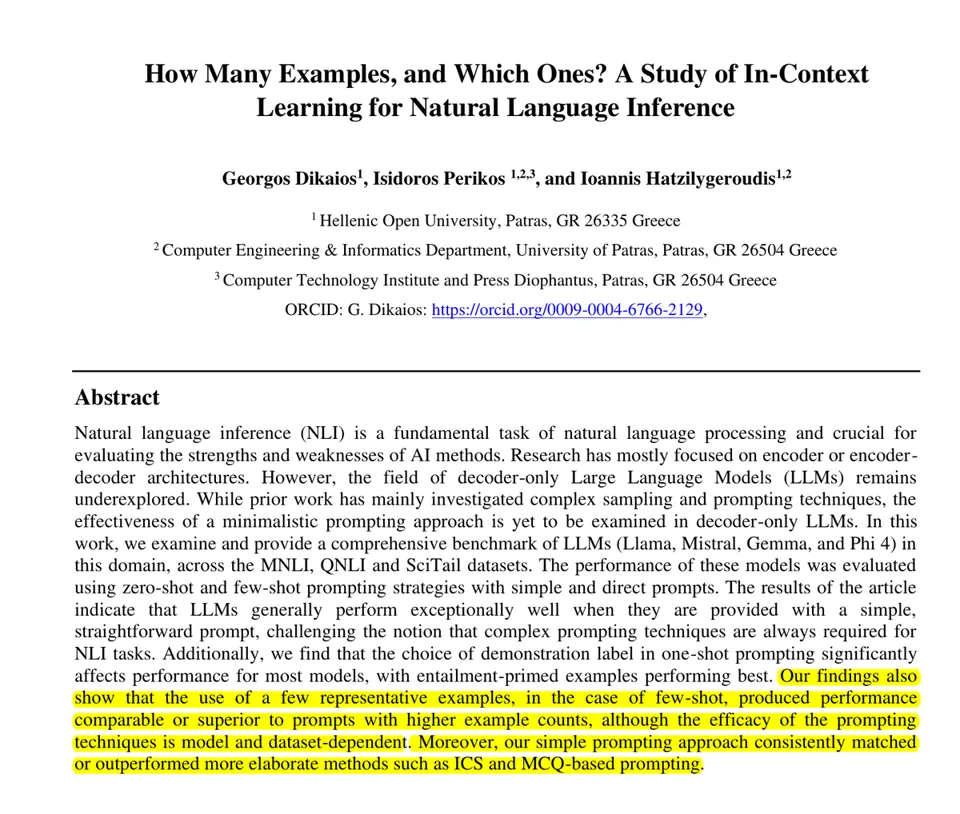
一篇论文发现,在自然语言推理(NLI)任务上,仅用一条简短直接的提示加少量示例(上下文学习),就能让 Gemma 2 9B、Mistral 7B、Llama 3.1 8B 等小型开源模型达到甚至超过以往依赖复杂提示与采样技巧的方法。Mistral 7B 在 MNLI 上超过已发表的上下文采样方法所取得的 63.4% 准确率,且 1 个示例与 15 个示例效果基本相当。
报道正文
Rohan Paul (@rohanpaul_ai) · 2026-11-11 01
This paper finds that a short, direct prompt with a few examples (In-Context Learning) lets small open LLMs match more complex prompting methods on natural language inference.
The task, called NLI, asks whether one sentence follows from another, contradicts it, or is unrelated. Earlier LLM work on it leaned on complex prompting and sampling tricks, assuming more examples help.
They tested 5 small open models, including Gemma 2 9B, Mistral 7B and Llama 3.1 8B, on 3 NLI datasets. Each got 1 short, direct prompt with 0 to 15 examples and no reasoning steps.
Mistral 7B beat the 63.4% MNLI accuracy that a published in-context sampling method got with the same model. Gemma 2, Llama 3.1 and Mistral scored about the same with 1 example or 15 on MNLI and SciTail.