Rohan Paul (@rohanpaul_ai) · 10/23/2026, 15:59:49
Harvard Study: AI Peer Reviews Outperform Human Experts in Blind Tests
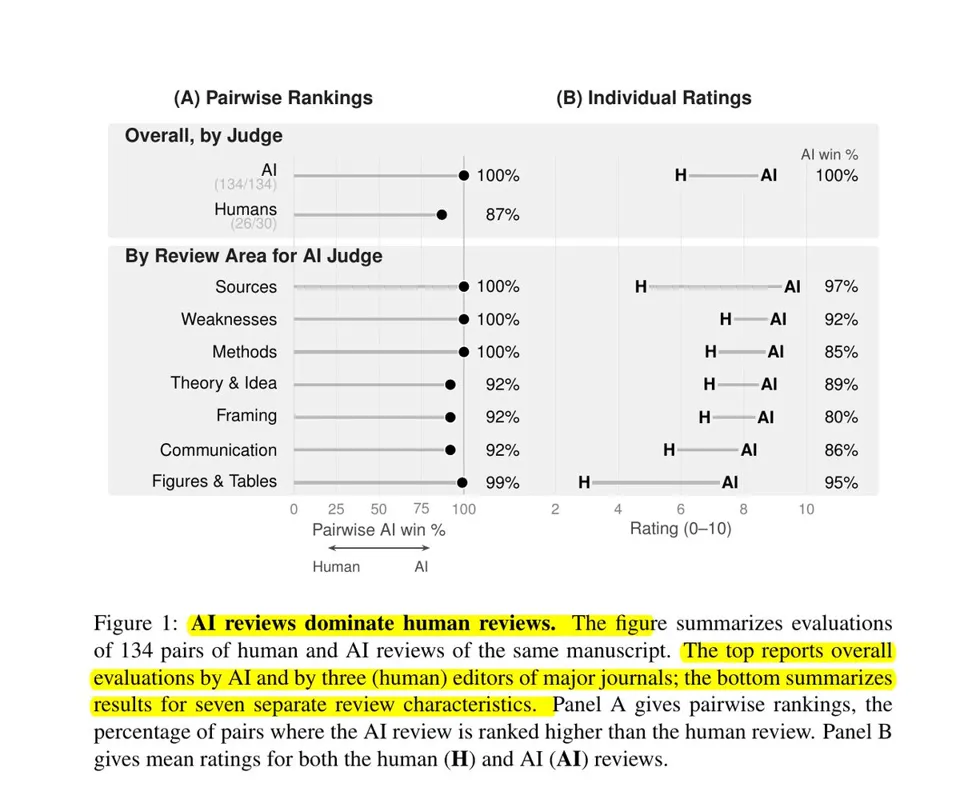
A new Harvard study reveals that Claude Opus 4.8-generated peer reviews outperform top human experts across all tested metrics. In blind evaluations by GPT-5.5 and journal editors, AI reviews were preferred 87% of the time with a significantly lower factual error rate (5.5% vs. 15.9%), suggesting AI is ready for first-pass full reviews.
SOURCE COVERAGEFull Original Report
Rohan Paul (@rohanpaul_ai) · 2026-10-23 07
Massive. New Harvard study finds that AI-written paper reviews now beat the best human peer reviews on every measure the authors tested.
Peer review is slow and often misses errors. Earlier studies concluded AI should only assist human reviewers, not replace them.
They used 134 reviews from rapidPeer, a Harvard service that pays expert reviewers well. Claude Opus 4.8 reviewed the same 1124 papers, and GPT-5.5 plus 3 former journal editors judged the pairs blind.
GPT-5.5 picked the AI review in all 132 decided pairs, and the editors picked it 87% of the time. Only 5.5% of the AI's claims about the paper were wrong, versus 15.9% for the human reviews.
Teams that depend on expert critique can now let AI do the first full review pass, and keep a human for the final decision.