Baidu Releases ERNIE 5.5 Flash Base, a 280B Sparse MoE Model
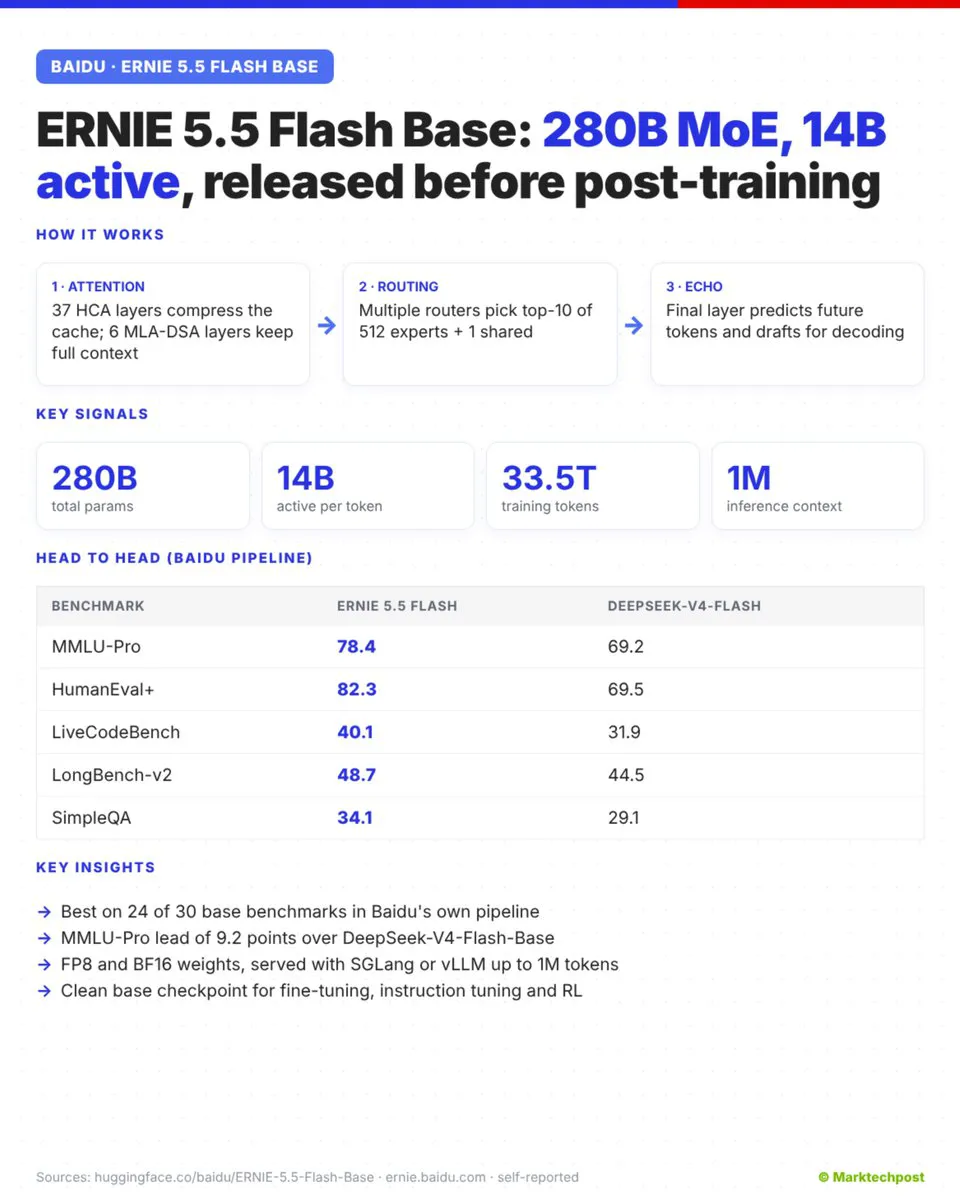
Baidu released ERNIE 5.5 Flash Base, a 280B-total, 14B-active sparse MoE model shipped directly from pre-training with no mid- or post-training. Efficiency is the design focus: 37 of 43 layers use Heavily Compressed Attention caching one entry per 128 tokens, multiple routers select top-10 of 512 experts, and the final layer doubles as a speculative-decoding draft model. Baidu self-reports gains over DeepSeek-V4-Flash-Base on MMLU-Pro and HumanEval+, but trails on HELMET-Rerank, and all numbers are self-reported.
Full Report
▲ Marktechpost AI · 2026-11-05 21
▲ Baidu just released ERNIE 5.5 Flash Base, a 280B sparse MoE model shipped straight from pre-training, with no mid- or post-training.
The key idea is efficiency by design. 37 of its 43 layers use Heavily Compressed Attention, caching 1 entry per 128 tokens. Multiple routers pick the top-10 of 512 experts, and the final layer doubles as a speculative-decoding draft model.
In Baidu's unified pipeline, it scores 78.4 on MMLU-Pro vs 69.2 for DeepSeek-V4-Flash-Base, and 82.3 vs 69.5 on HumanEval+. It is a trade-off though: it trails DeepSeek on HELMET-Rerank (56.2 vs 60.0), and every number is self-reported.
280B total, 14B active, 33.5T training tokens, 1M-token inference context, FP8 and BF16 weights.
Full analysis: