Alibaba Releases Qwen4-Max 2.4T-Parameter MoE Flagship
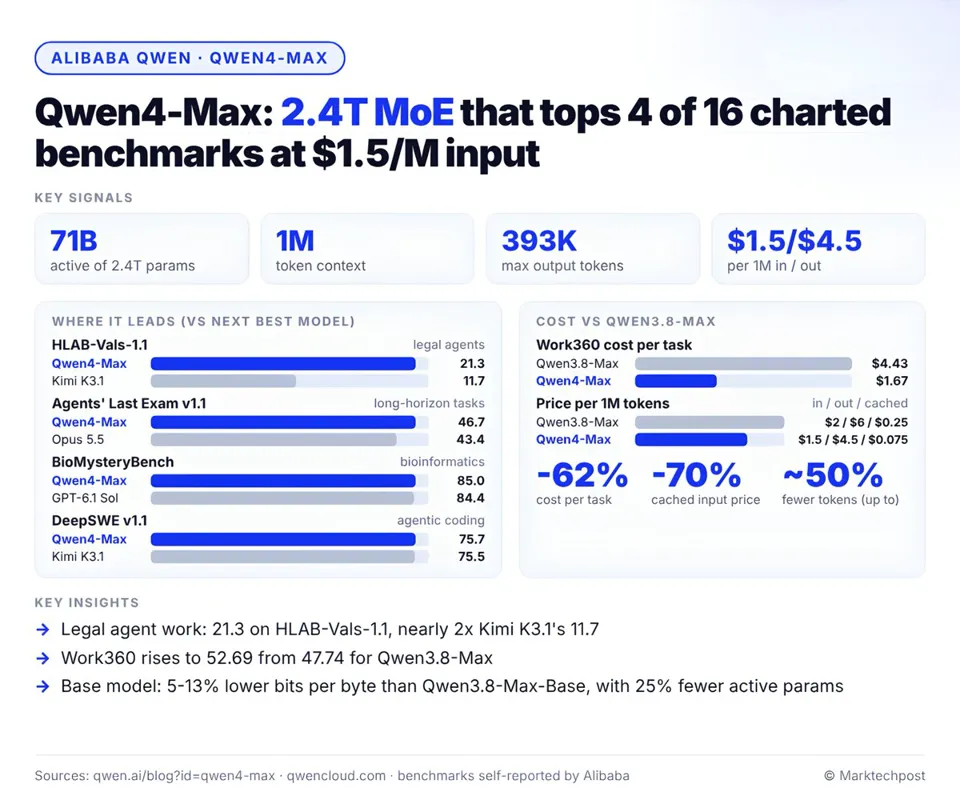
Alibaba released Qwen4-Max, a 2.4T-parameter sparse MoE flagship that activates only 71B parameters per token at $1.5 per million input tokens. Its rebuilt sparse MoE stack uses three Gated DeltaNet layers to compress history for each Qwen Sparse Attention layer, a lightweight indexer for context selection, plus four gated residual branches and 328B N-gram embedding parameters. It tops 4 of 16 benchmarks but trails Claude Opus 5.5 and Kimi K3.1 on coding and terminal tasks, a clear trade-off.
Related Entities
Full Report
▲ Marktechpost AI · 2026-11-16 09
▲ Alibaba just released Qwen4-Max, a 2.4T-parameter MoE flagship that runs only 71B parameters per token and costs $1.5 per million input tokens.
The key innovation is a rebuilt sparse MoE stack. 3 Gated DeltaNet layers compress history for each Qwen Sparse Attention layer, which picks context through a lightweight indexer. 4 gated residual branches and 328B N-gram Embedding parameters add capacity with little extra compute.
On Alibaba's chart it ranks first on 4 of 16 benchmarks, including HLAB-Vals-1.1 (21.3 vs 11.7 for Kimi K3.1) and DeepSWE v1.1 (75.7 vs 74.2 for Claude Opus 5.5). Work360 cost per task drops from $4.43 to $1.67. It is a trade-off though: ProgramBench sits at 31.5 vs 65.0 for Opus 5.5, and Terminal-Bench 4.0 at 48.5 vs 67.2 for Kimi K3.1.....
Full analysis: