LLMs Generate 3D Scenes as Code to Challenge Video Models
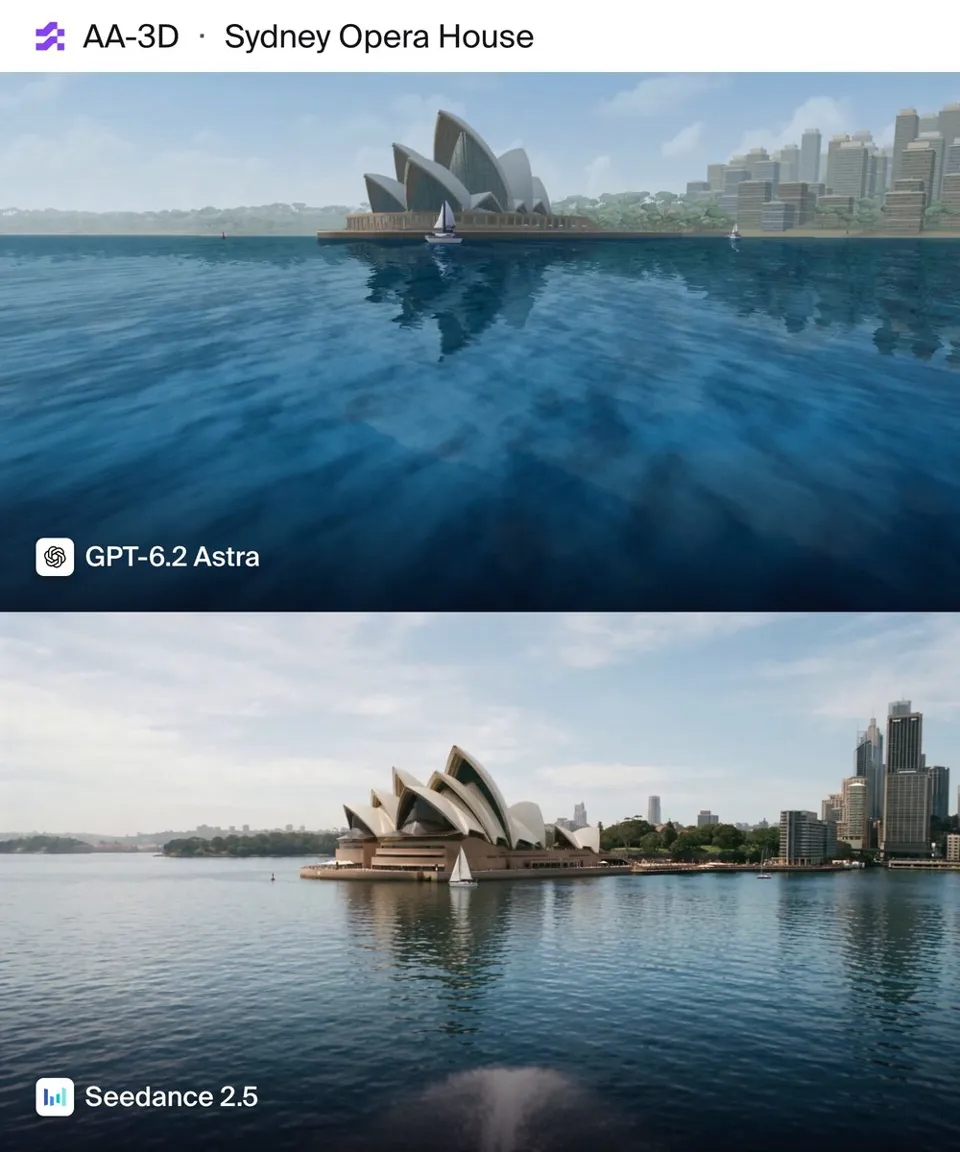
Artificial Analysis ran a head-to-head test asking OpenAI's GPT-6.2 Astra to build three 3D scenes (Sydney Opera House, an exploded mechanical watch, and a dragon attacking a medieval town) as three.js code, then flew a scripted camera through each in a browser at 15s, 1080p, 24fps. ByteDance's Dreamina Seedance 2.5 received the same camera path as a text prompt with route reference images at identical settings, probing whether LLMs can compete with dedicated video generation models.
Related Entities
Full Report
Artificial Analysis (@ArtificialAnlys) · 2026-11-20 00
Can language models make better videos than video models?
LLMs now make motion graphics, edit video as code and drive Blender to build 3D scenes. Can LLMs compete with video generation models?
We put GPT-6.2 Astra from @OpenAI, the current #1 on AA-3D, to the test, building the Sydney Opera House, an exploded mechanical watch, and a dragon attacking a medieval town as three.js code. We flew a scripted camera through each scene in a browser: 15 s, 1080p, 24 fps.
Dreamina Seedance 2.5 from @ByteDanceSeed_ got the same camera path as a text prompt with reference images of the route, at the same settings.
➤ Top: GPT-6.2 Astra (LLM, AA-3D)
➤ Bottom: Dreamina Seedance 2.5 (video model, AA-Video-T2V)