Artificial Analysis (@ArtificialAnlys) · 10/22/2026, 10:04:56
Medical Benchmarks: Anthropic Models More Complete, OpenAI More Accurate
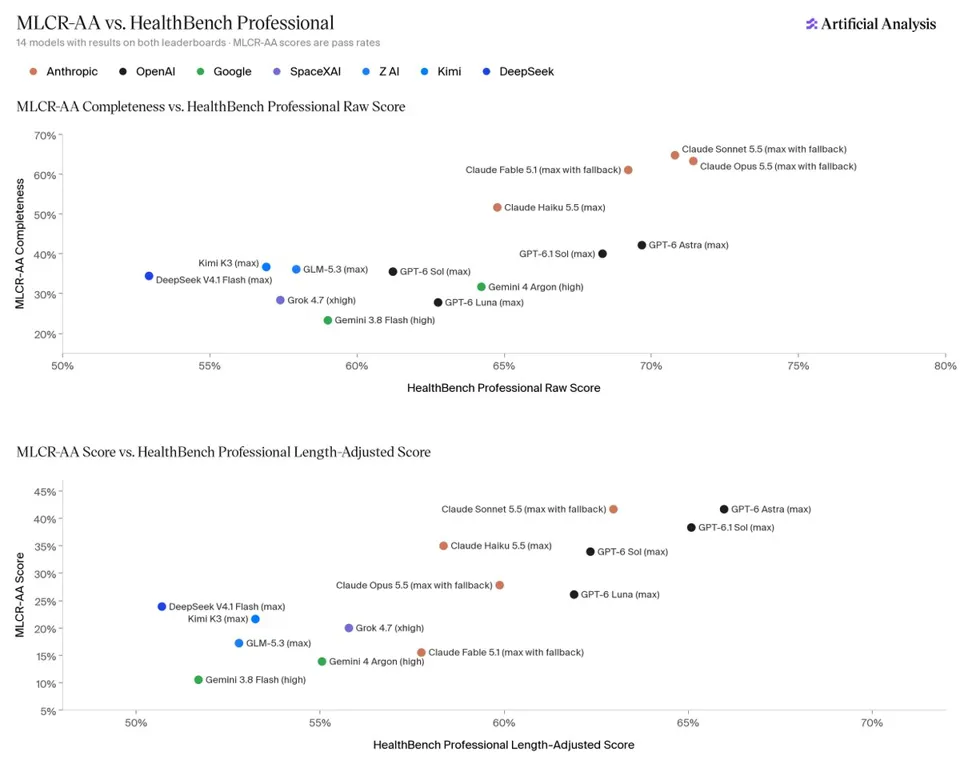
Artificial Analysis compared models on MLCR-AA and HealthBench Professional benchmarks. Results show Claude models lead in answer completeness, while GPT-6 Astra excels in accuracy and conciseness. When using composite scores that balance both metrics, GPT-6 Astra ties with Claude Sonnet 5.5 for the top spot.
SOURCE COVERAGEFull Original Report
Artificial Analysis (@ArtificialAnlys) · 2026-10-22 02
On MLCR-AA and HealthBench Professional, Anthropic models give the most complete answers but OpenAI models are more accurate and concise
We compared 14 models with results on both MLCR-AA, our leaderboard for @wisedocsai's Medical Long Context Reasoning benchmark, and @OpenAI's HealthBench Professional. MLCR-AA grades answers about long medical records on completeness (covering every key point of the expert's answer) and accuracy (no claim contradicting the record), and its score requires both. HealthBench Professional grades replies to clinicians against physician-written rubrics: the raw score is the share of rubric points earned, while the length-adjusted score penalizes longer answers.
Key takeaways:
➤ Anthropic models lead on completeness and raw score: Claude Sonnet 5.5, Opus 5.5 and Fable 5.1 (all max with fallback) from @AnthropicAI hold the top three MLCR-AA completeness scores, ~19-23 points ahead of the best OpenAI model, and Opus and Sonnet post the highest HealthBench Professional raw scores (71.4% and 70.8%), narrowly ahead of GPT-6 Astra (69.7%)
➤ OpenAI models lead on accuracy and conciseness: OpenAI models hold the top MLCR-AA accuracy scores. Longer answers are less likely to be judged accurate, as each extra claim is another chance to contradict the record: Anthropic models write ~4-6x more per answer than OpenAI models, and score 19-61% on accuracy against 89-97%
➤ The gap closes on scores that reward both: GPT-6 Astra (max) ties Claude Sonnet 5.5 for #1 on MLCR-AA and narrowly leads the HealthBench Professional length-adjusted score, while Claude Opus 5.5 falls from #1 on the raw score to #6 length-adjusted