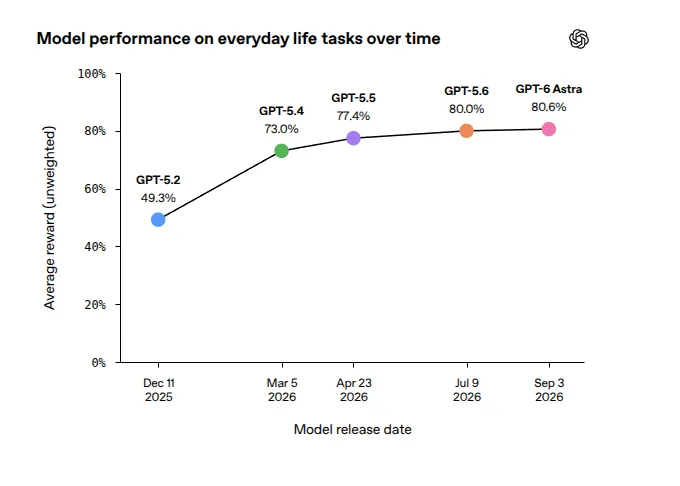
OpenAI Releases LifeVal Benchmark; GPT-6 Scores 80.6% on Daily Tasks
OpenAI has introduced LifeVal, a new benchmark designed to evaluate AI models' ability to handle everyday errands such as caregiving, finance, and shopping. Built from feedback by thousands of ChatGPT users, the benchmark reveals that GPT-6 Astra achieves an 80.6% success rate, a significant jump from GPT-5.2's 49.3% recorded nine months prior.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-11-02 18
OpenAI has released LifeVal, a benchmark testing whether AI models can finish everyday errands for people.
GPT-6 Astra, scores 80.6% on everyday tasks, up from 49.3% for GPT-5.2 less than 9 months earlier.
LifeVal’s tasks span caregiving, health, education, finance, shopping and household admin, from booking a car inspection to ordering halal groceries within budget.
↳ 引用 @OpenAI (OpenAI): For AGI to benefit all of humanity, it should help people with the everyday tasks that matter most to them. So we built LifeVal, a new benchmark shaped by feedback from thousands of ChatGPT users on where they most want help from a personal assistant—from finding childcare to accessing government services to managing personal finances.
Over the past year, we’ve used LifeVal to measure and improve how well our models handle these everyday tasks.