Prime Intellect Releases Mega MoE Training Kernel, Boosting Speed by 55%
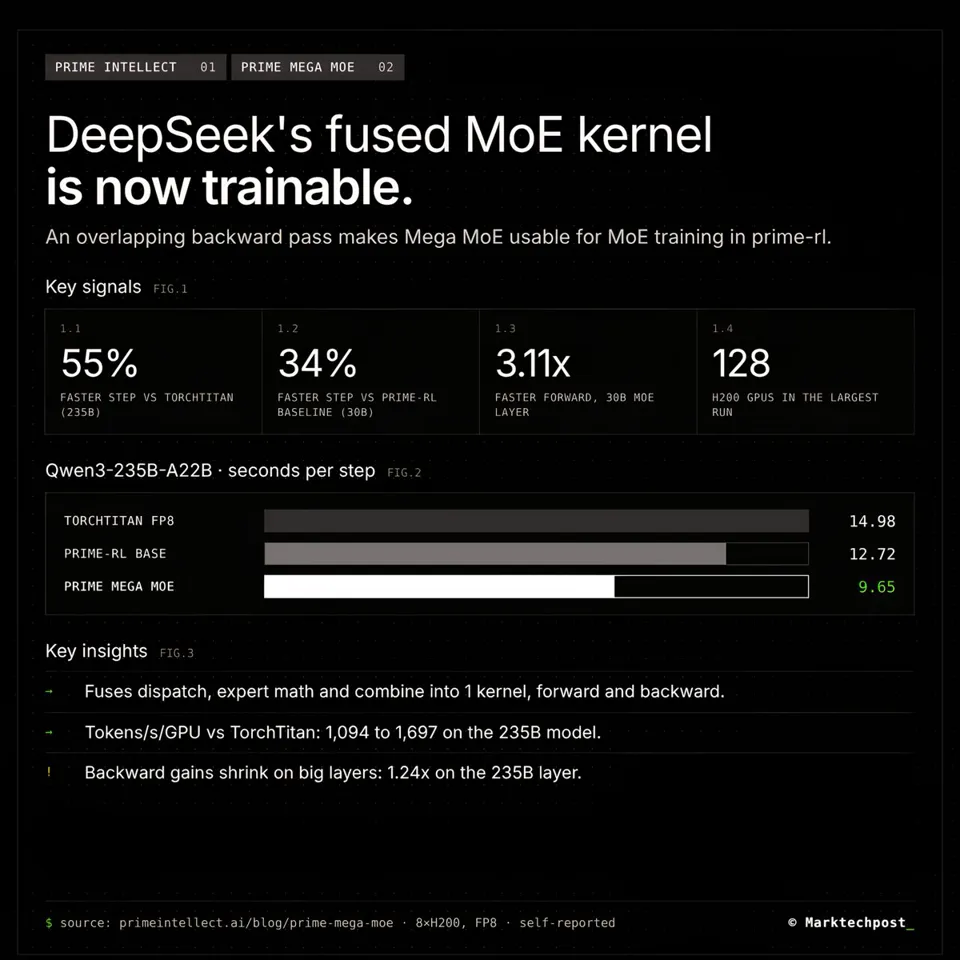
Prime Intellect released Prime Mega MoE, extending DeepSeek's fused kernel to support efficient backward pass training. On the Qwen3-235B model, this approach reduces single-step training time from 14.98s to 9.65s, achieving a ~55% speedup by optimizing communication and computation overlap in Mixture-of-Experts layers.
Full Report
▲ Marktechpost AI · 2026-10-29 18
▲ Prime Intellect just released Prime Mega MoE, which makes DeepSeek's fused Mega MoE kernel usable for training, not just inference.
The key idea is overlap. MoE layers normally route, send, compute and return as separate steps, so GPUs sit idle waiting on communication. DeepSeek's Mega MoE fuses those steps into 1 kernel, but it only had a forward pass. Prime Intellect added a fast, overlapping backward kernel.
On Qwen3-235B-A22B (128 H200), a training step drops from 14.98 s with TorchTitan to 9.65 s, 55% faster. Against its own prime-rl baseline, steps are 32% to 34% faster. It is a trade-off though: the forward pass gets up to 3.11x faster, but the backward pass on the 235B layer gains only 1.24x.
It ships today in prime-rl (Apache 2.0) as the mega_moe dispatch backend, with BF16, blockwise FP8 on Hopper and MXFP8 on Blackwell......
Full analysis: