Nvidia Paper Finds Irrelevant Text Weakens Models via Intrusion Heads
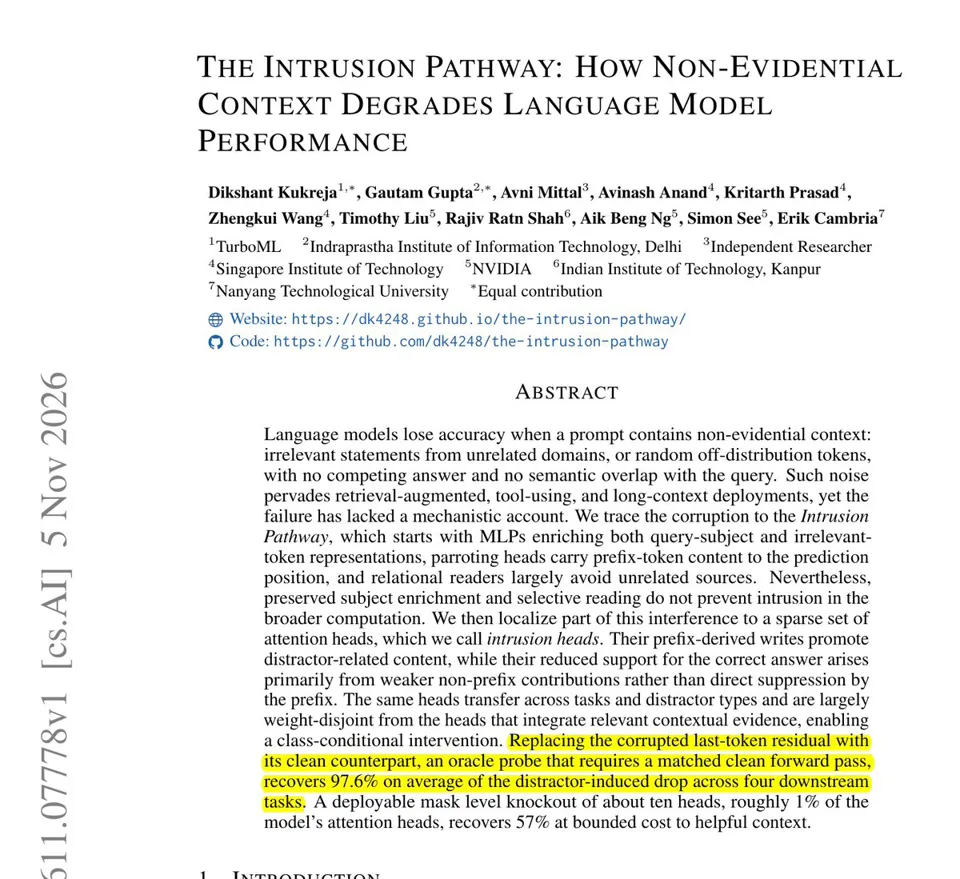
A new Nvidia-led paper finds that irrelevant text in RAG, tool-use and long-context prompts hurts models mainly by weakening their use of the question rather than directly suppressing the right answer. The authors identify a small set of 'intrusion heads' inside open models that read unrelated text and dilute the answer; masking about 10 such heads on 7B-scale models recovered 57% of the accuracy lost to distractors on average, versus a 97.6% oracle ceiling.
Related Entities
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-11-10 04
New Nvidia + other labs paper shows that irrelevant text hurts mainly by weakening the model's use of the question, not by directly pushing against the right answer.
Prompts in RAG, tool use, and long-context apps often carry text that has nothing to do with the question. Even a line like "Computers are useful" lowers a model's support for the right answer.
They traced this inside open models and found intrusion heads, a small set of attention heads that read the unrelated text and weaken the answer. Masking those heads' attention to the context leaves the heads that use helpful evidence untouched.
Across 4 tasks on 7B-scale models, masking about 10 heads recovered 57% of the accuracy lost to distractors on average. An oracle fix that needs a matching clean run recovered 97.6%.
If you serve open-weight models with noisy retrieved context, a training-free mask on a few model-specific heads can win back much of the lost accuracy.