Stanford Finds All 8 LLMs Favor Their Own Medical Answers as Judges
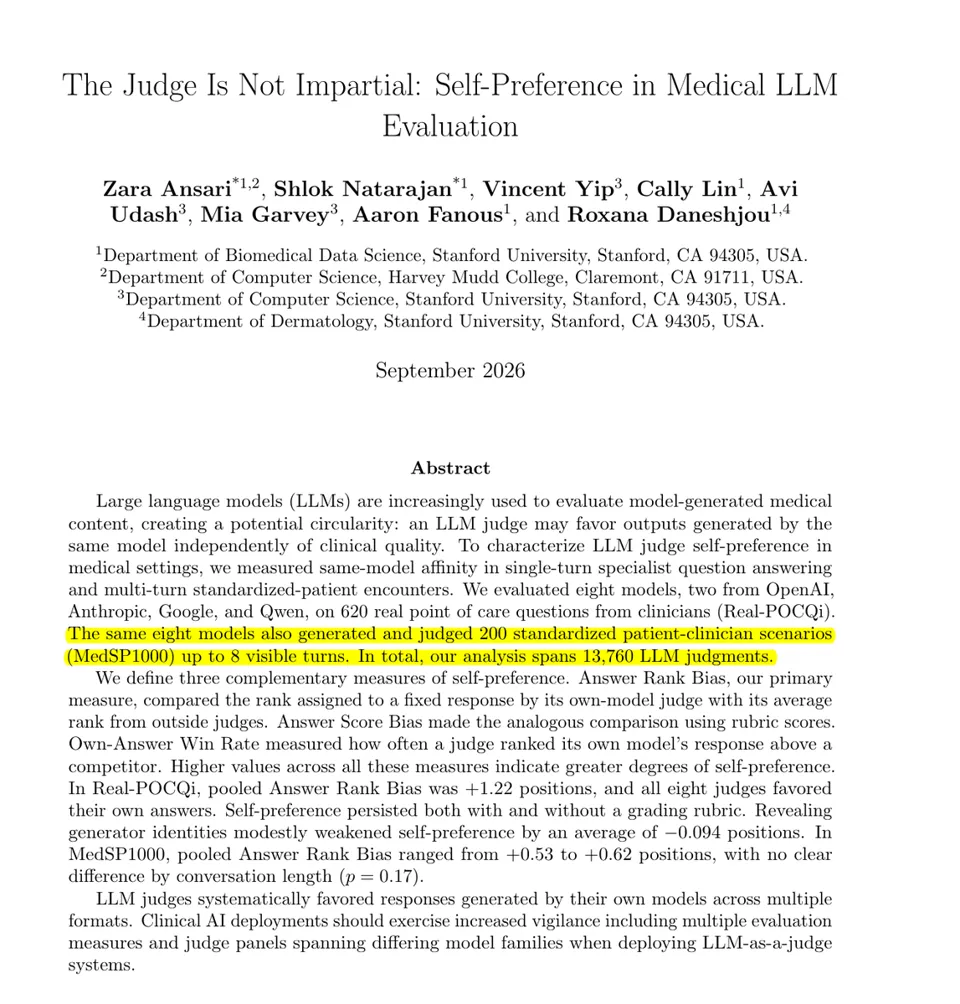
A new Stanford paper had eight models from OpenAI, Anthropic, Google and Qwen answer 620 real clinician questions, then rank all eight answers anonymously. Every judge favored its own answer, by 1.22 rank positions on average and nearly 3 for GPT-5.6 Sol. The bias persisted without a rubric, and revealing model names cut it by only 0.094 positions, implying LLM-as-judge medical benchmarks carry systematic self-preference. The authors recommend multi-family judge panels with per-judge reporting instead of one pooled score.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-11-18 04
New Stanford paper finds that all 8 LLMs tested rank their own medical answers higher than other models rank them, even when answers are anonymous.
Medical AI benchmarks often use LLMs to grade other LLMs' answers. If a judge favors its own outputs, the benchmark tilts toward that model.
They had 8 models from OpenAI, Anthropic, Google and Qwen answer 620 real clinician questions, then rank all 8 anonymous answers. They compared where each judge placed its own answer with where the other 7 judges placed that same answer.
Every judge favored its own answer, by 1.22 rank positions on average and nearly 3 for GPT-5.6 Sol. The bias held without a rubric, and revealing model names cut it by only 0.094 positions.
If you use LLM judges, use a panel from several model families and report results per judge instead of 1 pooled score.