Salesforce Study Finds External Teacher Distillation Costs More Compute Than RL
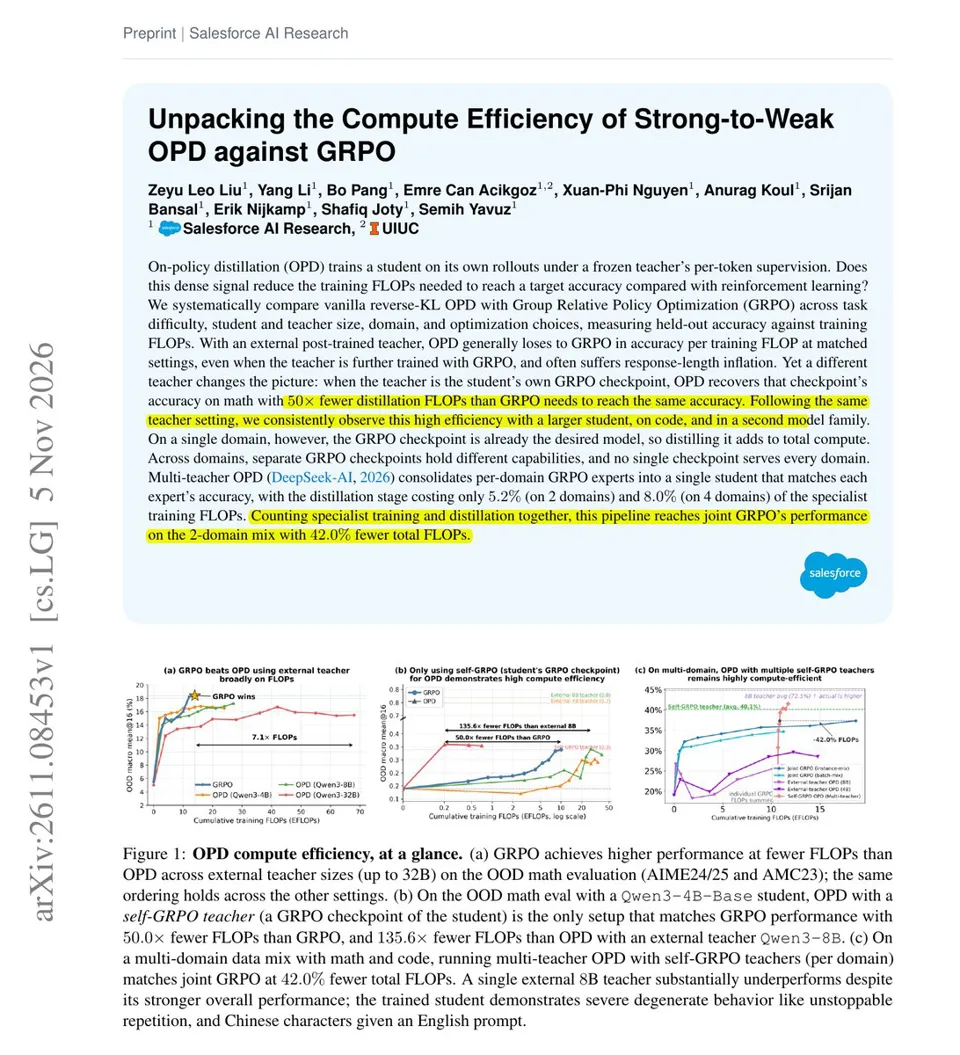
A new Salesforce paper compares on-policy distillation against GRPO using held-out accuracy per training FLOP. It finds that distilling from a large external post-trained teacher generally costs more compute than plain RL and tends to inflate response length, whereas training per-domain RL experts and distilling them into a single student matches joint GRPO on math and code with 42% fewer total FLOPs.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-11-08 00
New Salesforce paper finds that distilling from a big external teacher usually costs more compute than plain RL, while merging RL-trained domain experts saves 42%.
On-policy distillation lets a student learn from a teacher's per-token feedback on its own outputs, and many expect this dense signal to beat RL. But every training token also needs a teacher forward pass.
They compared distillation and GRPO by held-out accuracy per training FLOP, varying task difficulty, model sizes, domains, and training settings.
With an external post-trained teacher, GRPO generally won, and distillation often inflated response length. Distilling per-domain GRPO experts into 1 student matched joint GRPO on math plus code with 42.0% fewer total FLOPs.
To save compute, train per-domain experts with RL and distill them into 1 model, rather than distilling from a big external teacher.