Salesforce 研究:从外部大模型蒸馏不如强化学习划算
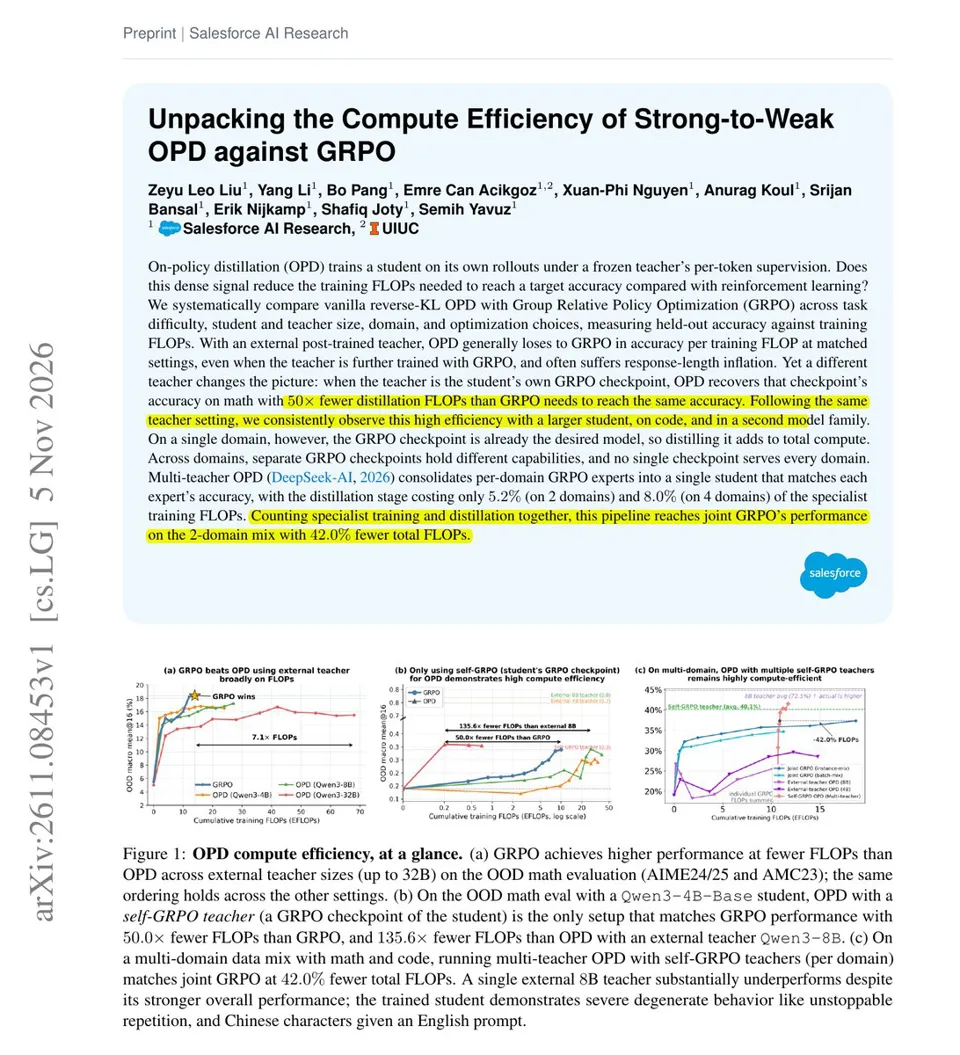
Salesforce 新论文以“每单位训练算力对应的留出准确率”为口径,对比在线策略蒸馏与 GRPO。结论是:从外部已后训练的大模型蒸馏通常比直接做 RL 更耗算力,且容易拉长回答长度;而先用 RL 训练各领域专家、再蒸馏合并为单一学生模型,可在数学与代码任务上以少 42% 的总 FLOPs 追平联合 GRPO。
报道正文
Rohan Paul (@rohanpaul_ai) · 2026-11-08 00
New Salesforce paper finds that distilling from a big external teacher usually costs more compute than plain RL, while merging RL-trained domain experts saves 42%.
On-policy distillation lets a student learn from a teacher's per-token feedback on its own outputs, and many expect this dense signal to beat RL. But every training token also needs a teacher forward pass.
They compared distillation and GRPO by held-out accuracy per training FLOP, varying task difficulty, model sizes, domains, and training settings.
With an external post-trained teacher, GRPO generally won, and distillation often inflated response length. Distilling per-domain GRPO experts into 1 student matched joint GRPO on math plus code with 42.0% fewer total FLOPs.
To save compute, train per-domain experts with RL and distill them into 1 model, rather than distilling from a big external teacher.