Microsoft Study Finds LLMs Abandon Correct Answers When Wrongly Challenged
A new Microsoft paper finds that LLMs frequently abandon correct answers when challenged with flawed arguments, and accuracy-focused training does not fix this failure mode. The proposed Self-Disagreement training has a model answer, write the strongest counter-case, then rule on it and answer again, raising correct-answer retention under wrong challenges from 53.3% to about 89% for Qwen3-8B and from 25.1% to about 89% for Gemma-2 9B.
Related Entities
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-11-18 16
New Microsoft paper finds that LLMs give up correct answers when challenged with wrong arguments, and accuracy training does not fix it.
When a user or another agent disputes an answer, models often abandon correct answers even when the challenge is wrong. More accuracy training, more sampling, or self-reflection does not fix it.
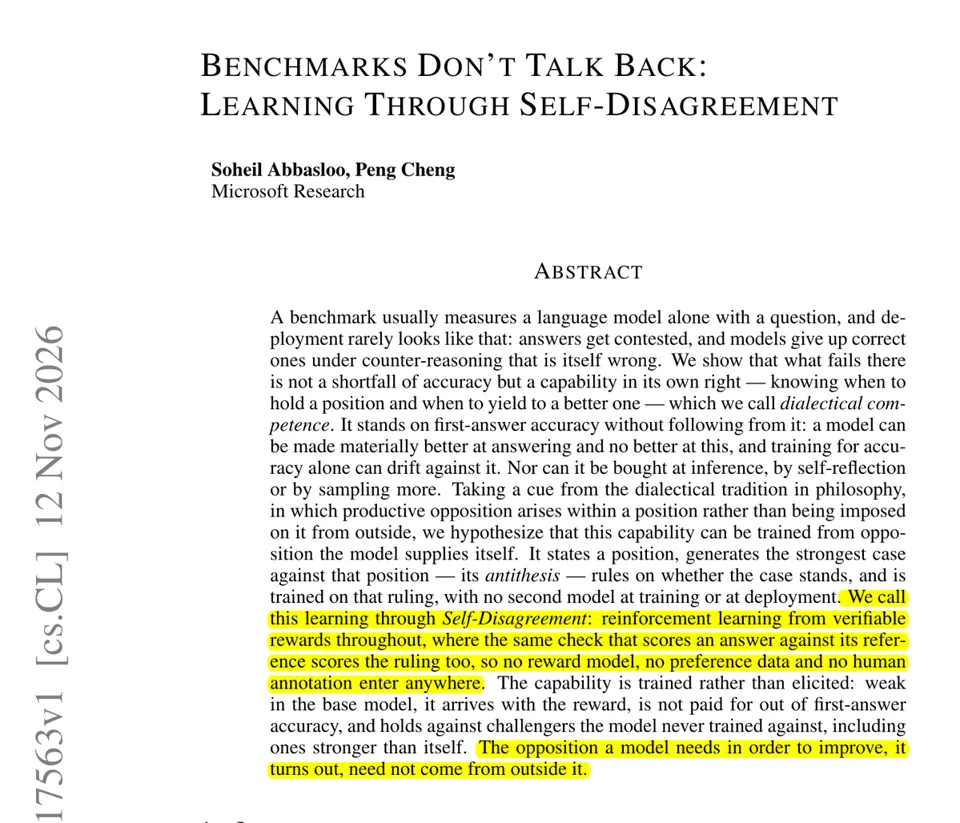
Self-Disagreement trains one model to state an answer, write the strongest case against it, then rule on that case and answer again. A standard answer checker rewards the final answer and the ruling.
When challengers were wrong, base Qwen3-8B kept its correct answer 53.3% of the time and Gemma-2 9B 25.1%. After training, both kept it about 89% of the time, while accuracy-only training added no such skill.
If your model faces pushback from users or other agents, test how often it drops correct answers, since accuracy scores will not show it.