Ant Group's Robbyant Open-Sources LingBot-Touch Tactile Foundation Model
Ant Group's Robbyant has open-sourced LingBot-Touch, a tactile pretrained foundation model that inserts a unified representation translation layer between raw sensor readings and action models. Experiments show zipper-pulling success rising from 39% with vision-only to 59%, and box handover recovering from 48% to 63%, fixing the degradation caused by sparse, noisy raw tactile signals.
Full Report
Contents3 sections
Jin Lei reporting from Aofeisi QuantumBit | WeChat Official Account QbitAI
What a contrast.
They clearly equipped a robot with touch, so why did it become clumsier...
△Image generated by AI
Here's what happened.
Recently, a team ran an experiment. They installed tactile sensors on all five fingers of the Sharpa Wave dexterous hand, and the task was to make it zip up a bag.
The action model they chose was π0.5. Using only cameras, the success rate reached 39%.
Then the team fed it the fingertip sensor readings unchanged. Logically, with an extra sense, the robot should be better at zipping up the bag.
But guess what.
AUV (oh wow)... the success rate directly dropped to 15%!
And this wasn't an isolated case.
With the same Sharpa Wave dexterous hand and π0.5 combination, after connecting raw touch to do the box handover task, the success rate dropped from 57% to 48%.
Even when swapping the dexterous hand for XHand, averaged across 6 tasks, the success rate fell from 49.71% to 48%.
So what exactly is the reason that the robot, with an extra sense, instead becomes clumsy?
The answer is: the problem lies in the readings themselves.
Because tactile data is different from other data. The robot's fingers are not in contact with objects most of the time, so the readings are basically a large expanse of "0"; even when contact begins, the signal is sparse and noisy.
On top of that, different sensors each serve their own purpose. Vision-based touch captures the deformation of the fingertip's soft gel, magnetic touch measures the magnetic field, piezoresistive touch records resistance... The data is all different.
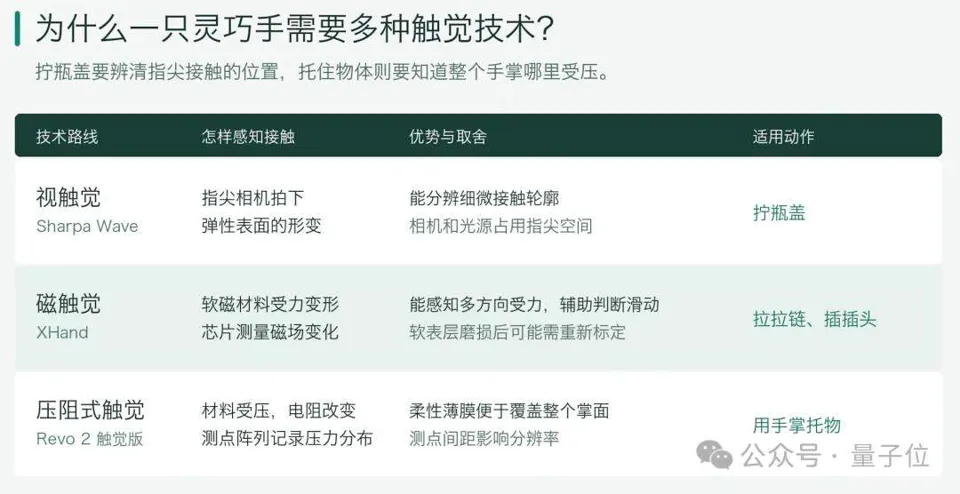
△How three types of tactile sensors perceive contact, and their respective trade-offs
For example, for the task of gripping a bottle cap, the three sensors give three completely different sets of numbers. The action model can't understand them, yet has to use them anyway... You could say they're doing more harm than good.
So how do we break this deadlock?
Ant Lingbo offers a solution — adding a "translator" between the sensors and the action model.
(Note: the experiments above were done by Ant Lingbo.)
Simply put, the idea is to first translate the data read by various sensors into something the action model can understand — such as where the finger touches, how much force is applied, which direction the force deviates, and whether there's slipping — and then hand it over.
Still the same π0.5, still the same zipping task, and with this approach, the success rate directly soared to 59%, even 20 percentage points higher than using no touch at all; the success rate for the box handover task also went from 48% back to 63%.
And this "translator" is Ant Lingbo's newly open-sourced tactile pre-trained foundation model LingBot-Touch, released today.
With its support, the bottle-cap-twisting motion we just mentioned becomes very smooth:

Video address: https://mp.weixin.qq.com/s/b7PNN5A3W8e1bZDVNTd5tg
You should know that the place where twisting a bottle cap easily goes wrong is exactly the small patch where the fingertip pad meets the cap: grip it a little loosely, and the fingertip pad slips on the cap surface — the wrist turns half a revolution, but the cap doesn't budge. And this is exactly what cameras can't see clearly.
So how exactly does LingBot-Touch, this "translator," pull it off?
Dexterous hands need a translator
Let's first clarify what LingBot-Touch actually does.
Simply put, it receives signals from three types of sensors — magnetic touch, vision-based touch, and piezoresistive touch — and then uniformly encodes them into a kind of tactile Token, from which it reads out contact position, force magnitude, and how the force direction changes over time.
Its position sits right in the middle: downward, it can connect to different sensors and dexterous hands; upward, it hands these Tokens to different action models.
In this way, no matter how varied the signals from different sensors are, by the time they reach the action model, they can all be understood uniformly — different paths leading to the same destination.
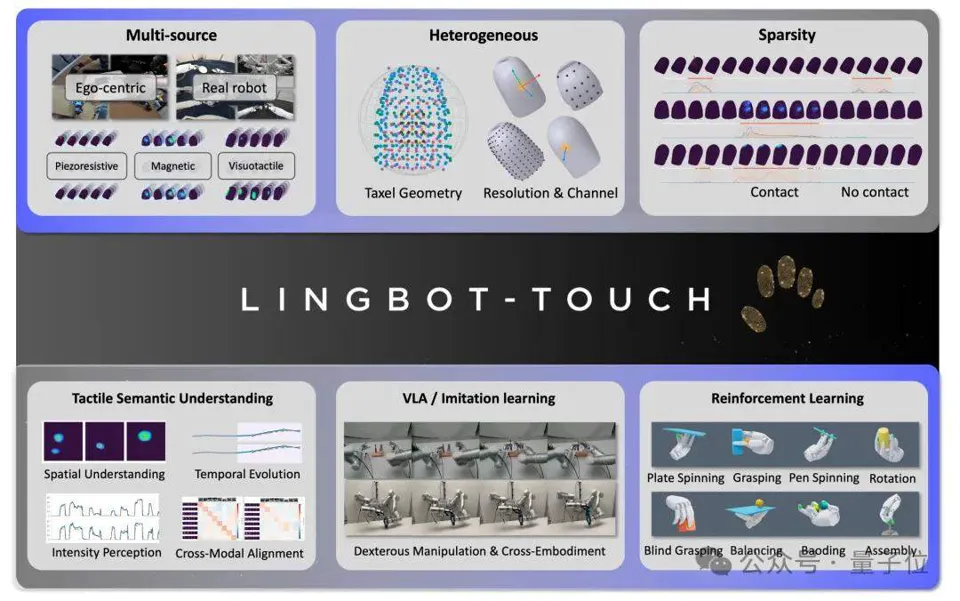
△LingBot-Touch connects multiple tactile sensors with real dexterous manipulation
Moreover, the lightweight version of LingBot-Touch, LingBot-Touch-Tiny, has only about 5.32 million parameters, and the technical report, code, and model weights have all been open-sourced.
So how was LingBot-Touch trained?
Overall, the Ant Lingbo team took mainly three steps.
The first step is unifying coordinates.
The first challenge the team encountered was that the number and arrangement of contact points differ greatly across sensors. For example, some dexterous hands have 116 contact points on the thumb alone, while some fabric gloves have only a single 3×3 small array.
If you try to match them by index, they definitely won't line up.
To address this, the team first mapped the contact points of all sensors into the same standardized fingertip space, and then gave each Token an "address" composed of time, finger, and 3D position.
The address enters the model through rotary position encoding (RoPE). This way, the model no longer requires a fixed number of contact points; even if the layout changes, it can still read them.
On this basis, each of the three sensor types has its own lightweight entry point, responsible for converting raw readings into Tokens; behind the entry points, they share the same tactile Transformer backbone.
In other words, the differences between sensors are absorbed by their respective entry points, while the patterns of contact itself are learned together in the shared backbone.
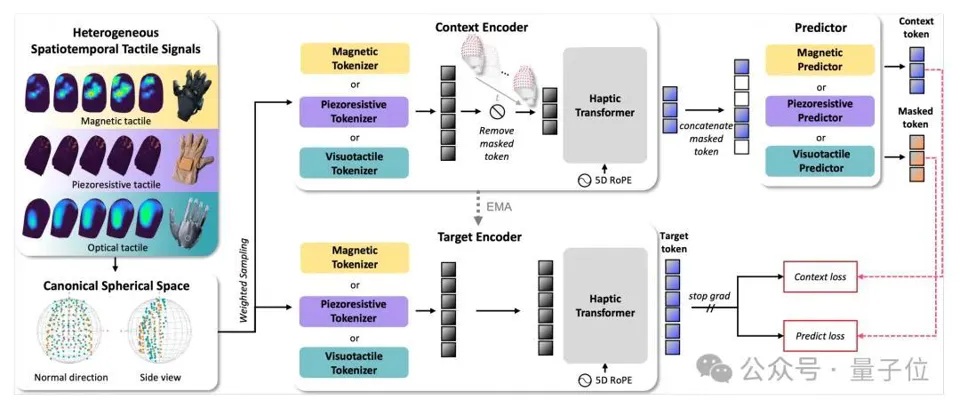
△Overall architecture of LingBot-Touch: three sensor types with separate entry points sharing one backbone
The second step is making predictions in feature space.
After unifying coordinates, the team ran into a second pitfall — the large expanse of "0" we mentioned at the beginning.
If the model were asked to reconstruct the raw readings, it would quickly find a shortcut: as long as it learns the "no-contact" background well, the loss can be driven very low. But in that case, although the scores look good, very little genuinely useful contact information is learned.
So LingBot-Touch chose the JEPA approach.
Specifically, during training the model randomly masks 90% of the contact points, and keeps them masked for the entire duration; then, based on the changes in the remaining 10%, the model predicts the representations of the masked parts in feature space, without needing to reconstruct the readings point by point.
With this approach, the results were immediate: trained on the same 1000 hours of data, LingBot-Touch's error in judging the contact center was 0.90 mm, while VAE and MAE were both above 3 mm.
As another example, when using a segment of touch to find the corresponding video frame, LingBot-Touch's top-5 recall was 32.07%, while the other two methods were both below 6%.

△Comparison of feature-space prediction versus raw-reading reconstruction on the same data
The third step is to expand the data to prevent the model from rote memorization.
LingBot-Touch's pretraining data totals 4983 hours, about 1.33 billion frames. Two-thirds of it comes from people wearing tactile gloves while working, and the remaining one-third comes from teleoperating the Sharpa Wave dual-arm robot.
The reason for using gloves so heavily is that they do not require a robot: one person can record several hours a day in an ordinary environment. Moreover, these data are annotated only with task categories such as open, close, assemble, and pour water; not a single frame is labeled with force magnitude.
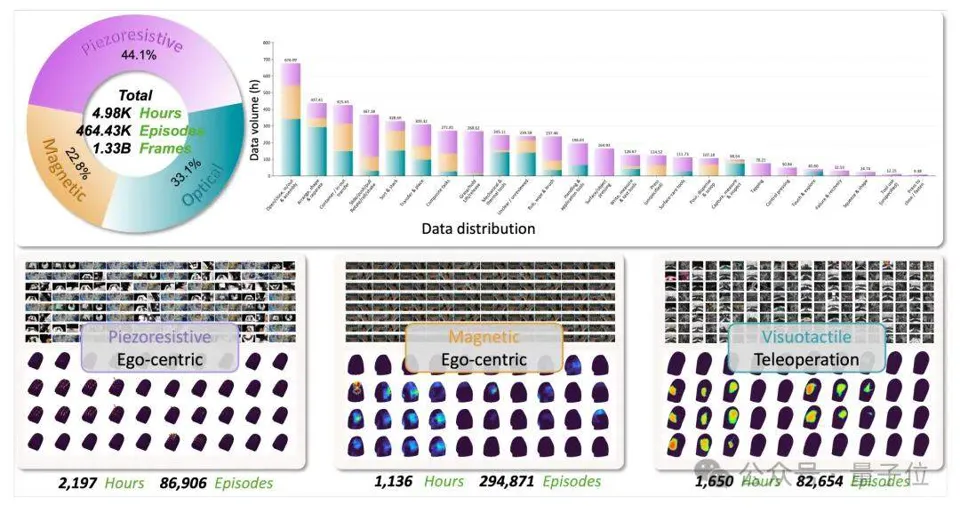
△Composition of the pretraining data, covering three types of sensing principles
However, once enough data had been accumulated, the team still had to prevent the model from "slacking off."
Because there are only three sensor layouts in pretraining, the model could very likely memorize the positions of these three sets of contact points outright, and then be at a loss when encountering a fourth layout.
So during training, the team randomly varies the sampling density of contact points and slightly shifts the position of each contact point, forcing the model to learn the underlying patterns of contact itself.
After these three steps, it was time for real-robot validation.
The tests covered two dexterous hands: the high-DOF Sharpa Wave performed 20 tasks, and the low-DOF XHand performed 6, for a total of 26 tasks.
Four action models participated in the tests: Diffusion Policy, π0.5, LingBot-VLA, and T-Rex. Each model was tested separately under three settings: no touch, feeding raw signals directly, and incorporating LingBot-Touch.
As a result, on both hands, the group incorporating LingBot-Touch had the highest average success rate for all four models.
Compared with no touch, the success rates of T-Rex, π0.5, and LingBot-VLA increased by 23.18, 21.81, and 24.81 percentage points, respectively, at the cost of only 0.13% to 0.16% more parameters.
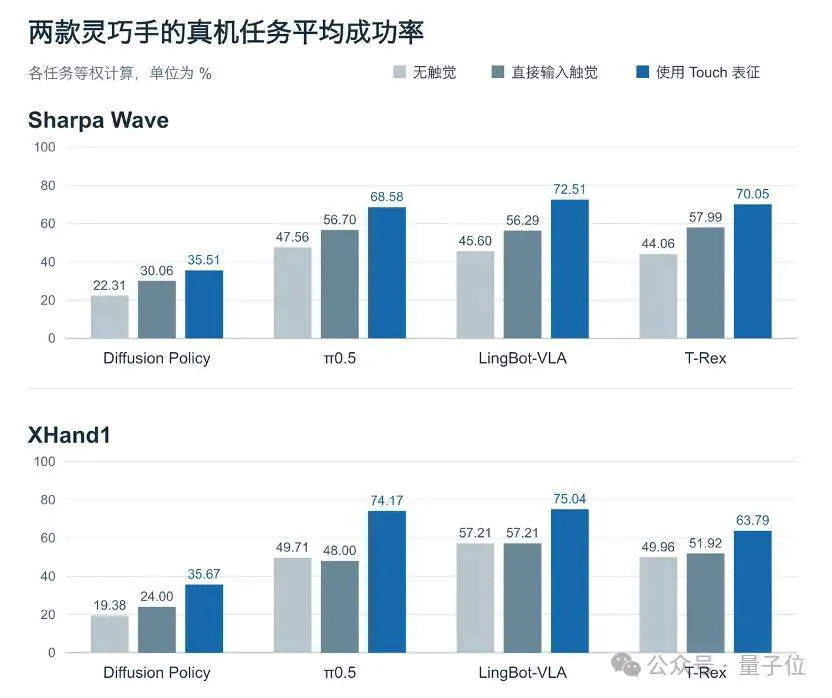
△Average success rates of four action models under three settings on two dexterous hands
Take inserting a straw with one hand as an example. The difficulty of this task lies in the moment of piercing the sealing film. As the straw presses down against the transparent sealing film, the resistance grows greater and greater, and the moment the film breaks, the hand suddenly loses resistance.
It is hard for a camera to distinguish whether the film has been dented or already pierced, but the fingertips can. If the force is released even one step too late, the straw will shoot straight to the bottom of the cup.

Video address: https://mp.weixin.qq.com/s/b7PNN5A3W8e1bZDVNTd5tg
Of course, the most telling results are the XHand experiments.
The magnetic tactile sensor used by XHand has a model that never appeared in the pretraining data; moreover, all the magnetic tactile data in pretraining came from gloves worn by people. When incorporating XHand, LingBot-Touch did not change a single parameter.
Even so, π0.5's average success rate on the 6 tasks rose from 48.00% when raw signals were fed directly to 74.17%.
In the task of separating stacked cups, the success rate more than doubled, from 32.5% to 72.5%.
This task requires the dexterous hand to take only the topmost cup. It has to use one hand to steady the whole stack and the other to pinch the rim and pull outward. If the resistance suddenly decreases while the fingertip is still firmly against the rim, it means the cup has come loose and the force must be released immediately; if the fingertip itself is slipping on the rim, it should regrip.
These two situations feel completely different.

Video address: https://mp.weixin.qq.com/s/b7PNN5A3W8e1bZDVNTd5tg
In other words, experience accumulated from human hands helped the robot understand a hand it had never touched.
In addition, the team compared LingBot-Touch with the earlier tactile foundation model FTP-1.
When judging the contact center on Sharpa Wave, FTP-1's error was 2.19 mm, while LingBot-Touch's was 0.12 mm; on XHand, the error also dropped from 5.89 mm to 0.16 mm.
It should be noted that FTP-1 even had a dedicated adapter for each of these two hands, whereas LingBot-Touch used the same frozen encoder.
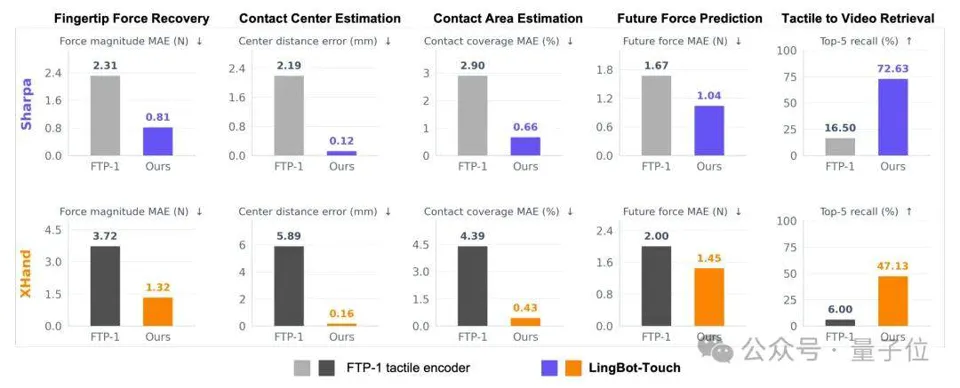
△Comparison with FTP-1 on two dexterous hands
In addition, LingBot-Touch's Scaling Law has already begun to emerge.
The Tiny version starts to saturate at around 4000 hours; switching to the larger-capacity Small version, performance is still rising at 5000 hours; the success rate on real-robot tasks also improves steadily as the pretraining data increases.

△The impact of pretraining data volume and model scale on performance
Completing the puzzle of touch
Having reviewed the technical details, let us now place LingBot-Touch back into Ant Lingbo's overall technology roadmap to see more clearly where it fits.
Before this, Lingbo's general-purpose brain had already laid out three capabilities: spatial perception with LingBot-Vision and LingBot-Depth 2.0, environmental interaction with LingBot-Video and LingBot-World 2.0, and dexterous manipulation with LingBot-VLA 2.0 and LingBot-VA 2.0.

As can be seen, most of these capabilities address what happens before contact—for example, where an object is, where the hand should reach, and what to do next.
However, once the fingers touch an object, the information vision can provide diminishes. For instance, the area where the fingertip presses against a bottle cap is occluded by the hand, and once a key is inserted into a keyhole, nothing can be seen at all.
What LingBot-Touch fills in is precisely this gap. In one sentence: vision handles what comes before contact, touch handles what comes after.
Opening a lock with both hands is a typical example.
One hand holds the padlock while the other pinches the key and aligns it with the keyhole—this step relies mainly on the eyes. But once the key is pushed in, it may tilt the lock, or get stuck halfway, requiring a slight retreat and another attempt at a different angle.
Once the key is in the keyhole, the camera is essentially of no help, and the dexterous hand can only rely on the resistance transmitted back to the fingertips through the key to make judgments.

Video address: https://mp.weixin.qq.com/s/b7PNN5A3W8e1bZDVNTd5tg
At this point, some readers may ask: why does Lingbo make touch a separate foundation model?
The reason is that every hand has a different control method, but all of them must understand contact.
If "understanding contact" is extracted as a separate, reusable layer, then the experience accumulated on one piece of hardware can become the starting point for the next robot.
This approach is actually in line with Lingbo's earlier work on LingBot-VLA.
VLA studies how the same brain can drive robots of different configurations—that is, "one brain, multiple machines." With Touch, the question is pushed one step further: can the contact experience accumulated across different hands and different sensors be learned together and then applied to new robots?
The XHand results mentioned earlier provide a preliminary answer.
Several design choices of LingBot-Touch were also derived backward from this goal. Data is collected with gloves because gloves do not depend on the robot body, which allows the data scale to grow. The input interface is designed according to sensing principles rather than product models, in order to leave room for future new sensors.
This is also what Lingbo has consistently emphasized as embodied-native, that is, starting from how robots perceive and act in the physical world to determine how models should be designed and what data they should be trained on.
Currently, LingBot-Touch has been integrated with LingBot-VLA and LingBot-Depth to enhance the general-purpose brain's hand-eye coordination and ability to complete fine manipulation.
In terms of deployment, Lingbo is also conducting commercial testing in retail sorting, logistics sorting, and industrial scenarios with hardware partners such as Leju and Taihu, as well as scenario partners such as Guoda Pharmacy and Longsheng.
The stronger large models become, the more indispensable embodied-native approaches are
Having discussed LingBot-Touch itself, let us zoom out a bit.
After GPT-6 Astra was released in September this year, the RoboDojo team had it run 42 simulated manipulation tasks under zero-shot conditions. Its overall score ranked first among 43 evaluated entries.
To be honest, this made the embodied AI community quite nervous for a while.
But in the same report, there was another set of numbers. GPT-6 Astra's success rate on the precision dimension was only 4%, while the best-performing public policy reached 20.42%. On tasks requiring precise contact, such as tube insertion and tower building, it almost completely failed, and real-robot testing was halted due to safety concerns.
The report attributed this gap to a lack of physical common sense—that is, an understanding of contact, force, and collision.
And just today, Anthropic released Claude Fable 5.2, pushing the progress bar of large models controlling robots one step further.
According to internal test results published on Anthropic's official blog, Fable 5.2 achieved an average success rate of 64.9% in the RoboDojo simulation tests—more than double that of GPT-6 Astra (29.8%) under the same testing framework, and also higher than most AI systems built specifically for robot control.
In the official demo, a robot controlled by Fable 5.2 can also solve a Rubik's cube, twist off a bottle cap, and draw. However, what RoboDojo tests is controlling a simulated dual-arm robot by watching camera footage.
From Fable 5.1 to Fable 5.2, in just over two months, the success rate in the same test suite rose from 27.6% to 64.9%. The ability of general large models to understand tasks, reason and plan, and even directly perform operations is visibly growing stronger.
But in our view, this does not mean embodied models should step aside and only handle "acting."
There is still a gap between high scores in simulation and reliably completing work in the real world—namely, generalization in the physical world. If the hand is changed, the material is changed, or the scenario has never been seen before, can the robot still perform well? This question cannot be avoided, and it must be tackled by a brain that grows natively from the physical world.
This is also the judgment of Ant Lingbo CEO Zhu Xing.
He believes that the progress of large language models in the digital world, such as GPT-6 Astra and Claude Fable 5.2, has indeed made robots stronger in complex task reasoning and physical manipulation, and Lingbo is actively absorbing these advances. However, to truly close the manipulation loop, "the hard nut of physical manipulation generalization still cannot be avoided," and to a large extent it still depends on breakthroughs in embodied foundation models themselves.
In his view, general large models and embodied foundation models are closer to a 1+1>2 relationship: each makes breakthroughs on its own and promotes the other, jointly accelerating the maturation of the embodied intelligence industry.
LingBot-Touch is Lingbo's attempt to crack this hard nut.
Touch is a modality native to the physical world. The internet holds vast amounts of text, images, and video, yet almost no webpage has ever recorded exactly how many newtons of force a thumb applies when pinching a bottle cap. This kind of experience can only be accumulated bit by bit through real interaction, and it is precisely one of the foundations of generalization in the physical world.
For example, a dexterous hand feeling mahjong tiles relies on exactly this kind of experience.
The two of circles and the three of circles both feel like circles to the touch. To tell them apart, you have to feel out how many circles there are in total and where each one is arranged—and these clues are all hidden in the shallow engravings beneath the fingertip.

Video address: https://mp.weixin.qq.com/s/b7PNN5A3W8e1bZDVNTd5tg
In the past, touch has always been fragmented—each sensor has its own dataset and its own model, and switching to a different hand means starting over from scratch. LingBot-Touch proves that touch can also have a unified representation.
If we take this one step further, in the LingBot-Touch approach—unified coordinates, separate entry points, a shared backbone, and prediction in feature space—no single component belongs exclusively to touch.
This line of thinking also runs through Ant Lingbo's entire embodied-native roadmap. According to the plan, Lingbo will continue to explore the upper limits of generalization in physical manipulation, build a general-purpose brain for the robotics industry that works across configurations, and drive the alignment of more physical modalities—vision, depth, touch, and even temperature—within a unified model. As for what additional sensing modalities robots will gain in the future, no one can say for sure right now, but at least there is already a path to refer to.
This is exactly what Ant Lingbo wants to do: build a layer of intelligence between hardware and scenarios, and transform the physical experience accumulated across different embodiments and different sensors into general capabilities that can be shared.
Moreover, Ant Lingbo is releasing this layer of capability in an open-source, decomposable way, and will continue to open-source it to the community while advancing commercialization.
LingBot-Touch can be used on its own, and it works just as well when plugged into other companies' action models such as π0.5 and Diffusion Policy; sensor manufacturers can continue along their own technical roadmaps, and robot OEMs do not need to swap sensors for the sake of a particular model.
Audi disclosed a figure earlier this year: across the industry, the automation rate of wiring harness production and assembly is still below 10%. This kind of work—making contact and adjusting on the fly—is exactly where dexterous hands have long failed to keep up.
Looking at China, there are many types of dexterous hands and tactile sensors. In the past, this was a headache because data could not be shared across them; but once experience can be shared, this diversity will instead become a data advantage.
In short, just because a robot hand has signals does not mean it knows how to use them.
As Zhu Xing put it, "the quality of modality input largely determines the quality of action output"—without good input, there is no good output.
The faster general-purpose large models run, the more the embodied-native brain must not fall behind. The ability to make robots do work steadily and well in the physical world ultimately has to be trained bit by bit in the real world by an embodied-native brain.
Project homepage:
https://technology.robbyant.com/lingbot-touch
Technical report:
https://github.com/Robbyant/lingbot-touch/tree/main/paper
GitHub: https://github.com/Robbyant/lingbot-touch
Hugging Face: https://huggingface.co/collections/robbyant/lingbot-touch
ModelScope Community:
https://www.modelscope.cn/collections/Robbyant/LingBot-Touch