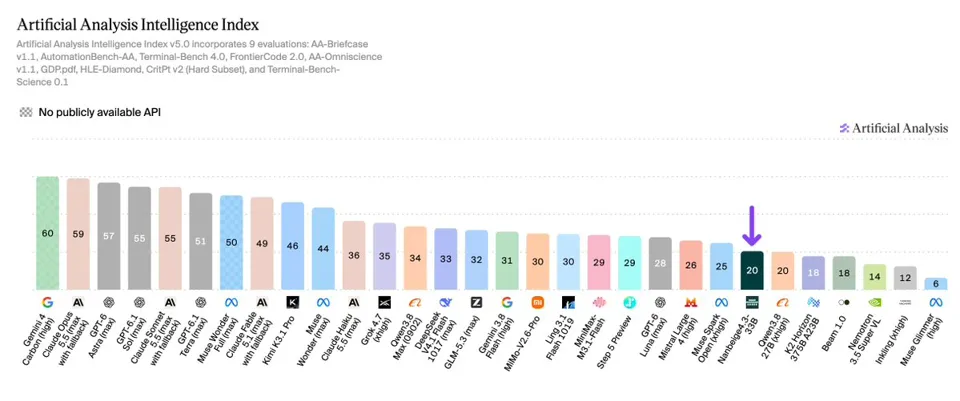
BOSS Zhipin's Nanbeige Team Releases Open-Weights Nanbeige4.3-33B, Matching Qwen3.8 27B on Intelligence Index
Nanbeige, the foundation model team at Chinese recruitment platform BOSS Zhipin, has released Nanbeige4.3-33B under Apache 2.0 — a dense 33B reasoning model scoring 20 on the Artificial Analysis Intelligence Index v5, level with Qwen3.8 27B (xhigh). It offers a 524K-token context window, text-only I/O, and is small enough to run locally on a laptop, with terminal use and physics reasoning as relative strengths but weaker knowledge benchmarks.
Full Report
Artificial Analysis (@ArtificialAnlys) · 2026-11-05 17
Nanbeige has released Nanbeige4.3-33B, an open weights model matching Qwen3.8 27B (xhigh) at 20 on the Artificial Analysis Intelligence Index v5 with stronger terminal use but weaker knowledge
@Nanbeige is the foundation model research team at BOSS Zhipin, the Chinese recruitment platform operated by Kanzhun Limited. Its dense 33B reasoning model is open weights under Apache 2.0, with text input and output only, a 524K-token context window, and is small enough to run locally on a laptop.
Key results:
➤ Competitive results at ~30B total parameters. Nanbeige4.3-33B and Qwen3.8 27B (xhigh) both score 20, compared with 6 for Muse Glimmer (high, 30B).
➤ Terminal use and physics reasoning are relative strengths. Nanbeige scores 30% on Terminal-Bench 4.0 and 16% on CritPt v2's Hard Subset, vs. 6% and 4% respectively for Qwen3.8 27B.
➤ Different strengths to Qwen3.8 27B despite the same overall score. Nanbeige beats Qwen3.8 27B on AutomationBench-AA (53% vs. 48%), but trails on AA-Briefcase v1.1 (1162 vs. 1391 Elo), FrontierCode 2.0 (11% vs. 15%) and HLE-Diamond (7% vs. 15%).
➤ High abstention and low hallucination rates on Omniscience. Nanbeige scores -4 on AA-Omniscience v1.1 vs. -6 for Qwen3.8 27B, with a hallucination rate of 18% vs. 29%. It answers fewer questions correctly (12% vs. 17%) and declines 71% of questions.
➤ Similar intelligence with more output tokens per task. Nanbeige used 158K output tokens per Intelligence Index task vs. 110K for Qwen3.8 27B, about 44% more.
Additional model details:
➤ Type: Open weights reasoning (Apache 2.0 license)
➤ Size: 33B total parameters (dense)
➤ Modalities: Text input and output only
➤ Context window: 524K
➤ API availability: No confirmed public first- or third-party APIs