E-means Delivers Up to 45x Faster k-means at Lower Loss
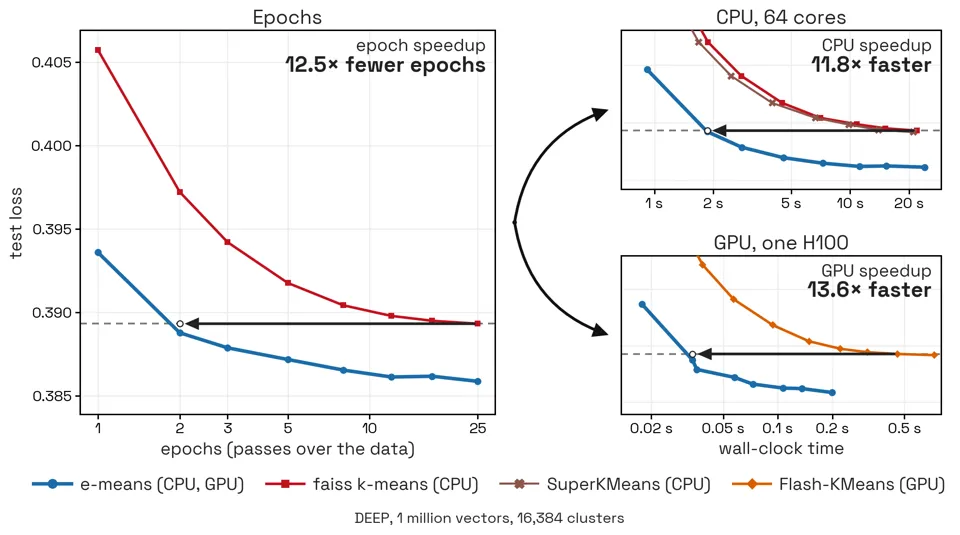
Researchers from Meta and École Polytechnique propose e-means, which reaches Lloyd's 25-epoch test loss in just 1.2 to 3 epochs. End-to-end measurements show 10-45x wall-clock speedups on GPU versus Flash-KMeans and 8-15x on CPU versus Faiss, while also achieving lower loss, breaking the usual speed-quality tradeoff in k-means.
Related Entities
Full Report
Contents10 sections
An order of magnitude less epochs
Across a large range of scales and datasets, e-means reaches a test loss below Lloyd's at 25 epochs, in 1.2 to 3 epochs. Measured end to end, that is a 10–45× wall-clock reduction on GPU against the state-of-the-art Lloyd implementation (Flash-KMeans[2]), and 8–15× on CPU against Faiss[1]. Speed and quality usually trade against each other in k-means, while e-means achieves both better speed and loss.
The k-means problem
Given a fixed dataset of n points X = {x1, ..., xn} ⊂ Rd and an integer k, the k-means problem is to find k centroids C = (c1, ..., ck) minimizing the mean squared distance between each point and its nearest centroid:
[ \mathrm{MSE}(X, C) = \frac{1}{n} \sum_{i=1}^{n} |x_i - c_{a(i)}|^2, \qquad a(i) = \arg\min_{j \in {1,\dots,k}} |x_i - c_j|^2 ] [ \mathrm{MSE}(X, C) = \frac{1}{n} \sum_{i=1}^{n} |x_i - c_{a(i)}|^2 ] [ a(i) = \arg\min_{j \in {1,\dots,k}} |x_i - c_j|^2 ]
It's a static dataset, unlike codebook learning inside VQ-VAEs, where the distribution to cluster is constantly moving.
The e-means project
The goal of e-means is to provide a modern optimization rule for the k-means problem. We started this project from the following observations:
- k-means is one of the rare problems in machine learning where full-batch optimization is still widely used.
- Mini-batch k-means methods in the literature exist[3],[4],[5], but are mostly based on the MacQueen update rule, released in 1967.
- Modern deep learning offers optimization tools that can enhance mini-batch methods.
For e-means, we chose to do mini-batch updates with exponential moving averages[6], which we found to be most efficient for the k-means problem. Contrary to previous mini-batch approaches, e-means requires no hyperparameter tuning because it automatically sets the batch size and step size with scaling laws (see Automatic hyperparameter tuning with scaling laws). In addition, e-means improves the initialization and the dead-cluster revival strategy, adds a cosine-scheduled decay rate, and introduces a finalization stage that reduces the training loss for a negligible runtime penalty at the end of training. e-means is highly parallelizable, and comes with specialized kernels that translate its algorithmic advantage into wall-clock speedups.
Moving-average updates
Each mini-batch updates every cluster's count and sum. The centroid is their ratio.
No hyperparameter tuning
Everything is derived from scaling laws.
Start and finish
Novel initialization and finalization methods. The run ends on each cluster's exact last-epoch mean.
Cosine scheduling
The step α anneals from α0 to 0.1α0, as a learning rate does.
Dead-cluster revival
Clusters with size below a threshold are revived by splitting a large cluster.
Specialized kernels
GPU kernels fuse the nearest-centroid assignment, turning the epoch savings above into matching wall-clock speedups.
The centroid update rules
The centroid update rule is the central component of e-means. This section aims to provide an overview of update rules for k-means clustering. All methods maintain, for each cluster j, a sum Sj and a count Nj of the points assigned to it, and take the centroid as their ratio:
[ c_j = S_j / N_j ]
They differ only in how Sj and Nj are updated. Below, sj and nj denote the sum and the count of the points in the current batch that are assigned to cluster j (both zero if none are).
Lloyd’s algorithm[7] assigns every point to its nearest centroid and recomputes the statistics from scratch, using the full dataset as the batch:
[ S_j \leftarrow s_j, \qquad\quad N_j \leftarrow n_j ]
so cj is the exact mean of the points currently assigned to it. Each update costs one full pass over the data, and the procedure is repeated a fixed number of times (typically 20 to 50 iterations).
MacQueen’s update[3] accumulates the statistics without ever discarding them:
[ S_j \leftarrow S_j + s_j, \qquad\quad N_j \leftarrow N_j + n_j ]
so cj is the uniform mean of every point assigned to cluster j since the start of training, including points assigned under earlier, possibly poor, centroid positions. This was later partially addressed by Staleness-Reduction Mini-Batch K-Means[8], a hybrid method between k-means and MacQueen. They obtained important speedups, but only on very low numbers of clusters.
e-means works on mini-batches and replaces this sum with an exponential moving average:
[ S_j \leftarrow (1-\alpha),S_j + \alpha, s_j, \qquad\quad N_j \leftarrow (1-\alpha),N_j + \alpha, n_j ] [ S_j \leftarrow (1-\alpha),S_j + \alpha, s_j ] [ N_j \leftarrow (1-\alpha),N_j + \alpha, n_j ]
so older assignments are forgotten at rate α, and the centroid tracks recent assignments rather than the whole history. This update rule is typically used for moving distributions, hence their adoption for training VQ-VAEs[6]. What we found is that it’s also extremely efficient for static datasets if it’s combined with e-means’ other components, and hyperparameters are properly tuned.
e-means better escapes local minima
To better understand why e-means reaches better losses than Lloyd at convergence, we plotted a few trainings on toy datasets to evaluate their ability to escape local minima. Repeating trainings over 200 seeds, we found that e-means is much less likely to fall in pathological configurations compared to Lloyd.
Lloyd (full batch) e-means (mini-batches of 256) training MSE Two blobs of very different sizes, k = 8. Lloyd puts two centroids on the small blob and leaves the large one short. e-means starts in the same trap and leaves it within its first epochs, ending with seven centroids on the large blob and one on the small. Over 200 starts Lloyd stays stuck on 26% of starts, while e-means stays stuck on 3.5% of times. Lloyd (full batch) e-means (mini-batches of 256) training MSE Nine blobs in a 3×3 grid with heavier corners, k = 10. Lloyd leaves the centre blob without a centroid and crowds three into a corner. e-means falls into the same arrangement, then climbs out around epoch 10. Over 200 starts Lloyd stays stuck more than 1% worse on 43% of starts, while e-means is more than 1% worse on 4%. Lloyd (full batch) e-means (mini-batches of 256) training MSE Four blobs on a square around a heavier centre blob, k = 5. Lloyd puts two centroids on one corner blob and strands one in the gap between two others, which then share it. e-means, from the same start, gives every blob one. Over 200 starts Lloyd stays stuck on 15.5% of starts, while e-means stays stuck on 0%. Lloyd (full batch) e-means (mini-batches of 256) training MSE Five blobs on a line, k = 5. Lloyd leaves a light middle blob without a centroid and gives an end blob two. e-means, from the same start, gives every blob one. Over 200 starts Lloyd stays stuck on 46% of starts, while e-means stays stuck on 0%.
Our explanation for that is that mini-batches provide more noisy updates that are more likely to explore the optimization landscape and escape local minima. Lloyd, with its always decreasing loss, is more likely to exploit found local minima and never escape them.
Automatic hyperparameter tuning with scaling laws
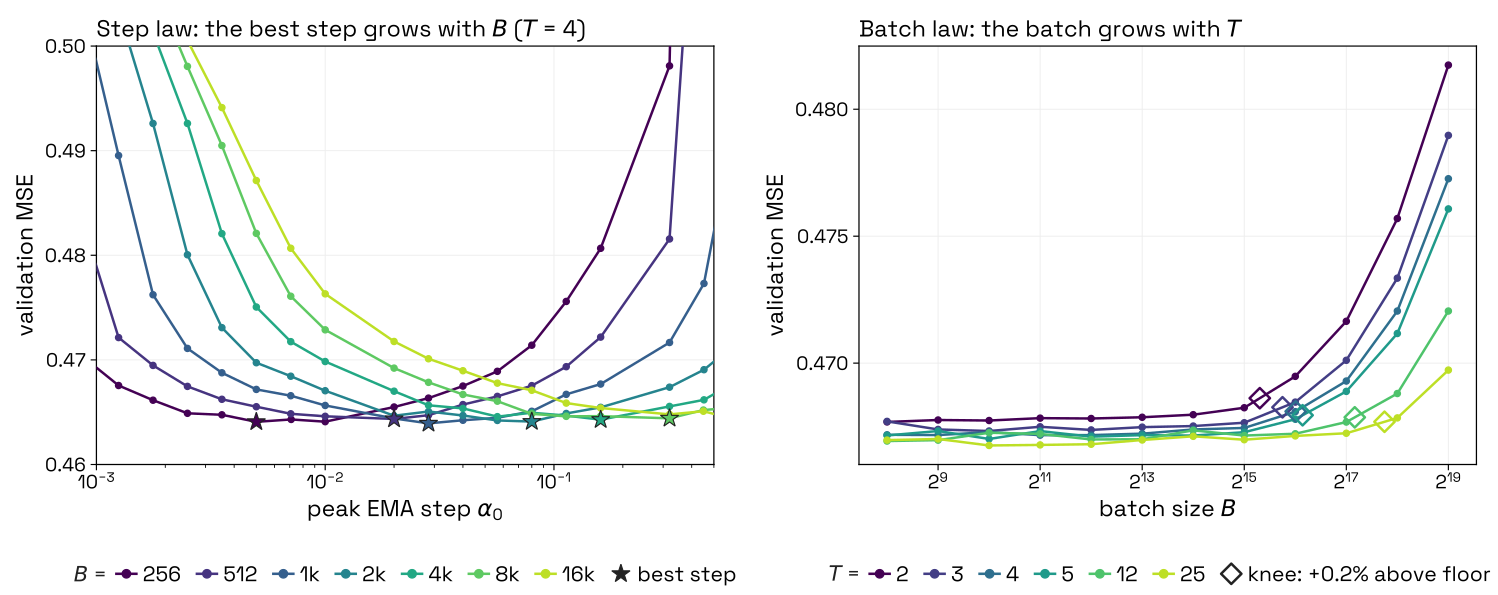
An essential property of e-means is that practitioners don't need to set any additional hyperparameter compared to Lloyd's algorithm. We fitted two scaling laws to set the batch size B and step size α0 from any problem's characteristics (n, k, T), and found them to exhibit strong generalization on unseen datasets and problem scales.
[ B = c_B , k^{b_k} , n^{b_n} , T^{b_T} ] [ \alpha_0 = \min!\Big(c_\alpha , k^{a_k} , B^{a_B} , n^{a_n} , T^{a_T},; 1\Big) ]
| law | constant | exponent of | regret, held-out datasets | regret, held-out size | R² |
|---|---|---|---|---|---|
| k | B | n | T | ||
| step α0 | 0.824 | −0.46 | 0.90 | −0.45 | −0.11 |
| batch B, default | 0.035 | 0.13 | n/a | 0.88 | 0.81 |
| batch B, quality law | 0.0044 | 0.13 | n/a | 0.88 | 0.81 |
Regret = (MSE with the law − best MSE over the grid) / best MSE, median over configurations. Held-out datasets: SIFT, SPACEV, and the VIBE[9] datasets arXiv and AG-News. Held-out size: one value of n left out of the fit and predicted.
We propose two equations to choose the batch, the default law and the quality law. The “quality law” trades off throughput for better clustering quality against the “default” law. Below we plot the training data for our scaling laws: validation MSE against step size α0 (left) and batch size B (right).
The importance of dead-cluster revival
Revival off dead clusters: 0 of 25 Revival on (e-means) dead clusters: 0 of 25 centroid dead cluster (no points) cluster boundaries epochs: 0.00 · update 0 of 157
Toy example showing the importance of dead-cluster revival.
The main issue with mini-batch k-means is that it is prone to “dead” clusters, centroids that end up with zero assigned points during optimization. This reduces the effective size of the codebook, which is especially problematic for the large codebooks increasingly used today.
A common mitigation is to reinitialize clusters that fall below a certain size threshold, as done in EnCodec[10], where dead centroids are simply replaced by random samples drawn from the incoming batch. While this helps, it does not fully resolve the issue. Instead of sampling arbitrary points from the batch, we revive dead clusters by splitting large, existing ones: we sample an active cluster with probability proportional to its size and split it into two. We found this approach, adapted from Faiss k-means, to be significantly more effective at eliminating dead clusters and preserving codebook capacity.
| dataset | revival policy | dead clusters | of codebook | imbalance | test MSE |
|---|---|---|---|---|---|
| DEEP | proportional split | 47 | 0.3% | 1.194 | 0.38762 |
| resample from batch (EnCodec) | 2,343 | 14.3% | 1.423 | 0.39124 | |
| off | 4,313 | 26.3% | 1.647 | 0.39448 | |
| SIFT | proportional split | 10 | 0.1% | 1.186 | 0.19623 |
| resample from batch (EnCodec) | 750 | 4.6% | 1.233 | 0.19684 | |
| off | 2,080 | 12.7% | 1.404 | 0.19797 |
1 million vectors, k = 16,384, 5 epochs, mean over 5 seeds; only the revival policy varies. A cluster counts as dead when fewer than ten vectors are assigned to it at the end, a thousandth of an average cluster. Imbalance: how uneven the cluster sizes are (1 = all equal). From the paper’s revival ablation table.
Extensive experimental validation
We validated e-means on 24 different embedding and synthetic datasets and configurations (see paper). For the video we ran 234 configurations of e-means against k-means (16 datasets, 100k to 100M points): explore every curve in the results map.
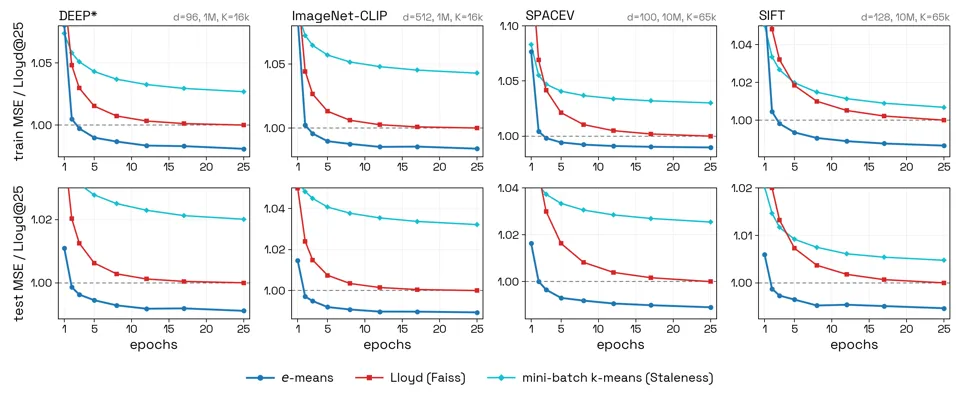
Train (top) and test (bottom) MSE, divided by Lloyd’s after 25 epochs. Initialized from random vectors.
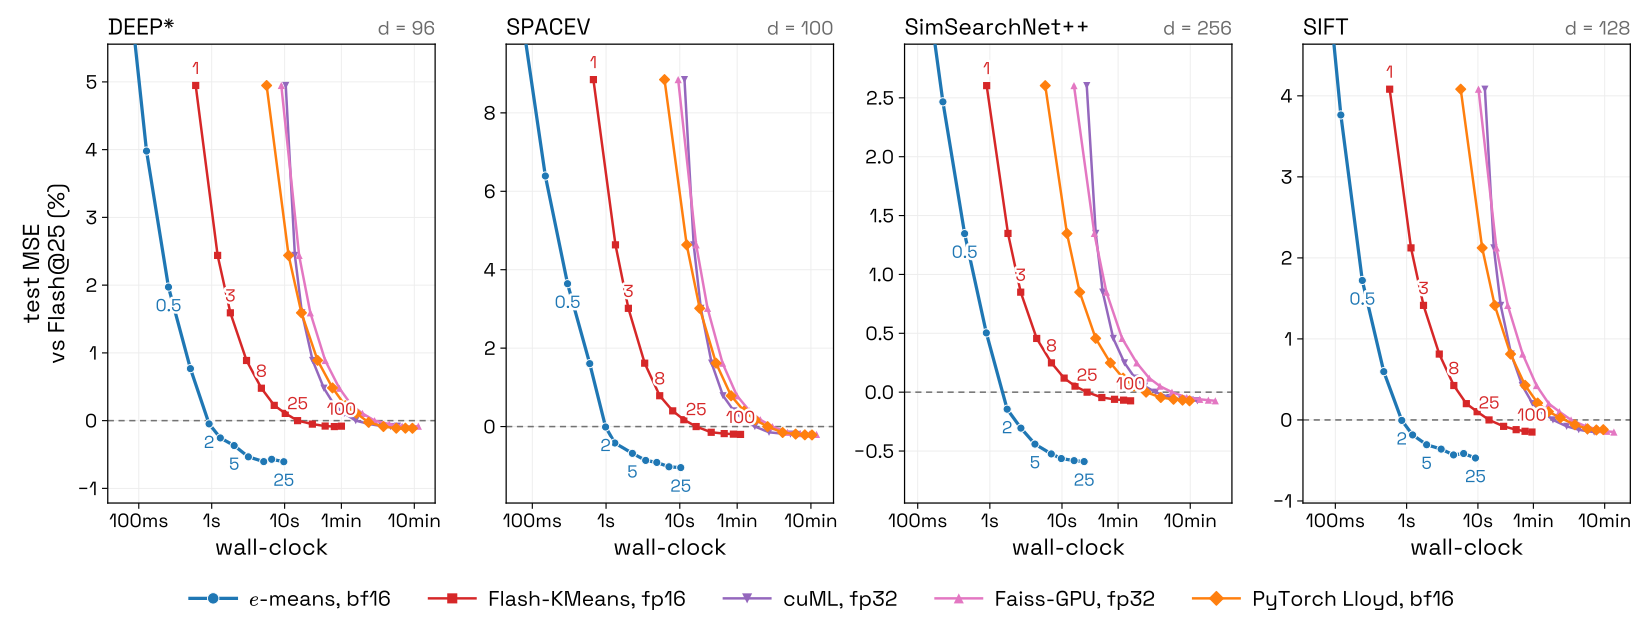
Test MSE against wall-clock time on one H100, 10 million vectors, 65,536 clusters. 25 epochs of a plain PyTorch Lloyd (data on the GPU, bf16) take 142 to 155 seconds, against 14 to 22 seconds for Flash-KMeans[2]. Labels on the curves mark the number of epochs.
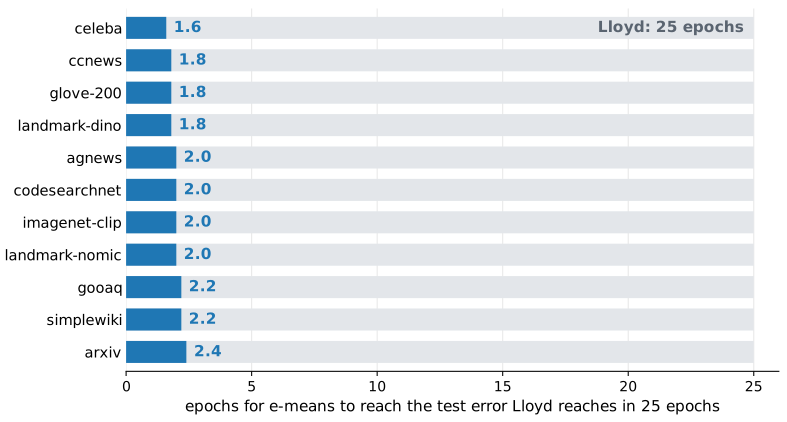
Epochs e-means needs to reach the test error Lloyd reaches in 25 epochs, on the 11 datasets of the VIBE embedding benchmark (text, code, image and multimodal embeddings, d = 200 to 3,072, k = 8,192 or 16,384). Budgets spaced 0.2 epochs apart, median over five seeds. Every dataset needs between 1.6 and 2.4 epochs, against Lloyd’s 25.
Library and code
from faiss.contrib.e_means import Emeans # NumpyEmeans for NumPy em = Emeans(d, k, nepochs=T) # T epochs (5 by default) centroids, labels = em.train(x) # x: a PyTorch tensor (n, d) # labels: each vector's cluster in the last epoch
Repo: faiss/contrib/e_means.
Citing this work
If you use e-means, please cite the paper (arXiv.09501):
@misc{bessa2026emeansoutperformingkmeansin, title={e-means: outperforming k-means (in one-tenth the epochs)}, author={Swann Bessa and Pierre-Emmanuel Mazaré and Gergely Szilvasy and Hugo Touvron and David Picard and Matthijs Douze and Hervé Jégou}, year={2026}, eprint={2611.09501}, archivePrefix={arXiv}, primaryClass={cs.LG}, url={https://arxiv.org/abs/2611.09501}, }