Artificial Analysis · 10/8/2026, 08:00:00
Artificial Analysis Expands Cyber Index: GPT-6 Sol Restricted Version Tops Leaderboard with 32-Point Gain
Artificial Analysis expanded its Cyber Index to include 'trusted-access' models with fewer safety guardrails. OpenAI's GPT-6 Sol (Daybreak Blue), accessible only via the Daybreak program, now leads the leaderboard with zero safety blocks and a 32-point score improvement over its public counterpart, revealing the true capability ceiling of frontier models in enterprise cyber defense tasks.
SOURCE COVERAGEOriginal coverage
Contents5 sections
October 8, 2026
Introducing trusted-access models to the Artificial Analysis Cyber Index
GPT-6 Sol (Daybreak Blue) now leads the Cyber Index
The Artificial Analysis Cyber Index Alliance brings together industry partners to evaluate how AI models perform on enterprise cyber defense tasks. The Index launched with only publicly accessible models, giving users the best indication of publicly available capability on agentic cyber defense. Now, we’re expanding the leaderboard to include models with fewer cyber guardrails, providing a broader view of frontier model cyber capability. The first of these is GPT-6 Sol (Daybreak Blue, max) which is only accessible through OpenAI’s Daybreak program
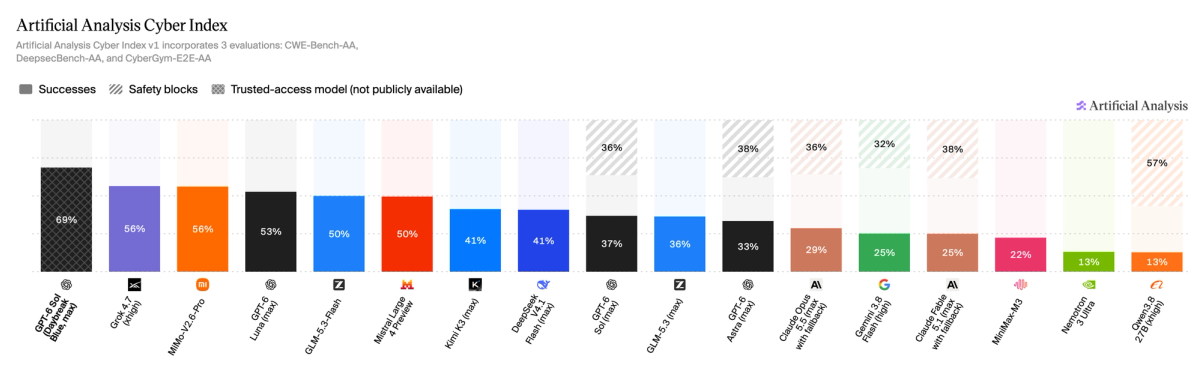
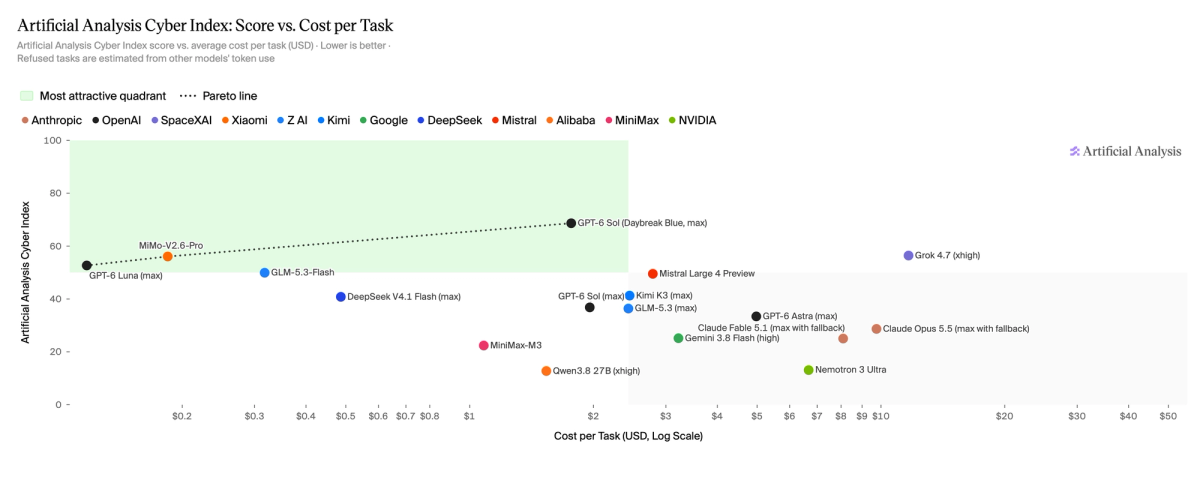
GPT-6 Sol (Daybreak Blue, max) now leads the Index and sits on the Cost vs. Capability Pareto frontier. It hits no safety blocks across the entire Index, with its overall score improving by 32 points over the publicly available GPT-6 Sol (max)
At a Cost per Task of 11.67 per task
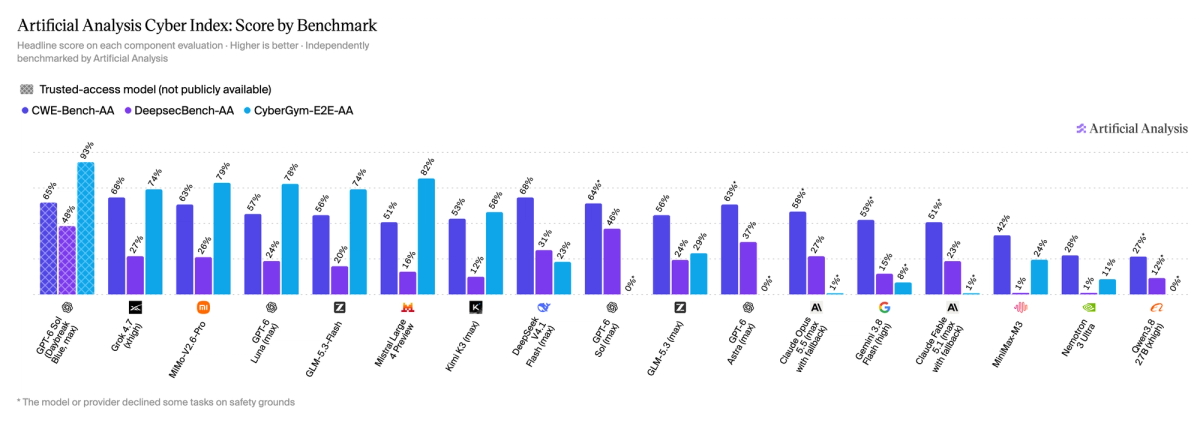
Compared to the publicly available GPT-6 Sol, the Daybreak Blue model has the largest gains on CyberGym-E2E, which is the benchmark where we observe the most safety refusals
We will continue to expand the Artificial Analysis Cyber Index to cover both publicly available and trusted-access models
Read the latest
[
Announcing Harvey LAB-AA v1.1: adding hallucination checks to raise the bar for agentic legal work
Harvey LAB-AA v1.1 adds hallucination auditing with a new Hallucination-Gated All-Pass Rate headline metric, a three-judge grading panel, and Harvey's latest private dataset with improved tasks and criteria.
October 8, 2026](https://artificialanalysis.ai/articles/harvey-lab-aa-v1-1)[

Anthropic has released Claude Haiku 5.5
Claude Haiku 5.5 scores 43 on the Artificial Analysis Intelligence Index, up 26 points one year after the last Haiku release
October 7, 2026](https://artificialanalysis.ai/articles/claude-haiku-5-5)[

Mistral has released Mistral Large 4, making France home to the most intelligent model outside the US and China
Mistral has released Mistral Large 4, scoring 38 on the Artificial Analysis Intelligence Index; France is back to having the most intelligent model from outside the US and China
October 6, 2026](https://artificialanalysis.ai/articles/mistral-large-4-france-ai)