Rohan Paul (@rohanpaul_ai) · 10/21/2026, 08:47:39
EAGLE-4 Released: Speculative Decoding Hits 961 Tokens/s
EAGLE-4, the latest speculative decoding accelerator, achieves 961.6 tokens/s on a single request using Qwen3.8-27B. By optimizing the draft model structure and reducing LM Head costs, it significantly boosts generation efficiency while maintaining output consistency, marking a key advancement in LLM inference optimization.
SOURCE COVERAGEFull Original Report
Rohan Paul (@rohanpaul_ai) · 2026-10-21 00
Some of the most useful inference work right now is happening in the speculative decoding component.
It has become one of the most dependable ways to get more tokens per second out of a model you’ve already chosen.
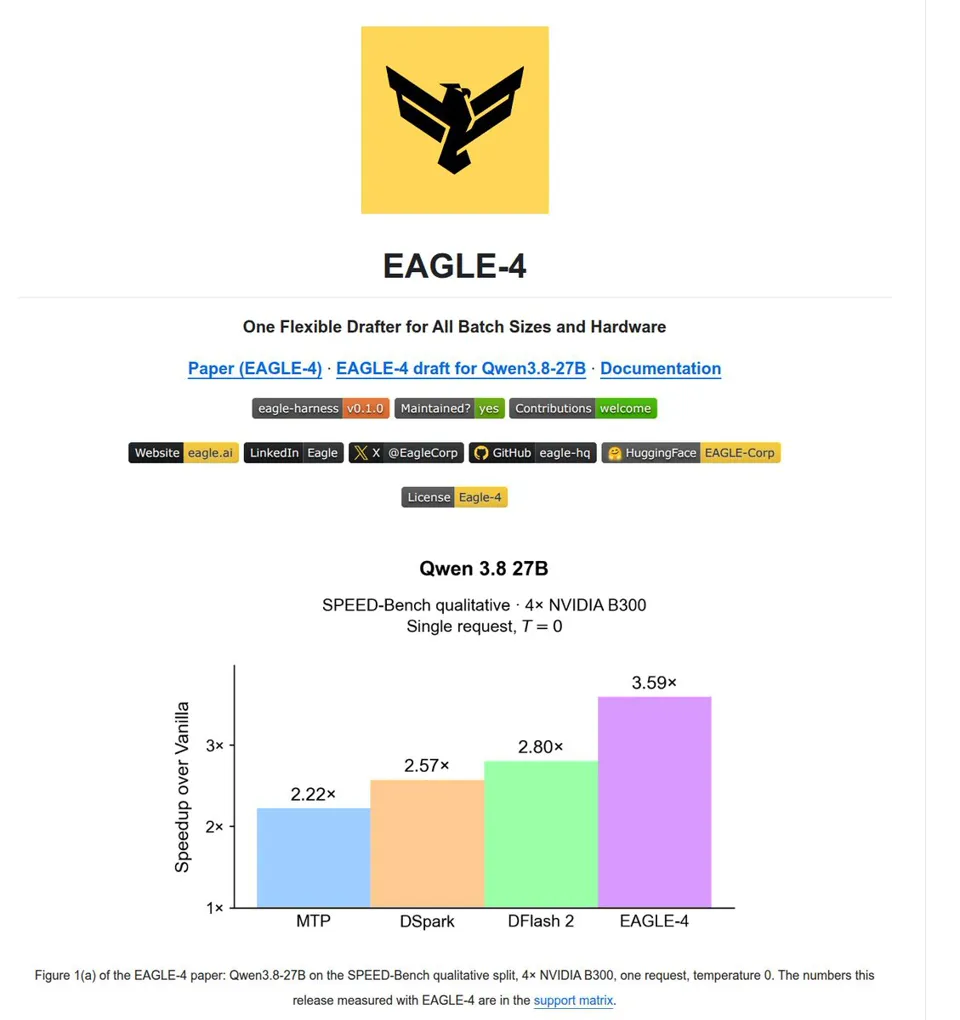
EAGLE-4 decodes 863.8 tokens/s on a 27B model on a single request, 1.28X DFlash 2 and 1.40X DSpark.
EAGLE-4 is a speed-up add-on for running AI chatbots: a tiny helper model guesses the next few words, and the big model checks all those guesses at once instead of writing one word at a time. The answers come out identical, just about 3× faster on the tested setup.
EAGLE-4 keeps the draft-and-verify loop and puts its work into the drafting side, with an adaptive draft structure and a cheaper draft LM head.
The loop:
- A small draft model proposes several tokens ahead
- The target model checks all of them in one forward pass
- Matching tokens are kept, and the first mismatch is replaced with the target’s own token
- Repeat from there
↳ 引用 @EagleCorp (Eagle): EAGLE-4 is here.
From EAGLE-1 to EAGLE-3, we’ve kept making inference faster.
EAGLE-4 is our fastest yet.
961.6 tokens/s on @Alibaba_Qwen’s Qwen3.8-27B with TokenSpeed (BF16, 4× @NVIDIA B300, TP4, one request, T=0).