Amazon Paper Finds Rule-Following AI Benchmarks Riddled with Answer-Key and Scorer Bugs
A new Amazon paper audited nine public rule-following benchmarks such as RuleArena and LegalBench and found that their reference answers and grading code contain errors, causing correct model responses to be marked wrong. In LegalBench's tax scorer, decimal points were stripped, turning $259,487.13 into 25,948,713; after the fix, three models' accepted answers rose from 8-9 out of 96 to 87-91. The authors urge checking scorer code and hand-reviewing failed answers before trusting low scores.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-11-08 21
New Amazon paper finds that benchmarks used to grade AI models on tax, legal and business rules often mark correct answers wrong, because the tests’ own answer keys or grading code contain mistakes.
Benchmarks like RuleArena and LegalBench test whether models apply written rules to tax, legal, and business cases. If the reference answer or the scorer is wrong, the score measures the benchmark's bugs, not the model.
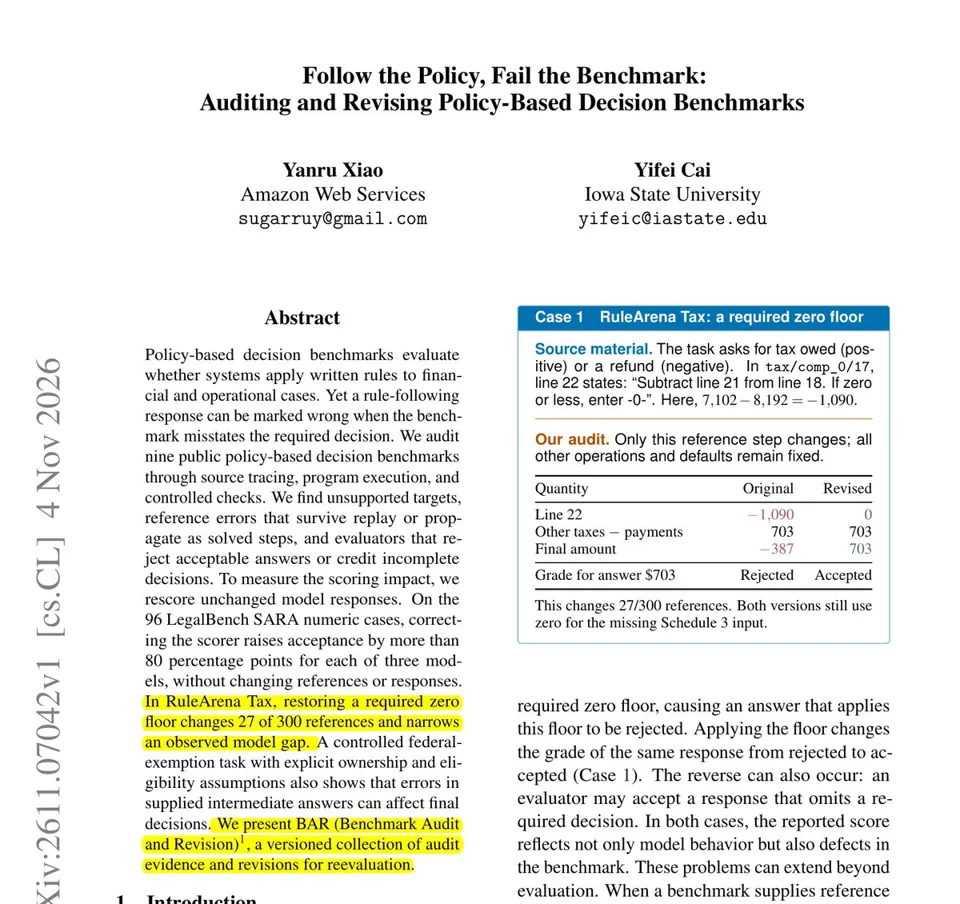
They audited 9 public benchmarks by tracing references back to the source rules, rerunning reference programs, and testing scorers with controlled answers. Then they rescored the same saved model responses after each fix.
LegalBench's tax scorer deleted decimal points, so $259,487.13 was read as 25,948,713. Fixing it raised accepted answers from 8 or 9 to between 87 and 91 out of 96 for each of 3 models.
Before trusting a low score on a rule-following benchmark, read the scorer code and check a few failed answers by hand.