亚马逊论文发现规则类基准答案键与评分代码普遍出错
亚马逊一篇新论文审计了 9 个公开的规则遵循类基准(如 RuleArena、LegalBench),发现其参考答案与评分代码本身存在错误,导致模型正确答案被误判。以 LegalBench 税务评分为例,评分器删除小数点,把 259,487.13 美元读成 25,948,713,修复后 3 个模型的通过数从 8-9/96 升至 87-91/96。作者建议在看到低分时先读评分代码并人工抽查失败样本。
报道正文
Rohan Paul (@rohanpaul_ai) · 2026-11-08 21
New Amazon paper finds that benchmarks used to grade AI models on tax, legal and business rules often mark correct answers wrong, because the tests’ own answer keys or grading code contain mistakes.
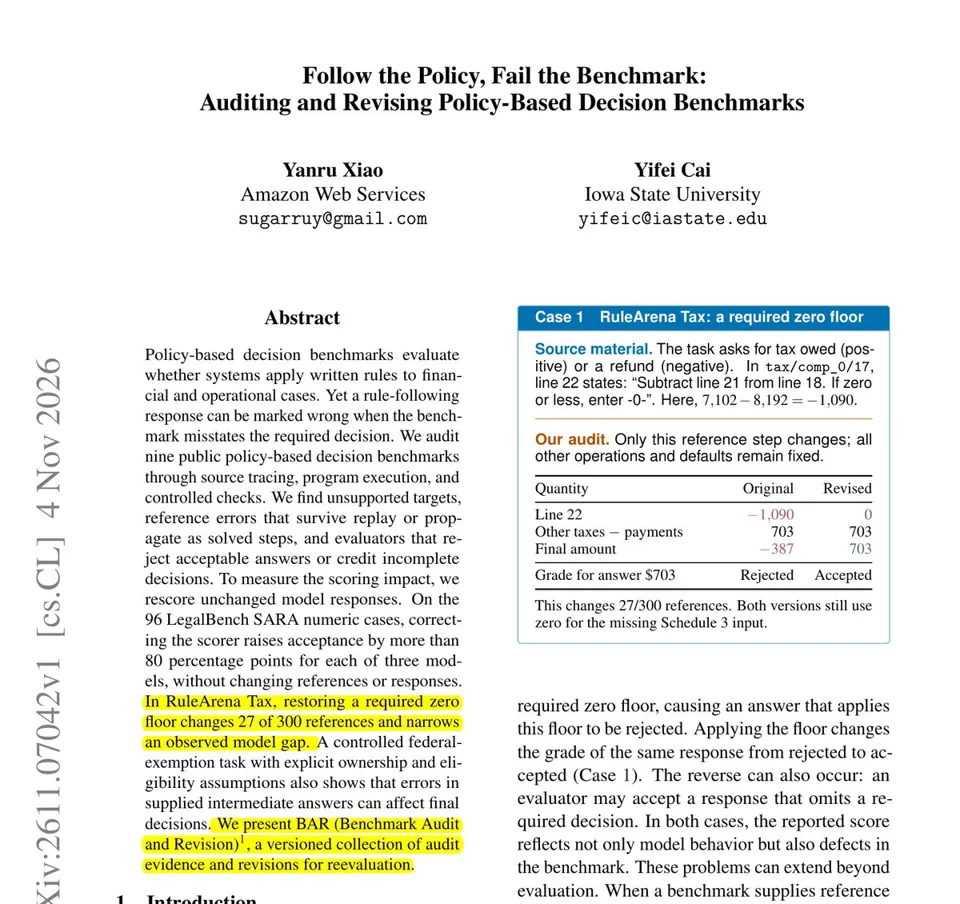
Benchmarks like RuleArena and LegalBench test whether models apply written rules to tax, legal, and business cases. If the reference answer or the scorer is wrong, the score measures the benchmark's bugs, not the model.
They audited 9 public benchmarks by tracing references back to the source rules, rerunning reference programs, and testing scorers with controlled answers. Then they rescored the same saved model responses after each fix.
LegalBench's tax scorer deleted decimal points, so $259,487.13 was read as 25,948,713. Fixing it raised accepted answers from 8 or 9 to between 87 and 91 out of 96 for each of 3 models.
Before trusting a low score on a rule-following benchmark, read the scorer code and check a few failed answers by hand.