NVIDIA Method Caches LLM Reasoning as CPU Code to Cut Costs 291x
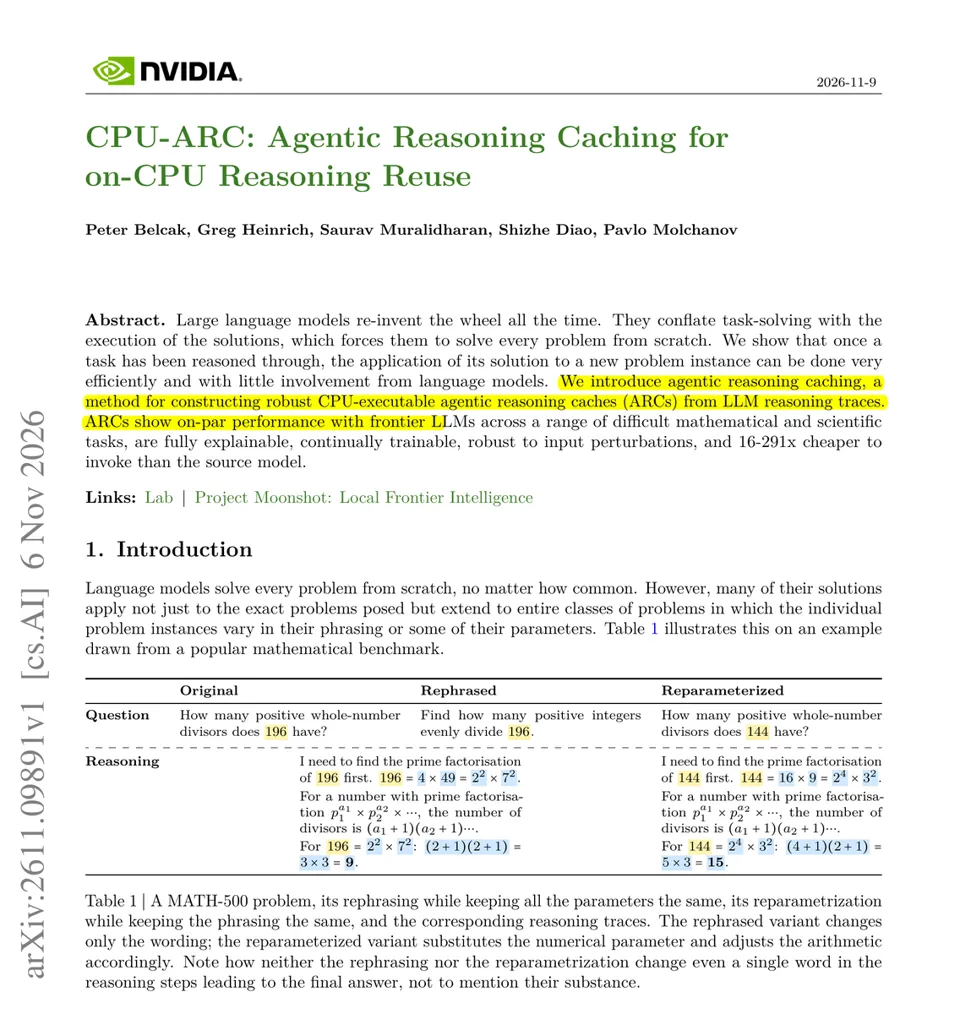
An NVIDIA paper proposes compiling an LLM's reasoning trace into small parameterized Python functions that run on CPU, invoking a fine-tuned 1B model only for lightweight text tasks such as value extraction. The cache matched or beat the source model on 7 of 8 math and science benchmarks, scoring 93.3% versus 83.3% on AIME '25, and covered at least 90% of rephrased or re-numbered variants at 16x to 291x lower cost.
Full Report
Rohan Paul (@rohanpaul_ai) · 2026-11-21 16
New NVIDIA paper finds that once an LLM has reasoned through a problem, the solution can run as CPU code for rephrased and re-numbered versions of it.
that answers similar questions 16x to 291x cheaper.
LLMs re-solve every problem from scratch, even when only wording or numbers change. Agents sending the same instructions with new data pay for that repeated reasoning each time.
Their method has Claude Opus 4.5 turn a reasoning trace into small Python functions, with changeable inputs as parameters. At run time they execute on a CPU, calling a fine-tuned 1B model only for small text jobs like extracting values.
The cache matched or beat the source model's accuracy on 7 of 8 math and science benchmarks, scoring 93.3% versus 83.3% on AIME '25. It handled at least 90% of rephrased or re-numbered variants.
If your agent runs the same prompt on new inputs all day, cache the reasoning as code and use the LLM only on misses.