Artificial Analysis (@ArtificialAnlys) · 10/21/2026, 23:53:56
MLCR-AA Update: Claude Sonnet 5.5 and GPT-6 Astra Tie for Top Medical Reasoning Score
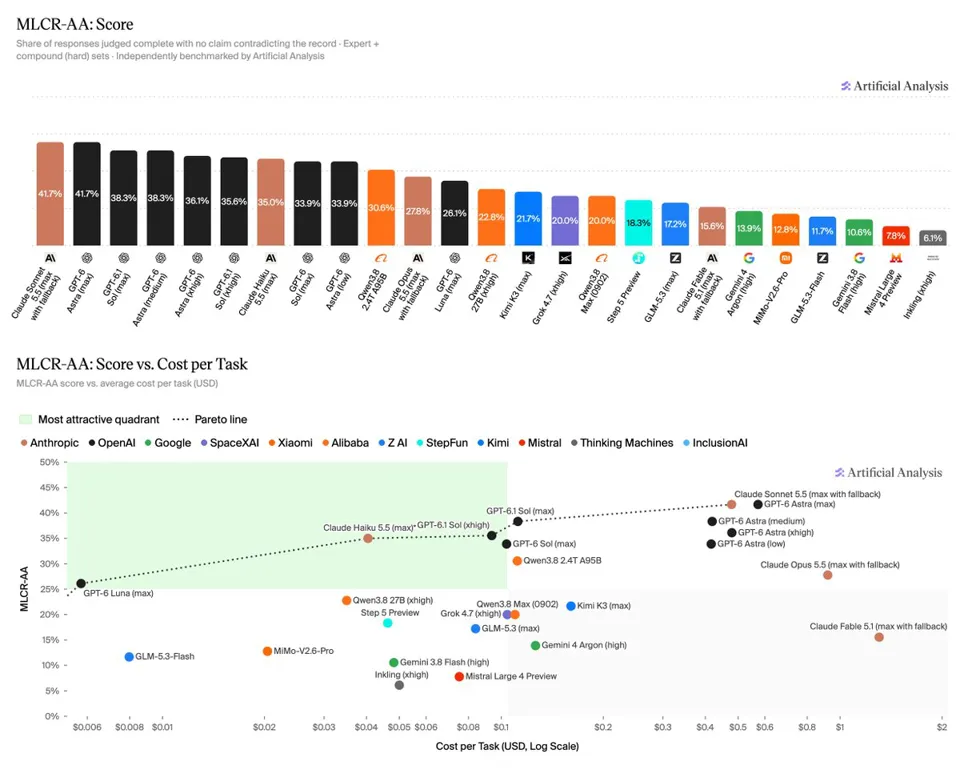
Artificial Analysis updated the MLCR-AA leaderboard with refined prompts and a three-model judge panel to better reflect real-world medical record review. Claude Sonnet 5.5 and GPT-6 Astra tied for first place with a 41.7% pass rate, yet results indicate that medical long-context reasoning remains far from solved, with median models passing under 15%. Qwen3.8 2.4T A95B leads among open-weight models.
SOURCE COVERAGEFull Original Report
Artificial Analysis (@ArtificialAnlys) · 2026-10-21 15
We've updated MLCR-AA, our leaderboard for Wisedocs' Medical Long Context Reasoning benchmark, with Claude Sonnet 5.5 and GPT-6 Astra now tied for the #1 score
We've updated how MLCR-AA prompts and grades models on @wisedocsai's benchmark, to better reflect how medical record review is done in practice. Models are now prompted as medical record reviewers, and asked to answer each part of a question in one paragraph with their conclusion and the supporting evidence from the record. Answers are graded by a new three-model judge panel, and we reviewed all 60 expert reference answers against their source records, refining 15.
Claude Sonnet 5.5 (max with fallback) from @AnthropicAI and GPT-6 Astra (max) from @OpenAI are tied at the top with 41.7%, followed by GPT-6.1 Sol (max) at 38.3%. Qwen3.8 2.4T A95B from @Alibaba_Qwen is the leading open weights model at 30.6%.
Key results from the updated MLCR-AA:
➤ Medical record review remains far from solved: an answer passes only when it is both complete and accurate, and no model passes more than 42% of questions and the median model passes under 15%
➤ Anthropic models lead on completeness, reaching the expert's conclusion with the right medical reasoning: Claude models hold the top 18 completeness scores across every model and effort level we tested, led by Claude Sonnet 5.5 (max with fallback) at 64.8%. The best non-Anthropic model is GPT-6 Astra (max) at 42.2%
➤ OpenAI models lead on accuracy, citing the record without exaggeration or hallucination: OpenAI models hold the top 27 accuracy scores, led by GPT-6.1 Sol (max) at 96.7%, but answer fewer questions completely: GPT-6.1 Sol (max) is complete on 40.0% of questions
We would like to thank Wisedocs for building MLCR and for their collaboration in bringing it to Artificial Analysis