Alibaba Launches 2.4T-Parameter Qwen4-Max, Cutting Task Costs Over 60%
Alibaba's Qwen team has officially launched Qwen4-Max, a 2.4-trillion-parameter sparse MoE flagship with native vision understanding and a 1M-token context window, claiming over 60% lower task cost at comparable performance. The model introduces systematic architectural changes including Gated DeltaNet, Qwen Sparse Attention, Gated Residual and N-gram Embedding, targeting long-horizon professional work in office, coding and research, and is now available via QwenCloud API with smaller open-source variants to follow.
Related Entities
Full Report
IT之家 November 16 news: The Alibaba Tongyi Qianwen team today announced the launch of its new-generation flagship model Qwen4-Max, which adopts a brand-new MoE (Mixture of Experts) architecture, with a backbone parameter scale reaching 2.4 trillion, native support for visual understanding, and a 1-million-token context window.
Unlike the limited-time preview version that was first opened on November 11, this release marks Qwen4-Max's official integration into the Qianwen AI platform as a formal version, and developers can access it via Token Plan or API calls.
Qwen4-Max adopts a sparse MoE architecture and has made systematic adjustments across three levels: Attention, Residual, and Embedding. In every four layers, three use Gated DeltaNet to compress historical information into a fixed state, while the remaining layer uses Qwen Sparse Attention to select relevant context at block granularity, thereby reducing the attention computation overhead for long sequences; Gated Residual expands the residual stream into four parallel branches to enhance cross-layer information transfer; and N-gram Embedding provides local token pattern representations via table lookup at the second layer, expanding model capacity with relatively low additional compute.
According to the official statement, the new model, while improving its ability to handle complex work tasks, can reduce token consumption and lower task costs.
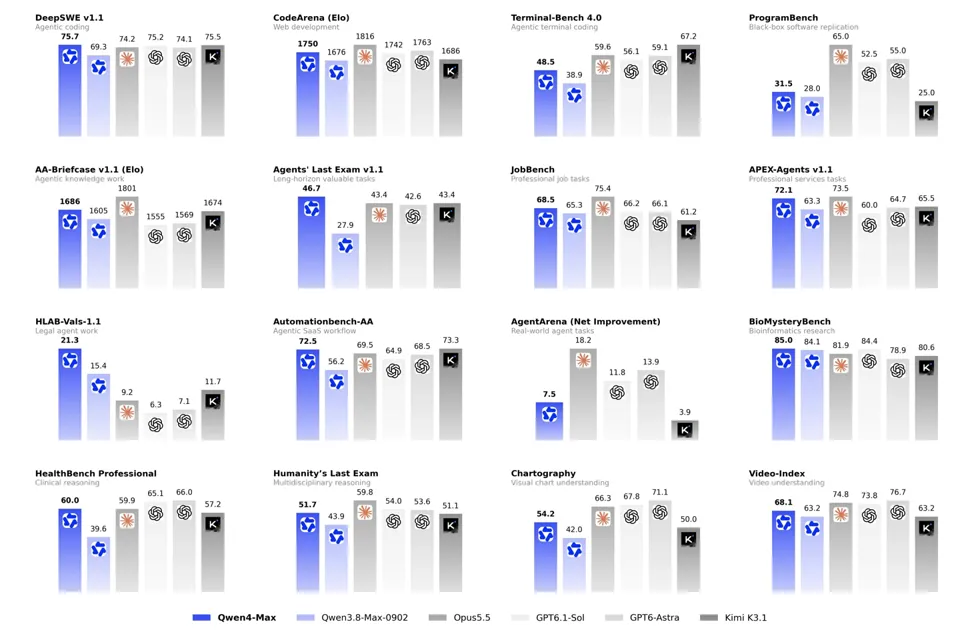
▲ Comprehensive performance comparison for programming, office work, and long-horizon tasks. Compared with Qwen3.8-Max, Qwen4-Max shows significantly improved overall capabilities.
According to the official Qwen blog, Qwen4-Max targets scenarios such as office productivity, creative writing, software development, and scientific research, with a focus on improving professional tool use, long-cycle task execution, and final delivery quality. The model can handle tasks in 3D modeling, game development, industrial manufacturing, finance, law, healthcare, and frontier scientific research.
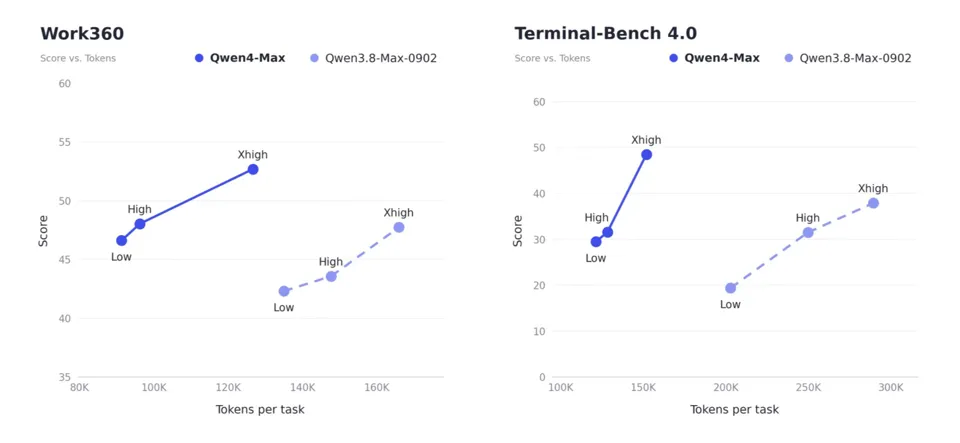
Efficiency is a prominent indicator of this upgrade. Qwen4-Max scored 52.69 on the Work360 industry benchmark, compared with 47.74 for the previous generation Qwen3.8-Max.
At equivalent performance, token consumption at the Xhigh and High reasoning effort levels decreased by about 24% and 35% respectively compared with the previous generation; on Terminal-Bench 4.0, the token consumption reductions reached about 48% and 49%. API pricing has also been lowered accordingly, especially with a substantial reduction in the cache-hit price. In the Work360 evaluation, the average cost per task dropped from 26.58 yuan to 11.16 yuan, a decrease of 58%.
To evaluate the model's performance in real work scenarios, the Qwen team also developed the Work360 evaluation framework to simulate and categorize complex professional work tasks. IT之家 notes that the framework covers 26 primary domains, 182 secondary subdomains, and 721 tertiary professional directions, involving workflows across a variety of industries and occupations.
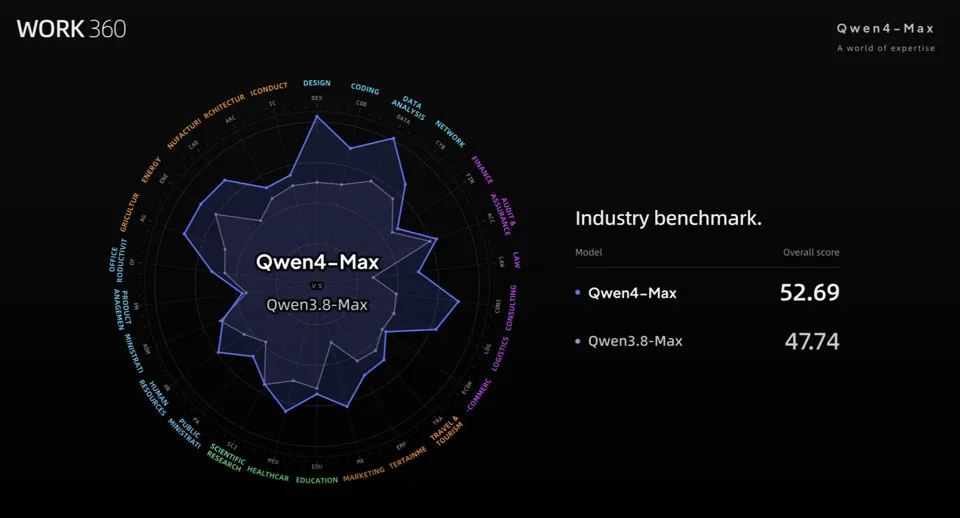
The model's capabilities are skewed toward long-horizon task execution. Qwen4-Max supports a million-token context window and native visual input, and introduces the Live Delivery mechanism in agent scenarios: first deliver a usable initial version, then progressively expand content and quality based on user feedback. The Qwen-Live-Delivery-Plugin has also been open-sourced.
The officially showcased cases cover Blender 3D modeling, game development with the Unity and Unreal engines, automotive production line planning and part machining programming, as well as professional scenarios such as financial investment research, legal due diligence, and critical care clinical assistance. In the automotive part machining case, the manual effort for programming a single workpiece dropped from about 475 minutes to 24 minutes.
Qwen4-Max is the first model in the Qwen4 series. According to the official statement, smaller models in the series will be open-sourced successively, following the same technical roadmap while making trade-offs for scenarios where smaller models are more suitable.
Currently, the Qwen4-Max API is available on QwenCloud, and developers can integrate it via API. In addition, users can experience the new model through Qwen Studio, QwenWork, and Qoder.
References: