Rohan Paul (@rohanpaul_ai) · 10/12/2026, 23:39:55
Nvidia Proposes New Base Model Agent Evaluation: Scoring Only the First Passing Edit Yields 0.964 Correlation with SWE-bench
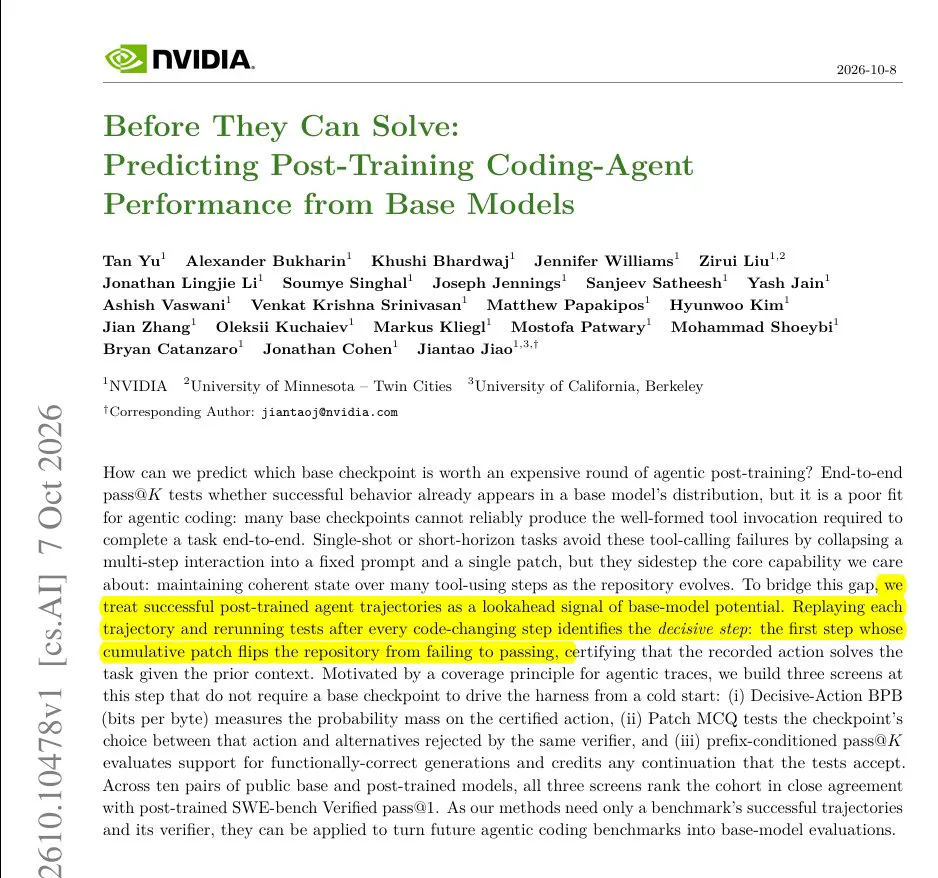
A new Nvidia paper reveals that scoring base models at every step of an agent run is ineffective, whereas evaluating them only on the specific edit that first makes tests pass accurately predicts post-training performance. By replaying successful trajectories to identify this decisive step, the method achieves a 0.964 rank correlation with SWE-bench Verified scores, offering a low-cost way to select base models for agentic fine-tuning.
SOURCE COVERAGEFull Original Report
Rohan Paul (@rohanpaul_ai) · 2026-10-12 15
New Nvidia paper shows scoring base models on every step of an agent run works worse than scoring them only on the edit that first makes the tests pass.
Post-training is expensive, so picking the right base model matters. Yet agent benchmarks score base models near zero, and simple coding tests barely predict later agent skill.
They replay a strong agent's successful run and rerun the tests after each edit to find the 1st edit that makes them pass. At this decisive step they test whether a base model favors that edit, picks it over failing edits, and can write a passing one.
How likely each base model was to write that exact edit ranked the same 10 models in line with their post-trained SWE-bench Verified scores, at 0.964.
When choosing a base model to post-train for agent work, run this check first. It needs only a benchmark's successful agent runs and its tests.