IT之家 · 智能时代 · 10/13/2026, 17:12:15
OpenBMB Releases MiniCPM-V 4.7: First On-Device MoE Multimodal Model Achieving 13+ Tokens/s on 3GB RAM
OpenBMB released MiniCPM-V 4.7, a new on-device multimodal LLM available in 35B-A3B and 1B variants. The 35B-A3B version is the first Mixture-of-Experts model in the series, leveraging LES inference acceleration to achieve over 13 tokens/s decoding speed with only 3GB of memory usage, drastically lowering deployment barriers for high-performance models. Additionally, OpenBMB open-sourced the Self-Replay Fine-Tuning (SRFT) method and ensured compatibility across major chip platforms including Intel, AMD, Arm, and Rockchip.
SOURCE COVERAGEFull Original Report
October 13 — ModelBest announced the launch of its new generation on-device multimodal large model, MiniCPM-V 4.7, available in two specifications: 35B-A3B and 1B. Notably, the 35B-A3B variant is the first MoE (Mixture of Experts) model in the MiniCPM-V series.
According to official information, this model leverages the latest LES (Lookahead Expert Scheduling) inference acceleration technology. The 35B-A3B version is the first open-source MoE model capable of running smoothly and losslessly on edge devices, achieving a decoding speed of 13+ tokens/s with only 3GB of memory.
IT Home reports that MiniCPM-V 4.7 supports iOS, Android, and HarmonyOS, and is adapted for chip platforms including Intel, AMD, Arm, Rockchip, and Houmo, covering a wider range of mobile devices and local computing scenarios. Additionally, the Self-Replay Fine-Tuning (SRFT) method has been open-sourced simultaneously, helping developers expand model capabilities at low cost while mitigating catastrophic forgetting, thereby facilitating secondary development.
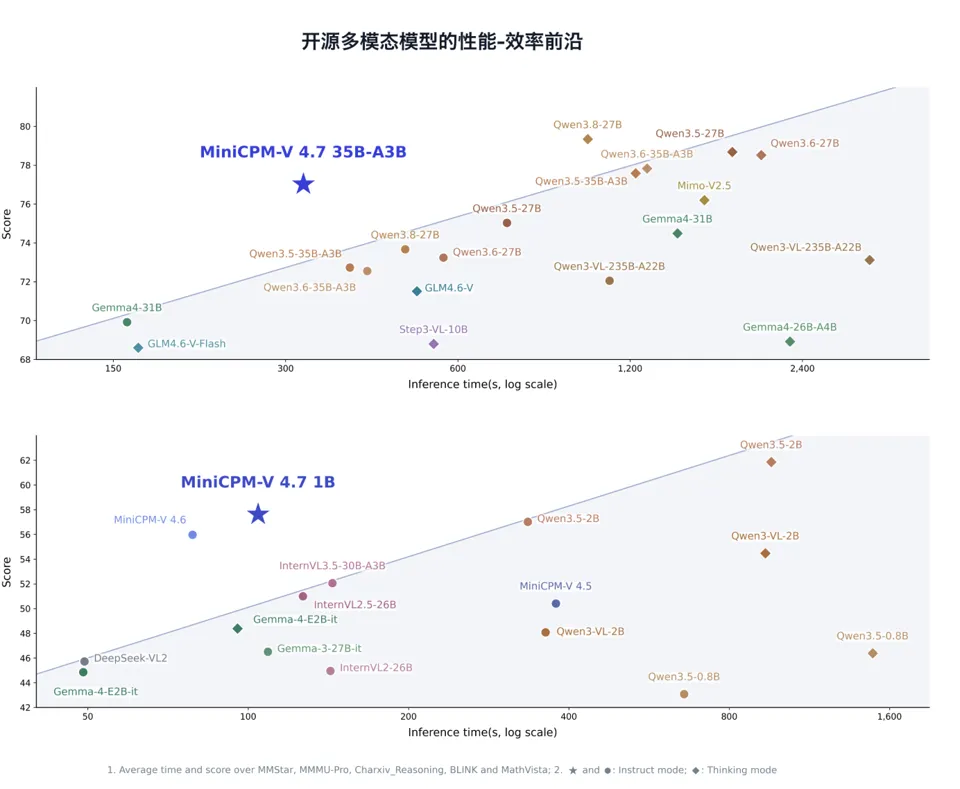
Furthermore, in Instruct mode, the 35B-A3B version achieves higher overall scores than Qwen3.6 35B-A3B with shorter inference times. The 1B version continues to improve upon MiniCPM-V 4.6's foundational capabilities, significantly outperforming Qwen3.5 0.8B in both overall score and inference efficiency.
Reference: